iidasspt.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-28
Readiness 100/100
See also independent and identically distributed data point random variable empirical risk minimization training set validation set distribution shift hypothesis space decision tree
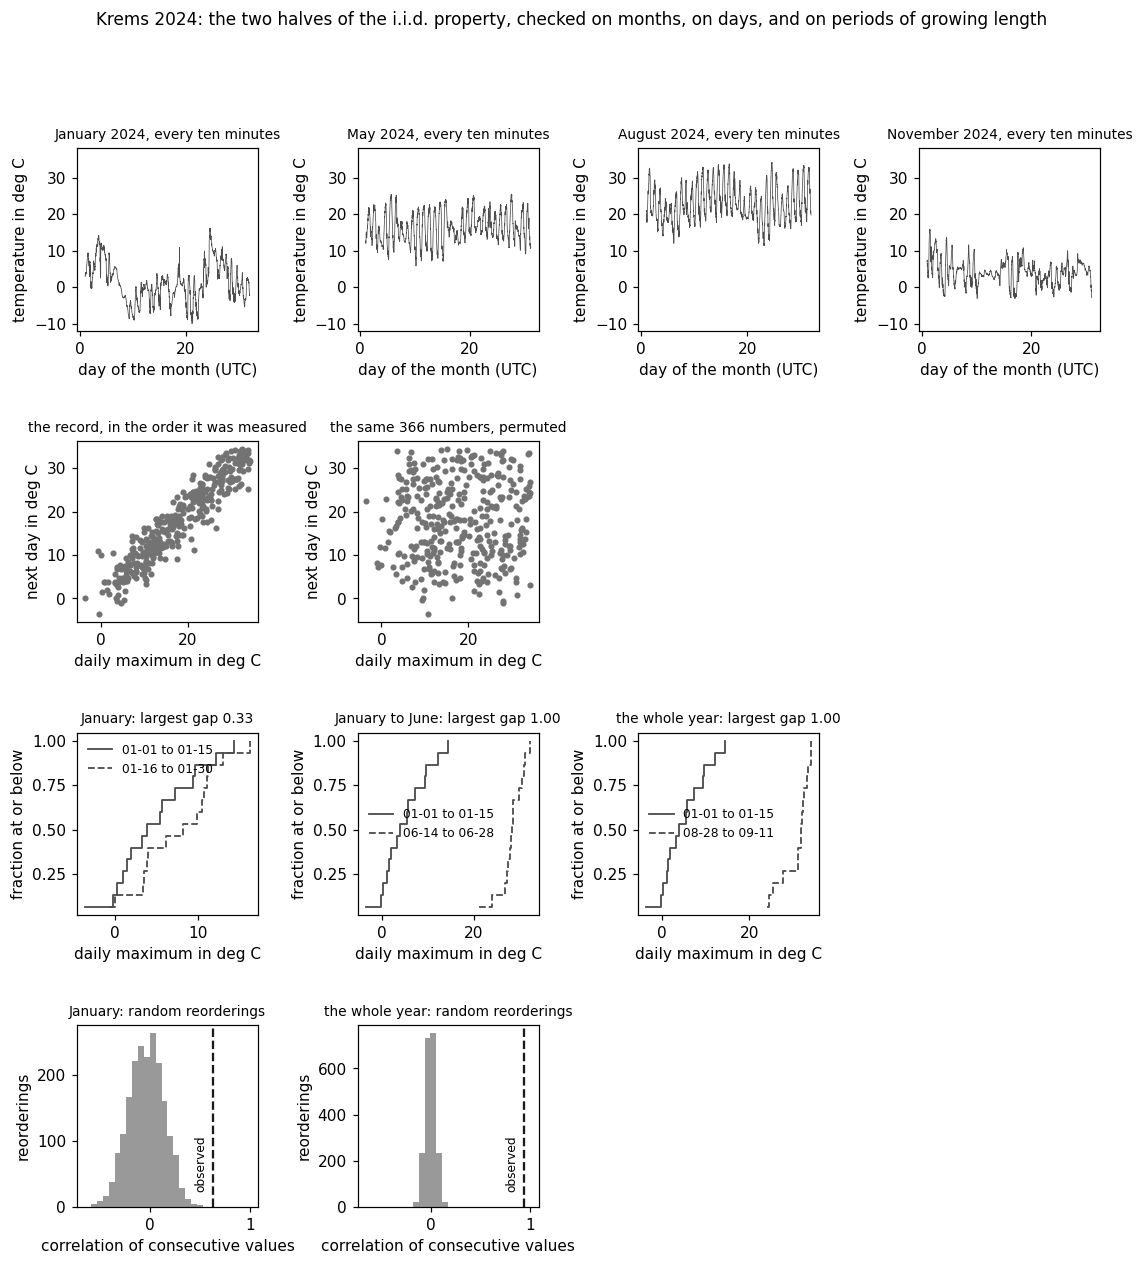
The independent and identically distributed assumption (i.i.d. assumption) is the probabilistic model that represents the generation of a sequence of data points by independent and identically distributed (i.i.d.) random variables (RVs). It consists of two separate requirements, joint independence and one common probability distribution. The assumption makes the average loss on a training set an unbiased estimate of the risk, which is what justifies empirical risk minimization (ERM) and the use of a validation set to estimate the loss outside the training set. Each requirement can be tested. Independence can be tested through its consequence for predictability of individual data points. A common probability distribution can be tested by the largest gap between the empirical cumulative distribution functions (cdfs) of two blocks of the sequence. The assumption fails under distribution shift, when the data points met after training follow a different probability distribution.
iidasspt.py, which recomputes what the entry states: the script block by block · open in ColabB-monthsA
weather station at Krems an der Donau recorded the maximum air
temperature of each day throughout 2024.
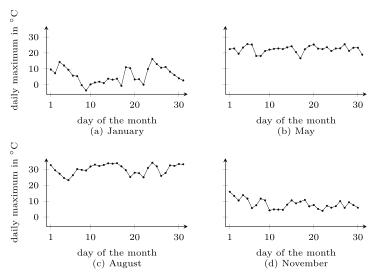
Fig. 1 shows four of those months, each a
dataset with one number per day. The numbers of one such month can be viewed as
realizations of independent and identically distributed (i.i.d.) random variables (RVs). That interpretation
is the i.i.d. assumption, and the figure shows evidence against it.
The four months have different averages. Inside every month a warm
day
is often followed by a warm one, so which day is read decides
what the neighboring values are.
pythondemos/iidasspt.py
The assumption names a quantity to aim at beyond the training set: the risk of a hypothesis, its expected loss $\mathbb{E} \big\{ L\left({\mathbf z},h \right) \big\}$ on a data point drawn from $p({\mathbf z})$. Under the i.i.d. assumption the average loss on a training set is an unbiased estimate of it (Shalev-Shwartz and Ben-David, 2014, Sect. 4.2). Let $\sigma^{2}$ be the variance of the loss of a fixed hypothesis on one data point. The average loss over $m$ data points then has variance $\sigma^{2}/m$, and for losses confined to an interval $[a,b]$, Hoeffding's inequality bounds the probability that it deviates from the risk by more than $\epsilon$ by $2 \exp \big( -2 m \epsilon^{2}/(b-a)^{2} \big)$ (Hoeffding, 1963; Shalev-Shwartz and Ben-David, 2014, Lemma B.6). This is the argument for empirical risk minimization (ERM) and for using a validation set to estimate the loss outside the training set (Shalev-Shwartz and Ben-David, 2014, Th. 11.1).
The assumption can fail: a distribution shift violates the identically distributed requirement across datasets, since the probability distribution that generated the training set differs from the one that generates the data points encountered after deployment (Quiñonero-Candela et al., 2009). Verifying that a given dataset can be approximated by realizations of i.i.d. RVs has two parts, each a form of hypothesis testing. A test first examines whether the data points are realizations of independent RVs. A second test then examines whether those RVs share one probability distribution.
One basic independence test uses the consequence that statistical independence has for the predictability of a data point from a few preceding ones. If ${\mathbf z}^{(1)}, \ldots, {\mathbf z}^{(d)}, {\mathbf z}^{(d+1)}$ are realizations of i.i.d. RVs, then no hypothesis predicts ${\mathbf z}^{(d+1)}$ from ${\mathbf z}^{(1)}, \ldots, {\mathbf z}^{(d)}$.
B-predictThe hypothesis is learned from data points constructed out of the sequence: each is an overlapping block of $d+1$ consecutive values, whose first $d$ values are its features and whose last value is its label. Learning by ERM on part of the blocks and measuring the average loss on the rest gives the quantity to compare. If the values are realizations of independent RVs, that loss is similar to the loss of a hypothesis that uses no features at all, namely the best constant. Any hypothesis space serves: a linear model with $d = 1$ under the squared error loss recovers the square of the autocorrelation at lag one, and a decision tree registers dependence that no Pearson correlation coefficient can.
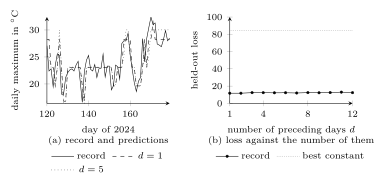
B-reachFig. 2 runs this on the Krems record. A
decision tree of depth three with the preceding days as features reaches
an average loss of $11.8$ on days it was not fitted on, against
the $84.6$ of the best constant, so the preceding days carry
information about the next one and the data points are not
realizations of
independent RVs.
pythondemos/iidasspt.py
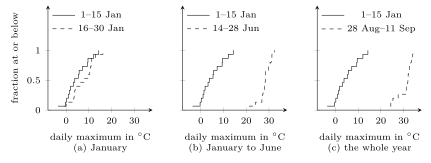
The identically distributed requirement needs to be verified in turn. Cut the dataset into blocks of equal size and compare the empirical distributions of two blocks by the largest vertical gap between their cumulative distribution functions (cdfs). That gap is the two-sample Kolmogorov–Smirnov statistic (Gretton et al., 2012, Sect. 7.2.1). It is at most one, and it equals one when the two blocks share no value.
B-verifyThe Krems record fails this requirement too, and by a wide
margin. Fig. 3 applies the block comparison over
periods of growing length. Within January the largest gap between
the two $15$-day blocks is $0.33$; over January to June and over
the whole year it is $1$, so two blocks of those periods share no
value.
pythondemos/iidasspt.py
A cruder check compares monthly averages: January averages $5.95$ degrees and July $28.99$. Take the common probability distribution to be Gaussian, with its expectation and variance set to the sample mean $17.91$ and the sample variance of the whole year, a standard deviation of $9.21$ degrees. The difference between two monthly averages of $31$ days each then has expectation zero and standard deviation $2.34$ degrees, so the observed gap of $23.03$ degrees lies $9.8$ standard deviations from zero, which that probability distribution produces with probability below $10^{-21}$. Subtracting the seasonal average removes this violation, and the dependence survives it.
See also: independent and identically distributed, autocorrelation, Ljung–Box test, probabilistic model, data point, random variable, risk, empirical risk minimization, training set, validation set, distribution shift, empirical distribution, hypothesis testing, hypothesis space, decision tree, realization.
@misc{dictml_iidasspt,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {independent and identically distributed assumption (i.i.d. assumption)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-03},
  url = {https://dictionaryofml.org/terms/iidasspt.html}
}