
decisiontree.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-22
Readiness 100/100
See also classification random forest feature importance interpretable machine learning
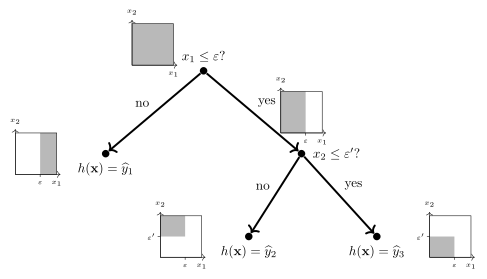
A decision tree is a flowchart-like representation of a hypothesis map: a root node reads in the feature vector of a data point and evaluates a basic test on it. The test result selects a child node, which applies a further test, and the forwarding continues until the feature vector reaches a leaf node. A leaf node has no children and represents one specific function value, i.e., a prediction. The tree partitions the feature space into decision regions, one per leaf node, on which the represented hypothesis is constant. A maximum depth and a family of node tests define the model, the hypothesis space of all such trees, which has no vector of model parameters of fixed length and is therefore searched greedily rather than by gradient methods. Decision trees serve as base models of the random forest and of gradient-boosted decision tree (GBDT) methods. Small decision trees yield interpretable machine learning (interpretable ML) if the user can comprehend the tests executed at their nodes.
decisiontree.py, which recomputes what the entry states: the script block by block · open in ColabA bank's loan approval can be written as a chain of simple tests on the applicant's features that ends in an "approve" or "reject" prediction. For example, is the income above a threshold? Is the credit score large enough? A decision tree is such a chain in general form: a flowchart-like representation of a hypothesis map $\hypothesis$.
More formally, a decision tree
is a directed acyclic graph (DAG) containing a root node that reads in the feature vector
$\featurevec$ of a data point. The root node then forwards
the data point to one of its child nodes based on some elementary test on the features $\featurevec$.
If the receiving child node is not a leaf node, i.e., it has child nodes itself,
it represents another test. Based on the test result, the data point is forwarded
to one of its descendants. This testing and forwarding of the data point is continued
until the data point ends up in a leaf node without any
children, which carries the prediction
$\predictedlabel = \hypothesis(\featurevec)$ returned by the
tree for this data point
(Fig. 1). The leaf nodes partition the
feature space into decision regions; in
Fig. 1, each test compares an entry
of $\featurevec$ with a threshold, so the decision regions
are rectangles. Next to each node,
Fig. 1 highlights the part of the
feature space that contains the feature vectors
reaching that node.
This hypothesis space has no natural parametrization. The shape of the tree and the index $\featureidx$ of the feature tested at each node are discrete choices, and how many of them a tree has depends on its shape, so $\hypospace$ is not the image of a vector of model parameters of fixed length: there is no parameter space $\reals^{n}$ on which the training error is a function. The thresholds form a vector once the shape and the tested features are fixed, but the training error is piecewise constant in each of them, since a data point changes child only when the threshold crosses its feature value, so the gradient is zero wherever it exists. Empirical risk minimization (ERM) over $\hypospace$ can therefore not use gradient descent (GD), and a fixed point view of the training iteration does not apply: an iteration adds a node, it does not update a vector. Minimizing a bound that adds a size penalty to the training error is computationally hard, and the methods below search $\hypospace$ greedily (Shalev-Shwartz and Ben-David, 2014, Sect. 18.2).
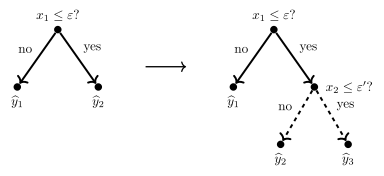
Training a decision tree amounts to extending a leaf node
by attaching another decision tree. In the simplest case, a
leaf node is replaced with a test node whose children are new
leaf nodes (Fig. 2).
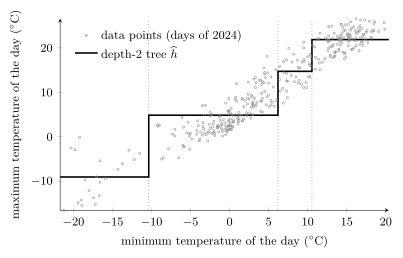
B-treeFig. 3 shows, as a
scatterplot, the result of this training on real
data. Each day of $2024$ at the Finnish Meteorological Institute (FMI) weather station
Helsinki Kaisaniemi (Finnish Meteorological Institute, 2024) is a data point, with the minimum
temperature of the day as its feature and the maximum
temperature as its label. The learned depth-$2$ tree is a piecewise
constant hypothesis with four pieces, one per leaf node,
each equal to the mean label of the days routed
there. The tree was grown to depth two rather than until the
stopping rule above fired, so that each of its four pieces is
visible in the picture.
pythondemos/decisiontree.py
See also: decision region, decision rule, classification, random forest, gradient-boosted decision tree, feature importance, interpretable machine learning.
@misc{dictml_decisiontree,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {decision tree},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/decisiontree.html}
}