
classification.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-08
Readiness 100/100
See also label binary classification logistic loss logistic regression support vector machine accuracy confusion matrix supervised learning clustering
Classification is the task of predicting a discrete-valued label for a given data point, based solely on its features. The label belongs to a finite label space: binary classification uses two label values, and multi-class classification more than two. A hypothesis whose predictions take values in the finite label space is a classifier; it partitions the feature space into decision regions separated by the decision boundary. A widely used construction compares a real-valued hypothesis against a threshold to obtain the predicted label. A natural quality measure is the $0/1$ loss; since it is neither convex nor differentiable, training methods minimize surrogates such as the logistic loss or the hinge loss, and the learned classifier is judged by the accuracy and the confusion matrix on a test set. When the label space is continuous, the task is regression.
classification.py, which recomputes what the entry states: the script block by block · open in ColabA weather station records the minimum and the maximum air temperature of each day. From these two numbers, it must be decided whether the following day brings frost, that is, whether its minimum temperature falls below $0\,^{\circ}\mathrm{C}$. A library must file each incoming text into one of the categories math, novel, or engineering. Both are classification problems: the task of predicting a discrete-valued label $\truelabel$ of a given data point, based solely on its feature vector $\featurevec$, the vector of its features (Bishop, 2006; Duda et al., 2001; Hastie et al., 2009). Classification assigns each feature vector a label from a finite set. The label takes values in a finite label space $\labelspace$ and names the category of the data point. Binary classification uses a label space with two label values, such as $\labelspace = \{-1, 1\}$ with $\truelabel = 1$ marking a frost day; multi-class classification uses more than two label values, such as $\labelspace = \{\text{math}, \text{novel}, \text{engineering}\}$ for the texts.
When the label space is continuous instead, the task is regression: predicting tomorrow's minimum temperature is regression, predicting whether tomorrow brings frost is classification. Classification is also distinct from clustering: as a form of supervised learning, classification learns from data points whose labels are known, while clustering groups data points without any given labels.
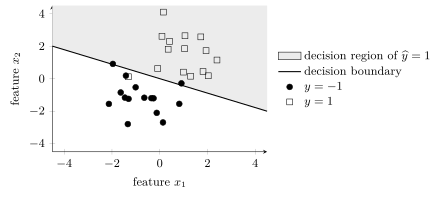
A hypothesis whose predictions take values in a finite label space is referred to as a classifier. A classifier partitions the feature space into decision regions, one region per label value, separated by the decision boundary (Fig. 1). Each classifier is fully determined by its decision regions: all feature vectors within the same decision region obtain the same predicted label.
B-thresholdA widely used construction of a classifier proceeds in two steps. First, a real-valued hypothesis $\hypothesis: \featurespace \rightarrow \reals$ quantifies the confidence in one particular label value. Second, the confidence $\hypothesis(\featurevec)$ is compared against a threshold to obtain the prediction $\predictedlabel \in \labelspace$. Logistic regression, for the label space $\labelspace = \{-1, 1\}$, uses a linear map $\hypothesis(\featurevec) = \weights^{\top} \featurevec$ as the confidence in the label value $1$. This confidence is compared against the threshold $0$, \[ \predictedlabel \defeq \begin{cases} 1 & \text{if } \hypothesis(\featurevec) \geq 0\text{,} \\ -1 & \text{otherwise.} \end{cases} \] The real-valued hypothesis $\hypothesis$ is not itself the classifier: the classifier is the thresholded map $\featurevec \mapsto \predictedlabel$, and calling $\hypothesis$ the classifier is a slight abuse of language. The two decision regions are then the halfspaces on either side of the hyperplane $\weights^{\top} \featurevec = 0$.
A natural quality measure for a classifier is the $0/1$ loss: its average over a dataset is the fraction of misclassified data points, and one minus that fraction is the accuracy. Even the best classifier cannot always achieve zero error: when data points with the same feature vector carry different labels, some misclassifications are unavoidable, and the smallest achievable risk is the Bayes risk.
B-figThe $0/1$ loss is rarely
used as the objective function for training: it is neither
convex nor differentiable as a function of the
model parameters, so its minimization is computationally
hard. Practical methods therefore minimize the average of a
surrogate loss over the training set: a loss function
that approximates the
$0/1$ loss while having more convenient properties, such
as convexity or differentiability. Logistic regression uses the
logistic loss, which is convex and differentiable
(Bishop, 2006); the support vector machine (SVM) uses the hinge loss, which
is convex but not differentiable
(Boser et al., 1992; Cortes and Vapnik, 1995).
Fig. 2 compares the three as
functions of the margin
$\truelabel \cdot \hypothesis(\featurevec)$. The learned
classifier is then judged by the accuracy and the
confusion matrix on a test set.
pythondemos/classification.py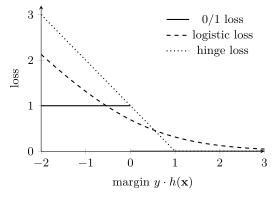
See also: label, label space, classifier, binary classification, decision boundary, decision region, $\bf 0/1$ loss, logistic loss, hinge loss, logistic regression, support vector machine, accuracy, confusion matrix, regression, supervised learning, clustering, Bayes risk.
@misc{dictml_classification,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {classification},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/classification.html}
}