
logreg.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-22
Readiness 100/100
See also classification binary classification linear classifier sigmoid function logistic loss empirical risk minimization gradient descent linear regression regularization
Logistic regression learns a linear hypothesis map for binary classification, that is, for data points whose label takes one of two values, $\truelabel \in \{-1, 1\}$. The predicted label is the sign of $\hypothesis(\featurevec)$, and the absolute value $|\hypothesis(\featurevec)|$ measures the confidence in the classification. The parameters are learned by empirical risk minimization (ERM) with the average logistic loss on the training set. This is equivalent to maximum likelihood estimation under a simple probabilistic model, under which $\sigma(\hypothesis(\featurevec))$ is the probability of the label $1$. When a data point carries this probability as a soft label instead of a class, the logistic loss is replaced by the cross-entropy between soft label and prediction, equivalently their Kullback–Leibler divergence (KL divergence). The resulting objective function is convex and smooth, so variants of gradient descent (GD) can be used to minimize it.
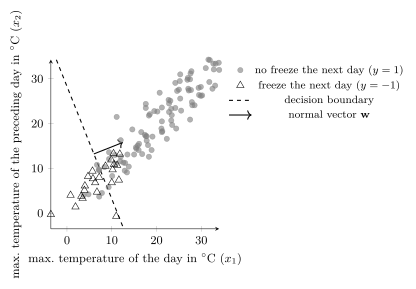
logreg.py, which recomputes what the entry states: the script block by block · open in ColabB-fetchConsider predicting whether it freezes tomorrow from recent temperature measurements. Records from a weather station turn this question into data: each day is a data point with two numeric features, the maximum temperature of the day and that of the preceding day, collected in the feature vector $\featurevec = (\feature_{1}, \feature_{2})^{\top} \in \reals^{2}$. The label $\truelabel \in \{-1, 1\}$ is $\truelabel = 1$ if the minimum temperature of the following day stays at or above $0^{\circ}$C and $\truelabel = -1$ otherwise.
B-daysFig. 1 shows such data points.
Logistic regression learns, for such a binary classification
task, a linear hypothesis map
$\hypothesis(\featurevec) = \weights^{\top} \featurevec + b$
with weight vector $\weights$ and offset $b$
(Bishop, 2006; Hastie et al., 2009).
Despite its name, the method solves a classification
problem: the regression refers to fitting the real-valued
map $\hypothesis$, not to a numeric label.
pythondemos/logreg.py
The parameters $\weights$ and $b$ of logistic regression are
learned via empirical risk minimization (ERM). The loss it minimizes is the logistic loss.
On a data point $(\featurevec, \truelabel)$, a hypothesis
$\hypothesis$ incurs
\[
\lossfunc{(\featurevec, \truelabel)}{\hypothesis} =
\ln\big(1 + \exp(-\truelabel \, \hypothesis(\featurevec))\big)
\text{.}
\]
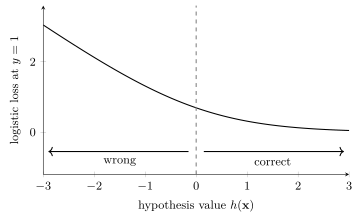
Fig. 2 shows this loss for a data point
with $\truelabel = 1$ as a function of $\hypothesis(\featurevec)$. A
correct classification with high confidence incurs a small loss. A
wrong classification incurs a loss whose size grows with the
confidence in the wrong classification.
pythondemos/logreg.py
B-dataIn this probabilistic model, given the label $\truelabel$, the feature vector $\featurevec$ is a Gaussian random variable (Gaussian RV) whose mean $\meanvec{\truelabel}$ depends on the label while its covariance matrix $\mC$ does not; the two means $\meanvec{-1}, \meanvec{+1} \in \reals^{\featuredim}$ are the parameters of the model. The best linear classifier under this model assigns $\featurevec$ to the label with the nearer mean, and its decision boundary is the hyperplane midway between the two means. Its weight vector is $\weights = \mC^{-1}\big(\meanvec{+1} - \meanvec{-1}\big)$. The factor $\tfrac{1}{2}$ that puts the decision boundary midway belongs to the offset $\offset$ and not to $\weights$: any positive multiple of $\weights$ leaves the decision boundary where it is, but only this one reproduces the posterior probability below. Learning the parameters $\weights$ and $\offset$ of the linear classifier is thus the same as estimating the parameters of the probabilistic model, and maximum likelihood is the principled way to estimate them. Under the model, the posterior probability of $\truelabel = 1$ is the sigmoid function $\sigma(\weights^{\top} \featurevec + b)$ with $\sigma(z) = 1 / (1 + e^{-z})$. Maximizing the likelihood function coincides with minimizing the average logistic loss $f$ (Murphy, 2012, Sect. 8.3).
B-gdThe hypothesis value as a confidence. The probabilistic model gives the number $\hypothesis(\featurevec)$ a second interpretation beyond its sign: $\sigma(\hypothesis(\featurevec))$ is the probability that the label of a data point with feature vector $\featurevec$ is $\truelabel = 1$, and $\sigma(-\hypothesis(\featurevec)) = 1 - \sigma(\hypothesis(\featurevec))$ the probability of $\truelabel = -1$. A forecast $\hypothesis(\featurevec) = 2$ thus says that $88$ percent of the days with these temperatures are followed by a frost-free day, and a forecast of $0$ that half of them are. Whether these numbers can be trusted is the question of calibration (Dawid, 1982). In most applications a data point carries only its label, the class that occurred. The logistic loss is the loss for this case. It is the cross-entropy between the probability mass function (pmf) concentrated on the observed label and the predicted pmf $(\sigma(\hypothesis(\featurevec)), 1 - \sigma(\hypothesis(\featurevec)))$ (Bishop, 2006, Sect. 4.3.2).
B-clfSome data points carry more than a class: a soft label $\labelprob \in [0, 1]$, the probability of $\truelabel = 1$ itself. It may be the frequency of frost among the recorded days with the same temperatures, the share of several annotators who chose the class, or the output of a larger classifier, as in knowledge distillation. For such a data point the logistic loss is replaced by the cross-entropy between the soft label and the prediction, \[ \lossfunc{(\featurevec, \labelprob)}{\hypothesis} = - \labelprob \ln \sigma(\hypothesis(\featurevec)) - (1 - \labelprob) \ln \big(1 - \sigma(\hypothesis(\featurevec))\big) \text{,} \] which for $\labelprob \in \{0, 1\}$ is the logistic loss again. Learning then minimizes the average of this loss over the training set, as before.
This cross-entropy equals the Kullback–Leibler divergence (KL divergence) from the predicted pmf to the soft label pmf $(\labelprob, 1 - \labelprob)$ plus the entropy of the soft label pmf, which does not depend on $\hypothesis$ (Bishop, 2006, Sect. 1.6.1, Eq. (1.113)). Minimizing either therefore learns the same $\hypothesis$, and the loss on a data point is smallest exactly when $\sigma(\hypothesis(\featurevec)) = \labelprob$, when the confidence of the prediction matches the probability of the class. A hard label can never be matched this way, since $\sigma$ never reaches $0$ or $1$. This is why the logistic loss keeps decreasing as $|\hypothesis(\featurevec)|$ grows on a correctly classified data point.
Minimizing the average loss. With hard or soft labels, the parameters are found by minimizing the average loss $f$. Unlike linear regression with the squared error loss, the minimization admits no closed-form solution. As in linear regression, however, the objective function $f$ is convex and smooth, so gradient descent (GD) applies. The parameters are collected as the pair $(\weights, b)$, and the GD step reads \[ (\weights, b)^{(\iteridx+1)} = T\big((\weights, b)^{(\iteridx)}\big) \text{, with } T(\weights, b) \defeq (\weights, b) - \lrate \nabla f(\weights, b) \text{,} \] with learning rate $\lrate$. The gradient $\nabla f$ of the average logistic loss has the weight part \[ \nabla_{\weights} f = -\frac{1}{\samplesize} \sum_{\sampleidx=1}^{\samplesize} \truelabel^{(\sampleidx)} \featurevec^{(\sampleidx)} \, \sigma\big(-\truelabel^{(\sampleidx)} (\weights^{\top} \featurevec^{(\sampleidx)} + b)\big) \text{,} \] and analogously for $b$.
The pair $(\weights, b)$ is a fixed point of the operator $T$ precisely when $\nabla f(\weights, b) = \mathbf{0}$, which by convexity of $f$ is exactly when $(\weights, b)$ is a minimizer. It can be shown that $\nabla f$ is Lipschitz continuous with some constant $\lipschitzconstant$ (Hastie et al., 2009). For a constant learning rate $\lrate < 2/\lipschitzconstant$, every GD step decreases $f$ and the values converge to the minimum, $f\big((\weights, b)^{(\iteridx)}\big) \to \min f$; the choice $\lrate = 1/\lipschitzconstant$ is the standard one. The iterates $(\weights, b)^{(\iteridx)}$ themselves need not converge: on a linearly separable training set the minimum is not attained, and the norm of the iterates grows without bound while the training error tends to zero. Adding the penalty term $\regparam \sqeuclnorm{\weights}$, with a positive $\regparam$, to $f$ makes the objective function strictly convex, with a unique minimizer that the iterates then approach (Hastie et al., 2009).
In practice, plain GD is seldom used to minimize $f$: the smooth convex objective function is minimized faster by Newton's method, equivalently iteratively reweighted least squares (Hastie et al., 2009), by the quasi-Newton solver L-BFGS (Liu and Nocedal, 1989), and, for a large training set, by coordinate descent (Wright, 2015).
B-lossWhat these solvers minimize is the average logistic loss, but that is
not the only loss with which a linear classifier can be learned. In
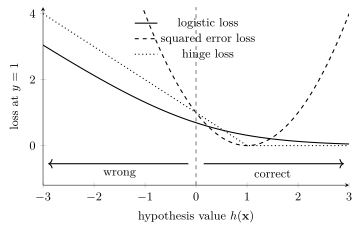
principle, the squared error loss serves too: with the label values encoded as the real
numbers $+1$ and $-1$, the squared error
$\big(\truelabel - (\weights^{\top}\featurevec + b)\big)^{2}$ is well
defined. Minimizing the squared error loss, however, has a flaw: it
penalizes a prediction $\weights^{\top}\featurevec + b$ that is
large, positive, and correct, while the logistic loss keeps
decreasing as this margin grows
(Fig. 3). The
hinge loss of the support vector machine (SVM) shares this behavior on a
correctly classified data point but stays flat once the
margin exceeds one.
pythondemos/logreg.py
See also: classification, binary classification, linear classifier, decision boundary, sigmoid function, logistic loss, squared error loss, hinge loss, empirical risk minimization, gradient descent, maximum likelihood, linear regression, softmax function, regularization, calibration, soft label, cross-entropy, Kullback–Leibler divergence.
@misc{dictml_logreg,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {logistic regression},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/logreg.html}
}