
clustering.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-22
Readiness 100/100
See also $k$-means Gaussian mixture model expectation–maximization hyperparameter unsupervised learning
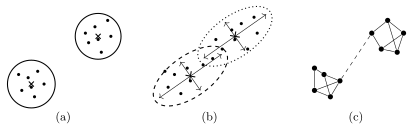
Clustering decomposes a dataset into subsets, called clusters, such that data points within the same cluster are more similar to each other than to data points in other clusters. Clustering methods differ in the measure of similarity between data points, in the representation of a cluster, and in whether each data point is assigned to exactly one cluster (hard clustering) or to several with varying degrees of belonging (soft clustering). $k$-means represents a cluster by a cluster centroid and a Gaussian mixture model (GMM) by a multivariate normal distribution, so their clusters are convex regions and ellipsoids. Graph clustering represents the data points as the nodes of a similarity graph and uses its weighted edges to determine the clusters.
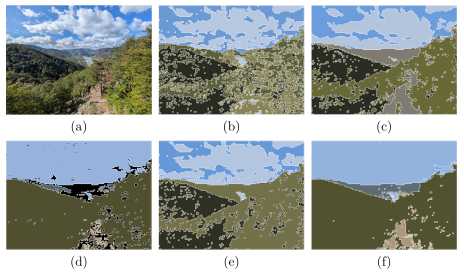
clustering.py, which recomputes what the entry states: the script block by block · open in ColabB-patchesA photograph taken in the Wachau shows
sky, clouds, forested slopes, sunlit vineyards and rock
(Fig. 1(a)). Cutting it into
$96 \times 128$ patches of $5 \times 5$ pixels gives $12288$
data points, each characterized by a feature vector
$\featurevec \in \reals^{3}$ that holds the mean red, green and
blue values of the patch. Clustering is the task of decomposing
such a dataset into clusters, such that
data points within the same cluster are more similar
to each other than to data points in other clusters
(Bishop, 2006, Sect. 9.1;
Hastie et al., 2009, Sect. 14.3).
Fig. 1(b)–(f) shows the
segmentations delivered by five clustering methods, $k$-means,
a Gaussian mixture model (GMM), density-based spatial clustering of applications with noise (DBSCAN), spectral clustering and
convex clustering. The number $\nrcluster$ of clusters
is either an input, as in $k$-means, or determined by the
method from its other hyperparameters, as in DBSCAN.
pythondemos/clustering.py
On the photograph, the five cluster centroids of $k$-means with $\nrcluster = 5$ are five representative colors, and each cluster consists of the patches whose color is nearest to one of them: sky, cloud, shaded forest, sunlit slopes and rock (Fig. 1(b)). Painting each patch in the color of its cluster centroid also compresses the photograph to five colors. A clustering learned from one photograph is judged by how it assigns new patches: in $k$-means, a new data point joins the cluster of the nearest cluster centroid, so the cluster centroids are the learned hypothesis.
B-gmmA GMM represents each cluster by a multivariate normal distribution: a cluster index is drawn first, then the feature vector from that cluster's multivariate normal distribution. The degree of belonging of a data point to a cluster is the posterior distribution of its cluster index, and the expectation–maximization (EM) algorithm learns the model parameters by maximum likelihood (Bishop, 2006, Sect. 9.2). The result is a soft clustering whose clusters are ellipsoids; hard clustering is the extreme case in which every degree of belonging is $0$ or $1$. On the photograph, each surface type becomes a multivariate normal distribution over colors, and the degree of belonging of a patch to the sky cluster is the probability that its color was drawn from the multivariate normal distribution of the sky. Painting each patch by the cluster with the largest degree of belonging gives Fig. 1(c); one in eight patches, mostly along the horizon and the cloud edges, has no degree of belonging above $0.8$.
B-dbscanDBSCAN defines a cluster through two hyperparameters, a distance $\varepsilon$ and a minimum size $m^{*}$ of a cluster (Ester et al., 1996). A data point is a core point if at least $m^{*}$ data points lie within Euclidean distance $\varepsilon$ of it. A cluster is a maximal set of data points that are connected through a chain of core points at most $\varepsilon$ apart, and data points that are neither core points nor within $\varepsilon$ of one are noise. A cluster can therefore have any shape that a chain of nearby data points can trace, and the number of clusters is an output, not an input. On the photograph, $\varepsilon$ is a distance between colors. With $\varepsilon = 0.03$ and $m^{*} = 32$, the blue of the sky and the white of the clouds are joined by a chain of intermediate colors, so sky and cloud form one cluster and the land another. The patches along the horizon, whose mixed colors are rare, are noise (Fig. 1(d)).
Graph clustering methods represent the dataset as the nodes $\sampleidx = 1, \ldots, \samplesize$ of a graph whose edge weights express the similarity between data points, e.g., the $k$-nearest-neighbor graph ($k$-NN graph) that connects each data point to its nearest neighbors (Luxburg, 2007, Sect. 2). The clusters are determined by the connectivity of the nodes: a cluster is a subset of nodes whose total edge weight to the rest of the graph, divided by the number of nodes in the subset, is small. The sum of this ratio over the clusters is the ratio cut that spectral clustering minimizes approximately (Luxburg, 2007, Sect. 5).
B-convexSpectral clustering computes the clusters from eigenvectors of the
Laplacian matrix of the graph (Luxburg, 2007;
Ng et al., 2001) and flow-based clustering from network flows
between selected nodes (SarcheshmehPour et al., 2021). There are
also graph clustering methods that incorporate node-wise
feature vectors $\featurevec^{(\sampleidx)}$,
$\sampleidx = 1, \ldots, \samplesize$: convex clustering
combines the connectivity of the nodes with the node-wise
feature vectors. Graph clustering methods are appealing
for data points without an obvious choice for numeric
feature vectors: scientific papers connected by citations,
users of a social network connected by friendships, or web pages
connected by links. On the photograph in
Fig. 1(a), the nodes are the
patches and each patch is connected to the ten patches of most
similar color;
spectral clustering then separates the five surface types
(Fig. 1(e)), since the patches of
one surface type are neighbors in color.
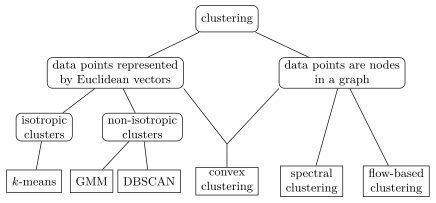
Fig. 3 arranges the methods by the
representation of the data points and of a cluster.
Beyond image segmentation, clustering is used for customer segmentation (Wedel and Kamakura, 2000), for grouping documents by topic in natural language processing (NLP) (Manning et al., 2008, Sect. 16.1), for community detection in social networks (Fortunato, 2010), and for anomaly detection, where a data point that falls into no cluster or into a tiny one is an outlier (Chandola et al., 2009). As a preprocessing step for supervised learning, clustering reduces a dataset to its cluster centroids as prototypes (Hastie et al., 2009, Sect. 13.2.1), or adds the distances of a data point to the cluster centroids as new features (Coates and Ng, 2012). It can also split the dataset so that a separate hypothesis is learned per cluster, e.g., one linear regression per cluster (Späth, 1979).
Synonyms: segmentation.
See also: cluster, cluster centroid, clustering error, degree of belonging, hard clustering, soft clustering, $k$-means, Gaussian mixture model, expectation–maximization, density-based spatial clustering of applications with noise, spectral clustering, graph clustering, flow-based clustering, convex clustering, coreset, hyperparameter, anomaly detection, image segmentation, similarity graph, Laplacian matrix, $k$-nearest-neighbor graph, unsupervised learning.
@misc{dictml_clustering,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {clustering},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/clustering.html}
}