
cm.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-21
Readiness 100/100
See also classification accuracy baseline training set validation set label matrix
The confusion matrix of a hypothesis on a finite dataset with $\nrcategories$ label values is the $\nrcategories \times \nrcategories$ matrix whose entry in row $\truelabel$ and column $\predictedlabel$ counts the data points with true label $\truelabel$ and prediction $\predictedlabel$. Its diagonal counts the correct predictions, and each off-diagonal entry counts one kind of misclassification. The accuracy, the precision, and the recall are obtained from the matrix by normalizing the diagonal, a column, or a row. On imbalanced data, the confusion matrix exposes failure on the rare class that the accuracy alone hides.
cm.py, which recomputes what the entry states: the script block by block · open in ColabB-fetchThe weather station in Krems an
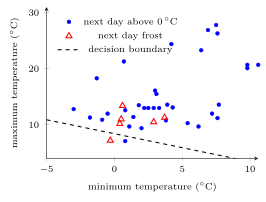
der Donau (Austria) records the minimum and the maximum air
temperature of each day. A linear classifier is learned by
logistic regression from a training set $\trainset$ of $40$ such
data points from February and April 2024
(Fig. 1). The features of
a data point are the two
temperatures of one day; its label indicates whether
the minimum temperature of the following day stays above
$0\,^{\circ}\mathrm{C}$ or falls below it, a frost warning.
pythondemos/cm.py
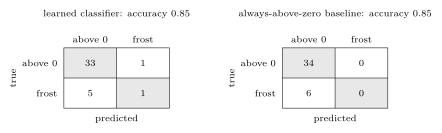
pythondemos/cm.pyB-cmThe standard classification metrics are ratios of entries
of the confusion matrix. The accuracy is the sum of the diagonal
divided by $\samplesize$. Normalizing a row by its sum yields the
fraction of data points of that class that are detected
(for the positive class, the recall), while normalizing a
column yields the fraction of predictions of that class
that are right, the precision. For the learned
classifier of Fig. 2, with frost as the
positive class, the recall is $1/6$ and the precision
is $1/2$. The baseline has a recall of $0$, and its
precision is not defined at all, since it never predicts
frost (pythondemos/cm.py). On imbalanced data, the confusion
matrix exposes what a large
accuracy can hide. A classifier that never predicts
the rare class fills the row of that class with misclassifications
while keeping most predictions correct. The
always-above-zero baseline in Fig. 2
does exactly that (see baseline). All numbers above are
computed on the training set $\trainset$, the $40$ days the
classifier was learned from. A frost warning is judged on days
that did not belong to $\trainset$, so the confusion matrix, and
every ratio taken from it, must be computed again on a validation set
before one classifier is preferred over the other.
See also: classification, accuracy, precision, recall, imbalanced data, baseline, training set, validation set, metric, label, label space, matrix.
@misc{dictml_cm,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {confusion matrix},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/cm.html}
}