B-plot writes when the script runsDictionary of Applied Machine Learning · independent and identically distributed assumption (i.i.d. assumption)
Updated on 2026-11-03
Numerical companion to the entry independent and identically distributed assumption (i.i.d. assumption): it recomputes what the entry states and prints one line per check
iidasspt.py — numerical companion to the glossary entry 'independent and identically distributed assumption (i.i.d. assumption)'.
Run it without installing anything:uv run https://dictionaryofml.org/terms/iidasspt.py
uv downloads this script and the pinned NumPy and Matplotlib it needs, then runs it; the script fetches any input file it uses. To keep the output files, download iidasspt.py into a folder and run uv run iidasspt.py there. With NumPy and Matplotlib already installed, python3 iidasspt.py, from any directory — it writes its output files into the current directory. Fixed seeds, so the printed numbers reproduce exactly. Download iidasspt.py · Notebook · Open in Colab
Before running a downloaded copy, scan it: uvx bandit -q -t B102,B307,B602,B605 iidasspt.py (B102,B307,B602,B605 are the exec, eval and shell checks of bandit) reports nothing: the script runs no shell command and evaluates no generated code.
One cell per block of the script: the code, and what that code printed when it last ran here
"""
iidasspt.py — numerical companion to the glossary entry 'independent and
identically distributed assumption (i.i.d. assumption)'.

The entry asks whether temperature measurements recorded at Krems in 2024 can
be modeled as i.i.d. random variables, and answers it by testing the two
requirements of the assumption separately on the record itself. Self-contained
(numpy/matplotlib only), fixed seed; the measurements are fetched from the
public GeoSphere Austria archive.

Blocks
------
[B-months]      Daily maximum air temperature for January, May, August and
                November, one dataset per month. The levels differ across the
                months and inside each of them a warm day is often followed
                by a warm one, which is what the rest of the entry measures.
[B-data]        366 daily maximum temperatures at Krems an der Donau
                (station 3805) for 2024.
[B-identical]   The identically distributed half fails: the monthly averages
                run from January to July, so the distribution of the
                temperature depends on which day is read.
[B-independent] The independent half fails too: the event "above 25 degrees"
                has probability 0.265 per day, so under independence two
                consecutive days would both exceed it with probability 0.070;
                the record does it three times as often. The lag-one
                correlation says the same.
[B-lagfit]      What a decision tree predicts from the preceding days, and how
                its held-out loss falls with the number of them used as
                features -- against the
                same curve for the shuffled record, which stays at the loss of
                the best constant. Writes the entry's second figure.
[B-shuffle]     A random permutation of the same 366 numbers leaves the
                collection of values untouched and makes the product rule
                hold, which is what independence is about. Writes the two
                panels of the entry's second figure.
[B-predict]     The independence check in the terms ML already uses: if the
                earlier values are useless as features, a hypothesis fitted on
                them cannot beat the best constant. Fitted on the whole record
                with one lag and a linear model, the reduction in loss is
                exactly the squared lag-one correlation. Judged on held-out
                days, a linear model and a decision tree both reach about 0.86,
                which no reordering approaches -- and the tree, the larger
                hypothesis space, does slightly worse on this near-linear
                relation.
[B-reach]       What that check can and cannot see. On a sequence whose
                conditional mean is flat, no enlargement of the hypothesis
                space helps: degrees 1 to 3 all do worse out of sample than
                the best constant, the polynomial ones worse than the linear
                one. Only predicting the squared value helps. The reach is set by the
                hypothesis space AND by what the hypothesis is asked to
                predict.
[B-deseason]    Subtracting the seasonal average repairs the identically
                distributed half only: the lag-one correlation of what is
                left is still 0.67.
[B-gaussgap]    How unlikely the January-July gap is under one common
                distribution: fit a Gaussian to the whole year, and the gap
                between two monthly averages is 9.8 standard deviations out.
[B-verify]      The two standard methods applied to periods of growing length
                (January, January to June, the whole year): the largest gap
                between the empirical CDFs of two 15-day blocks of the period
                against the Kolmogorov-Smirnov threshold, and the lag-one
                correlation calibrated by a permutation test. Writes the
                panels of the entry's third figure.

Outputs
-------
iidasspt_temps.csv            : date, daily maximum temperature, 366 days of 2024
iidasspt_month_<mon>.csv      : day, daily maximum temperature, four months
iidasspt_lagfit_series.csv    : day, temp, fit1, fit5 -- 60 days with the
                                predictions of a decision tree reading 1 and 5
                                preceding days
iidasspt_lagfit_error.csv     : lags, record, shuffled, constant -- held-out
                                squared error loss against the number of lags
iidasspt_cdf_<period>_<block>.csv : temperature, fraction -- empirical CDFs
iidasspt.png             : preview (checking only)

Data generated by pythondemos/iidasspt.py.
"""

# /// script
# requires-python = ">=3.10"
# dependencies = ["matplotlib==3.10.7", "numpy==2.3.4"]
# ///

import json
import math
import urllib.request
from pathlib import Path

import numpy as np
import matplotlib

matplotlib.use("Agg")
import matplotlib.pyplot as plt

OUT_DIR = Path(__file__).parent
ARCHIVE = "https://dataset.api.hub.geosphere.at/v1/station/historical/"
STATION = 3805

report = []


def check(name, ok):
    report.append((name, bool(ok)))
    print(f"  [{'ok' if ok else 'FAIL'}] {name}")


def fetch(resource, parameter, start, end):
    """One parameter of one station from the GeoSphere Austria archive."""
    url = (f"{ARCHIVE}{resource}?parameters={parameter}"
           f"&station_ids={STATION}&start={start}&end={end}")
    with urllib.request.urlopen(url, timeout=180) as resp:
        payload = json.load(resp)
    values = payload["features"][0]["properties"]["parameters"]
    key = list(values.keys())[0]
    return (np.array(values[key]["data"], dtype=float),
            [t[:16] for t in payload["timestamps"]])


def lag_one_correlation(x):
    """Pearson correlation coefficient between consecutive entries of x."""
    return float(np.corrcoef(x[:-1], x[1:])[0, 1])


def ks_statistic(a, b):
    """Largest gap between the empirical CDFs of two collections."""
    grid = np.sort(np.concatenate([a, b]))
    fa = np.searchsorted(np.sort(a), grid, side="right") / len(a)
    fb = np.searchsorted(np.sort(b), grid, side="right") / len(b)
    return float(np.abs(fa - fb).max())


def ks_threshold(size, level):
    """Two-sample Kolmogorov-Smirnov critical value for two blocks of size."""
    return math.sqrt(-0.5 * math.log(level / 2)) * math.sqrt(2 / size)


def lagged_design(x, nrlags):
    """Rows of `nrlags` earlier values, and the value that follows them."""
    cols = [x[nrlags - 1 - k:len(x) - 1 - k] for k in range(nrlags)]
    return np.column_stack(cols), x[nrlags:]


def fit_tree(design, target, max_depth, min_leaf=5, nr_thresholds=16):
    """Regression tree: split on the feature and threshold that leave the
    smallest total squared error, to a fixed depth."""
    def grow(rows, depth):
        values = target[rows]
        node = {"value": float(values.mean())}
        if depth == max_depth or len(rows) < 2 * min_leaf or np.ptp(values) == 0:
            return node
        best = None
        for col in range(design.shape[1]):
            column = design[rows, col]
            grid = np.linspace(0, 1, nr_thresholds + 2)[1:-1]
            for thr in np.unique(np.quantile(column, grid)):
                left = column <= thr
                nr_left = int(left.sum())
                nr_right = len(rows) - nr_left
                if nr_left < min_leaf or nr_right < min_leaf:
                    continue
                err = (values[left].var() * nr_left
                       + values[~left].var() * nr_right)
                if best is None or err < best[0]:
                    best = (err, col, float(thr), left)
        if best is None:
            return node
        _, col, thr, left = best
        node.update(col=col, thr=thr, left=grow(rows[left], depth + 1),
                    right=grow(rows[~left], depth + 1))
        return node

    return grow(np.arange(len(target)), 0)


def predict_tree(node, design):
    """Follow each row down the tree to the leaf that holds its prediction."""
    out = np.empty(len(design))
    for i, row in enumerate(design):
        walk = node
        while "col" in walk:
            walk = walk["left"] if row[walk["col"]] <= walk["thr"] else walk["right"]
        out[i] = walk["value"]
    return out


def one_loss_reduction(x, nrlags, depth, holdout, rng):
    """1 - (loss of a hypothesis reading the earlier values)/(loss of the
    best constant), on the days not used to fit it. depth=None is a linear
    model, an integer is a decision tree of that depth."""
    design, target = lagged_design(x, nrlags)
    size = len(target)
    if holdout is None:
        fit_idx = judge_idx = np.arange(size)
    else:
        order = rng.permutation(size)
        cut = int(holdout * size)
        fit_idx, judge_idx = order[:cut], order[cut:]
    if depth is None:
        fit_mtx = np.c_[np.ones(len(fit_idx)), design[fit_idx]]
        weights, *_ = np.linalg.lstsq(fit_mtx, target[fit_idx], rcond=None)
        guess = np.c_[np.ones(len(judge_idx)), design[judge_idx]] @ weights
    else:
        guess = predict_tree(fit_tree(design[fit_idx], target[fit_idx], depth),
                             design[judge_idx])
    with_lags = np.mean((target[judge_idx] - guess) ** 2)
    constant = np.mean((target[judge_idx] - target[fit_idx].mean()) ** 2)
    return float(1 - with_lags / constant)


def loss_reduction(x, nrlags=1, depth=None, holdout=None, rng=None, repeats=1):
    """one_loss_reduction averaged over `repeats` random splits of the days."""
    if holdout is None:
        return one_loss_reduction(x, nrlags, depth, None, None)
    return float(np.mean([one_loss_reduction(x, nrlags, depth, holdout, rng)
                          for _ in range(repeats)]))


def empirical_cdf(x):
    """Sorted values and the fraction of the collection at or below each."""
    values = np.sort(x)
    return values, np.arange(1, len(values) + 1) / len(values)
366 daily maximum temperatures at Krems an der Donau (station 3805) for 2024.
temp, stamps = fetch("klima-v2-1d", "tlmax", "2024-01-01", "2024-12-31")
month = np.array([int(s[5:7]) for s in stamps])
with open(OUT_DIR / "iidasspt_temps.csv", "w") as f:
    f.write("date,tlmax\n")
    for day, value in zip(stamps, temp):
        f.write(f"{day[:10]},{value:g}\n")
print(f"[B-data] {len(temp)} daily maxima, mean {temp.mean():.2f} deg, "
      f"variance {temp.var(ddof=1):.2f} deg squared")
check("[B-data] the year has all 366 days", len(temp) == 366)
check("[B-data] the record matches the archive (Feb 1: 10.4 deg)",
      stamps[31][:10] == "2024-02-01" and np.isclose(temp[31], 10.4))
[B-data] 366 daily maxima, mean 17.91 deg, variance 84.87 deg squared
  [ok] [B-data] the year has all 366 days
  [ok] [B-data] the record matches the archive (Feb 1: 10.4 deg)
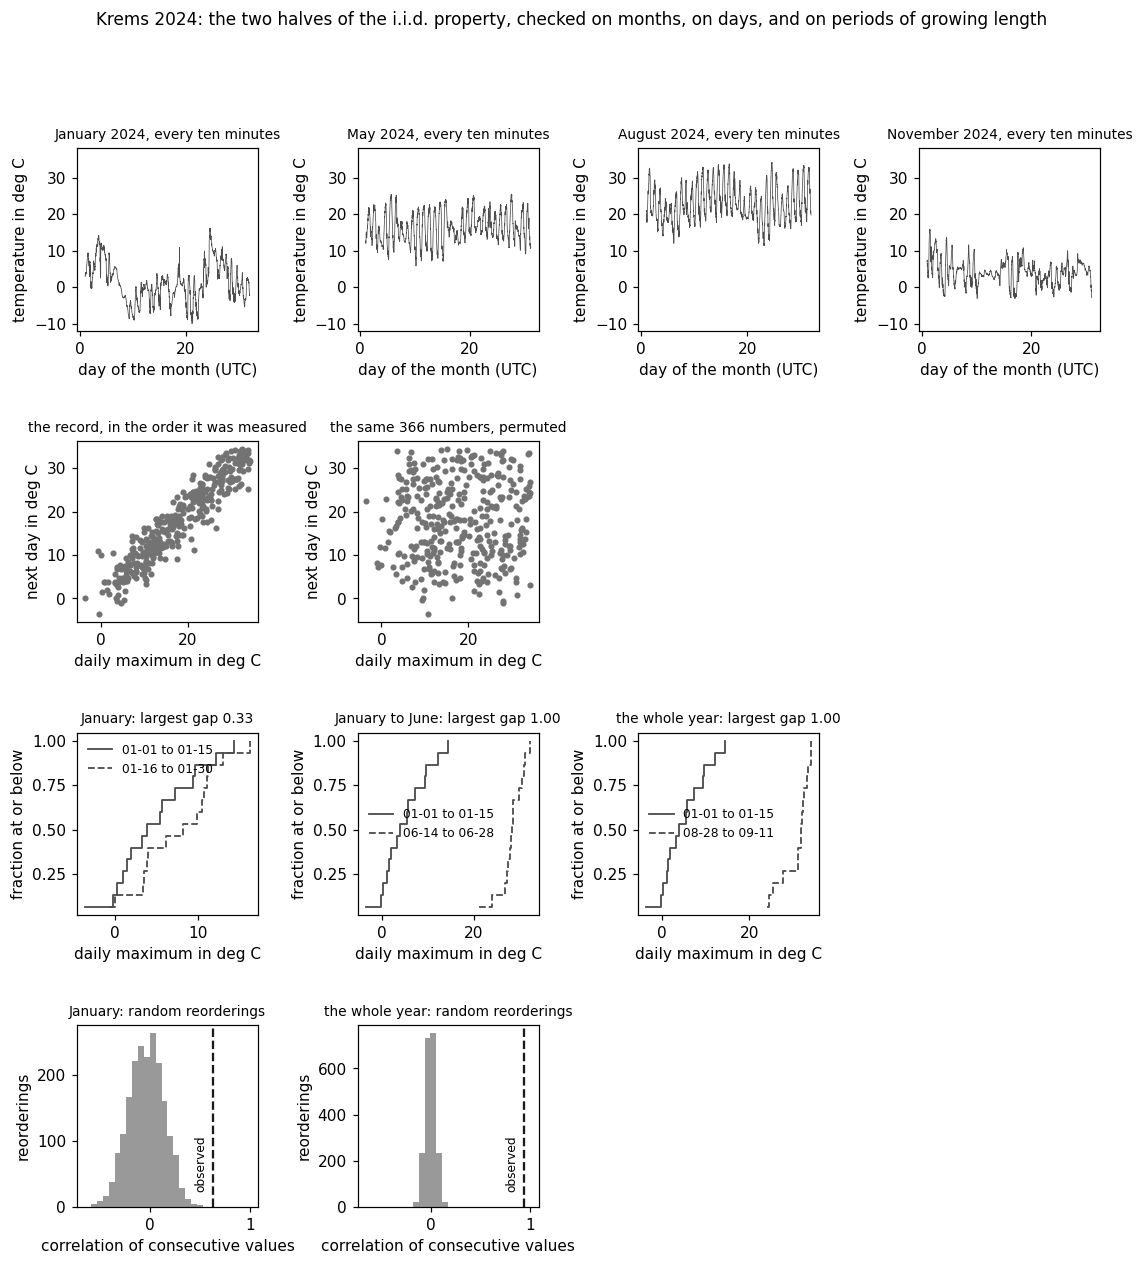
Daily maximum air temperature for January, May, August and November, one dataset per month. The levels differ across the months and inside each of them a warm day is often followed by a warm one, which is what the rest of the entry measures.
MONTHS = [(1, "jan", "January"), (5, "may", "May"),
          (8, "aug", "August"), (11, "nov", "November")]
month_series = {}
for number, tag, title in MONTHS:
    days = np.arange(1, int((month == number).sum()) + 1)
    values = temp[month == number]
    month_series[tag] = (days, values, title)
    with open(OUT_DIR / f"iidasspt_month_{tag}.csv", "w") as f:
        f.write("day,temp\n")
        for day, value in zip(days, values):
            f.write(f"{day},{value:.1f}\n")
print("[B-months] monthly averages of the daily maximum: "
      + ", ".join(f"{month_series[t][2]} {month_series[t][1].mean():.2f}"
                  for _, t, _ in MONTHS))
check("[B-months] the monthly averages of the daily maximum differ widely",
      max(month_series[t][1].mean() for _, t, _ in MONTHS)
      - min(month_series[t][1].mean() for _, t, _ in MONTHS) > 20)
[B-months] monthly averages of the daily maximum: January 5.95, May 22.29, August 30.09, November 8.24
  [ok] [B-months] the monthly averages of the daily maximum differ widely
The identically distributed half fails: the monthly averages run from January to July, so the distribution of the temperature depends on which day is read.
jan, jul = temp[month == 1], temp[month == 7]
print(f"[B-identical] January averages {jan.mean():.2f} deg and July "
      f"{jul.mean():.2f} deg")
check("[B-identical] the July average exceeds the January average by more "
      "than twenty degrees", jul.mean() - jan.mean() > 20.0)
check("[B-identical] the gap is large against the spread within a month",
      jul.mean() - jan.mean() > 4.0 * max(jan.std(ddof=1), jul.std(ddof=1)))
[B-identical] January averages 5.95 deg and July 28.99 deg
  [ok] [B-identical] the July average exceeds the January average by more than twenty degrees
  [ok] [B-identical] the gap is large against the spread within a month
The independent half fails too: the event "above 25 degrees" has probability 0.265 per day, so under independence two consecutive days would both exceed it with probability 0.070; the record does it three times as often. The lag-one correlation says the same.
THRESHOLD = 25.0
warm = temp > THRESHOLD
p_single = warm.mean()
p_pair = (warm[:-1] & warm[1:]).mean()
print(f"[B-independent] a day above {THRESHOLD:g} deg has frequency "
      f"{p_single:.3f}; two in a row {p_pair:.3f} against the product "
      f"{p_single ** 2:.3f}, a factor of {p_pair / p_single ** 2:.2f}")
print(f"[B-independent] lag-one correlation of the record "
      f"{lag_one_correlation(temp):.3f}")
check("[B-independent] consecutive warm days are at least three times as "
      "frequent as the product rule allows", p_pair > 3.0 * p_single ** 2)
check("[B-independent] the lag-one correlation is above 0.9",
      lag_one_correlation(temp) > 0.9)
[B-independent] a day above 25 deg has frequency 0.265; two in a row 0.230 against the product 0.070, a factor of 3.28
[B-independent] lag-one correlation of the record 0.940
  [ok] [B-independent] consecutive warm days are at least three times as frequent as the product rule allows
  [ok] [B-independent] the lag-one correlation is above 0.9
A random permutation of the same 366 numbers leaves the collection of values untouched and makes the product rule hold, which is what independence is about. Writes the two panels of the entry's second figure.
rng = np.random.default_rng(0)
shuffled = rng.permutation(temp)
warm_s = shuffled > THRESHOLD
p_pair_s = (warm_s[:-1] & warm_s[1:]).mean()
print(f"[B-shuffle] after permuting: two warm days in a row {p_pair_s:.3f} "
      f"against the product {p_single ** 2:.3f}; lag-one correlation "
      f"{lag_one_correlation(shuffled):.3f}")
check("[B-shuffle] permuting leaves the collection of values unchanged",
      np.allclose(np.sort(shuffled), np.sort(temp)))
check("[B-shuffle] the product rule now holds to within a tenth",
      abs(p_pair_s - p_single ** 2) < 0.1 * p_single ** 2)
check("[B-shuffle] the lag-one correlation is close to zero",
      abs(lag_one_correlation(shuffled)) < 0.1)
[B-shuffle] after permuting: two warm days in a row 0.071 against the product 0.070; lag-one correlation 0.035
  [ok] [B-shuffle] permuting leaves the collection of values unchanged
  [ok] [B-shuffle] the product rule now holds to within a tenth
  [ok] [B-shuffle] the lag-one correlation is close to zero
What a decision tree predicts from the preceding days, and how its held-out loss falls with the number of them used as features -- against the same curve for the shuffled record, which stays at the loss of the best constant. Writes the entry's second figure.
LAGFIT_DEPTH = 3
MAX_LAGS = 12
SHOWN_LAGS = (1, 5)
WINDOW = slice(120, 180)
FIT_SPLITS = 20

window_days = np.arange(len(temp))[WINDOW]
series_rows = {"day": window_days, "temp": temp[WINDOW]}
for nrlags in SHOWN_LAGS:
    design, target = lagged_design(temp, nrlags)
    guess = predict_tree(fit_tree(design, target, LAGFIT_DEPTH), design)
    padded = np.concatenate([np.full(nrlags, np.nan), guess])
    series_rows[f"fit{nrlags}"] = padded[WINDOW]
with open(OUT_DIR / "iidasspt_lagfit_series.csv", "w") as f:
    names = ["day", "temp"] + [f"fit{n}" for n in SHOWN_LAGS]
    f.write(",".join(names) + "\n")
    for k in range(len(window_days)):
        f.write(",".join(f"{series_rows[n][k]:.2f}" for n in names) + "\n")

constant_loss = float(np.var(temp))
curve = []
for nr_feat in range(1, MAX_LAGS + 1):
    design, target = lagged_design(temp, nr_feat)
    size = len(target)
    errs = []
    for rep in range(FIT_SPLITS):
        order = np.random.default_rng(100 + rep).permutation(size)
        cut = size // 2
        fit_idx, judge_idx = order[:cut], order[cut:]
        tree = fit_tree(design[fit_idx], target[fit_idx], LAGFIT_DEPTH)
        errs.append(np.mean((target[judge_idx]
                             - predict_tree(tree, design[judge_idx])) ** 2))
    curve.append((nr_feat, float(np.mean(errs))))
with open(OUT_DIR / "iidasspt_lagfit_error.csv", "w") as f:
    f.write("lags,record,constant\n")
    for nr_feat, rec in curve:
        f.write(f"{nr_feat},{rec:.3f},{constant_loss:.3f}\n")

best_rec = min(c[1] for c in curve)
print(f"[B-lagfit] best loss over 1 to {MAX_LAGS} preceding days: "
      f"record {best_rec:.2f}, best constant {constant_loss:.2f}")
check("[B-lagfit] the preceding days predict the record far better than the "
      "best constant", best_rec < 0.25 * constant_loss)
check("[B-lagfit] both figure panels written",
      all((OUT_DIR / n).exists() for n in
          ("iidasspt_lagfit_series.csv", "iidasspt_lagfit_error.csv")))
[B-lagfit] best loss over 1 to 12 preceding days: record 11.76, best constant 84.64
  [ok] [B-lagfit] the preceding days predict the record far better than the best constant
  [ok] [B-lagfit] both figure panels written
The independence check in the terms ML already uses: if the earlier values are useless as features, a hypothesis fitted on them cannot beat the best constant. Fitted on the whole record with one lag and a linear model, the reduction in loss is exactly the squared lag-one correlation. Judged on held-out days, a linear model and a decision tree both reach about 0.86, which no reordering approaches -- and the tree, the larger hypothesis space, does slightly worse on this near-linear relation.
HOLDOUT = 0.5
NR_SPLITS = 20
TREE_DEPTH = 3

insample = loss_reduction(temp)
rho_one = lag_one_correlation(temp)
print(f"[B-predict] fitted on the whole record, one lag, linear: reduction "
      f"{insample:.4f} against a squared lag-one correlation of "
      f"{rho_one ** 2:.4f}")
check("[B-predict] the linear one-lag reduction is the squared correlation",
      abs(insample - rho_one ** 2) < 1e-9)

held_lin = loss_reduction(temp, holdout=HOLDOUT, rng=np.random.default_rng(1),
                          repeats=NR_SPLITS)
held_tree = loss_reduction(temp, depth=TREE_DEPTH, holdout=HOLDOUT,
                           rng=np.random.default_rng(1), repeats=NR_SPLITS)
print(f"[B-predict] judged on held-out days: linear {held_lin:.4f}, decision "
      f"tree of depth {TREE_DEPTH} {held_tree:.4f}")
check("[B-predict] both hypothesis spaces beat the constant on days never "
      "fitted on", held_lin > 0.5 and held_tree > 0.5)
[B-predict] fitted on the whole record, one lag, linear: reduction 0.8839 against a squared lag-one correlation of 0.8839
  [ok] [B-predict] the linear one-lag reduction is the squared correlation
[B-predict] judged on held-out days: linear 0.8845, decision tree of depth 3 0.8615
  [ok] [B-predict] both hypothesis spaces beat the constant on days never fitted on
What that check can and cannot see. On a sequence whose conditional mean is flat, no enlargement of the hypothesis space helps: degrees 1 to 3 all do worse out of sample than the best constant, the polynomial ones worse than the linear one. Only predicting the squared value helps. The reach is set by the hypothesis space AND by what the hypothesis is asked to predict.
reach_rng = np.random.default_rng(1)
noise = reach_rng.standard_normal(3001)
flat = noise[1:] * noise[:-1]
DEPTHS = (1, 2, 3, 4)
by_depth = [loss_reduction(flat, depth=d, holdout=HOLDOUT,
                           rng=np.random.default_rng(2), repeats=NR_SPLITS)
            for d in DEPTHS]
squared = loss_reduction(flat ** 2, depth=TREE_DEPTH, holdout=HOLDOUT,
                         rng=np.random.default_rng(2), repeats=NR_SPLITS)
print(f"[B-reach] predicting the value, tree depths {DEPTHS}: "
      f"{', '.join(f'{v:+.4f}' for v in by_depth)}")
print(f"[B-reach] predicting the squared value, depth {TREE_DEPTH}: "
      f"{squared:+.4f}")
check("[B-reach] no depth helps predict the value", max(by_depth) < 0)
check("[B-reach] and the deeper the tree the worse it does",
      all(by_depth[k] > by_depth[k + 1] for k in range(len(DEPTHS) - 1)))
check("[B-reach] while predicting the squared value does help",
      squared > 0.02)
[B-reach] predicting the value, tree depths (1, 2, 3, 4): -0.0037, -0.0120, -0.0242, -0.0499
[B-reach] predicting the squared value, depth 3: +0.0551
  [ok] [B-reach] no depth helps predict the value
  [ok] [B-reach] and the deeper the tree the worse it does
  [ok] [B-reach] while predicting the squared value does help
Subtracting the seasonal average repairs the identically distributed half only: the lag-one correlation of what is left is still 0.67.
WINDOW = 31
wrapped = np.concatenate([temp[-(WINDOW // 2):], temp, temp[:WINDOW // 2]])
seasonal = np.convolve(wrapped, np.ones(WINDOW) / WINDOW, mode="valid")
residual = temp - seasonal
print(f"[B-deseason] after subtracting the seasonal average the monthly "
      f"means agree to {np.abs([residual[month == k].mean() for k in range(1, 13)]).max():.2f} deg, "
      f"and the lag-one correlation is still "
      f"{lag_one_correlation(residual):.3f}")
check("[B-deseason] the seasonal average is what separates January from July",
      abs(residual[month == 7].mean() - residual[month == 1].mean()) < 2.0)
check("[B-deseason] the dependence survives it",
      lag_one_correlation(residual) > 0.5)
[B-deseason] after subtracting the seasonal average the monthly means agree to 0.55 deg, and the lag-one correlation is still 0.671
  [ok] [B-deseason] the seasonal average is what separates January from July
  [ok] [B-deseason] the dependence survives it
How unlikely the January-July gap is under one common distribution: fit a Gaussian to the whole year, and the gap between two monthly averages is 9.8 standard deviations out.
jan_temp, jul_temp = temp[month == 1], temp[month == 7]
year_mean, year_sd = float(np.mean(temp)), float(np.std(temp, ddof=1))
gap = float(np.mean(jul_temp) - np.mean(jan_temp))
gap_sd = year_sd * math.sqrt(1 / len(jan_temp) + 1 / len(jul_temp))
gap_z = gap / gap_sd
# Upper tail of the standard Gaussian, in logs: the Mills-ratio bound
# 1 - Phi(z) <= exp(-z^2/2) / (z sqrt(2 pi)), tight enough at z near 10.
log10_tail = (-0.5 * gap_z ** 2
              - math.log(gap_z * math.sqrt(2 * math.pi))) / math.log(10)
print(f"[B-gaussgap] year mean {year_mean:.2f}, standard deviation "
      f"{year_sd:.2f}; the gap of {gap:.2f} degrees is {gap_z:.1f} standard "
      f"deviations of {gap_sd:.2f}, a probability below 1e{log10_tail:.0f}")
check("[B-gaussgap] the gap is far outside what one common Gaussian gives",
      gap_z > 9.0 and log10_tail < -21)
[B-gaussgap] year mean 17.91, standard deviation 9.21; the gap of 23.03 degrees is 9.8 standard deviations of 2.34, a probability below 1e-22
  [ok] [B-gaussgap] the gap is far outside what one common Gaussian gives
The two standard methods applied to periods of growing length (January, January to June, the whole year): the largest gap between the empirical CDFs of two 15-day blocks of the period against the Kolmogorov-Smirnov threshold, and the lag-one correlation calibrated by a permutation test. Writes the panels of the entry's third figure.
BLOCK = 15
LEVEL = 0.05
NR_PERM = 2000
PERIODS = [("month", "January", temp[month == 1], np.array(stamps)[month == 1]),
           ("halfyear", "January to June", temp[month <= 6],
            np.array(stamps)[month <= 6]),
           ("year", "the whole year", temp, np.array(stamps))]
verdict = {}
for tag, title, series, days in PERIODS:
    nr_block = len(series) // BLOCK
    blocks = [series[i * BLOCK:(i + 1) * BLOCK] for i in range(nr_block)]
    spans = [f"{days[i * BLOCK][5:10]} to {days[(i + 1) * BLOCK - 1][5:10]}"
             for i in range(nr_block)]
    # the pair of blocks that are furthest apart, ties broken by the means
    gap, spread, first, second = max(
        (ks_statistic(blocks[i], blocks[j]),
         abs(blocks[i].mean() - blocks[j].mean()), i, j)
        for i in range(nr_block) for j in range(i + 1, nr_block))
    corr = lag_one_correlation(series)
    draws = np.array([abs(lag_one_correlation(rng.permutation(series)))
                      for _ in range(NR_PERM)])
    pvalue = (1 + (draws >= abs(corr)).sum()) / (NR_PERM + 1)
    nr_pair = nr_block * (nr_block - 1) // 2
    plain = ks_threshold(BLOCK, LEVEL)
    adjusted = ks_threshold(BLOCK, LEVEL / nr_pair)
    verdict[tag] = (title, len(series), nr_block, gap, corr, pvalue,
                    (blocks[first], spans[first]),
                    (blocks[second], spans[second]),
                    nr_pair, plain, adjusted)
    for label, index in (("early", first), ("late", second)):
        values, fraction = empirical_cdf(blocks[index])
        with open(OUT_DIR / f"iidasspt_cdf_{tag}_{label}.csv", "w") as f:
            f.write("temp,frac\n")
            for a, b in zip(values, fraction):
                f.write(f"{a:g},{b:.4f}\n")
    print(f"[B-verify] {title} ({len(series)} days, {nr_block} blocks of "
          f"{BLOCK} days): largest gap between the empirical CDFs of two "
          f"blocks {gap:.3f} ({spans[first]} against {spans[second]}); the "
          f"correlation of consecutive values is {corr:.3f}, which no "
          f"reordering among {NR_PERM} random ones reaches")
    print(f"[B-verify] {title}: the Kolmogorov-Smirnov threshold at level "
          f"{LEVEL} is {plain:.3f} for a single pair and {adjusted:.3f} after "
          f"dividing the level among the {nr_pair} pairs; the gap "
          f"{'exceeds' if gap > adjusted else 'stays below'} it")
check("[B-verify] the gap between two blocks grows with the length of the "
      "period", verdict["month"][3] < verdict["halfyear"][3] <= verdict["year"][3])
check("[B-verify] six months and a year separate two blocks completely",
      verdict["halfyear"][3] == 1.0 and verdict["year"][3] == 1.0)
check("[B-verify] the lag-one correlation stays above 0.5 on every period",
      all(verdict[tag][4] > 0.5 for tag, _, _, _ in PERIODS))
check("[B-verify] no permutation reaches the observed correlation",
      all(verdict[tag][5] < 2.0 / (NR_PERM + 1) for tag, _, _, _ in PERIODS))
check("[B-verify] January stays below the threshold even for a single pair",
      verdict["month"][3] < verdict["month"][9])
check("[B-verify] the longer periods exceed the threshold that accounts for "
      "every pair of blocks",
      verdict["halfyear"][3] > verdict["halfyear"][10]
      and verdict["year"][3] > verdict["year"][10])
[B-verify] January (31 days, 2 blocks of 15 days): largest gap between the empirical CDFs of two blocks 0.333 (01-01 to 01-15 against 01-16 to 01-30); the correlation of consecutive values is 0.634, which no reordering among 2000 random ones reaches
[B-verify] January: the Kolmogorov-Smirnov threshold at level 0.05 is 0.496 for a single pair and 0.496 after dividing the level among the 1 pairs; the gap stays below it
[B-verify] January to June (182 days, 12 blocks of 15 days): largest gap between the empirical CDFs of two blocks 1.000 (01-01 to 01-15 against 06-14 to 06-28); the correlation of consecutive values is 0.910, which no reordering among 2000 random ones reaches
[B-verify] January to June: the Kolmogorov-Smirnov threshold at level 0.05 is 0.496 for a single pair and 0.725 after dividing the level among the 66 pairs; the gap exceeds it
[B-verify] the whole year (366 days, 24 blocks of 15 days): largest gap between the empirical CDFs of two blocks 1.000 (01-01 to 01-15 against 08-28 to 09-11); the correlation of consecutive values is 0.940, which no reordering among 2000 random ones reaches
[B-verify] the whole year: the Kolmogorov-Smirnov threshold at level 0.05 is 0.496 for a single pair and 0.788 after dividing the level among the 276 pairs; the gap exceeds it
  [ok] [B-verify] the gap between two blocks grows with the length of the period
  [ok] [B-verify] six months and a year separate two blocks completely
  [ok] [B-verify] the lag-one correlation stays above 0.5 on every period
  [ok] [B-verify] no permutation reaches the observed correlation
  [ok] [B-verify] January stays below the threshold even for a single pair
  [ok] [B-verify] the longer periods exceed the threshold that accounts for every pair of blocks

26/26 checks pass
preview
fig = plt.figure(figsize=(12, 9.5))
grid = fig.add_gridspec(3, 4, hspace=0.6, wspace=0.55)
for column, (_, tag, title) in enumerate(MONTHS):
    ax = fig.add_subplot(grid[0, column])
    day, values, _ = month_series[tag]
    ax.plot(day, values, color="0.3", linewidth=0.5)
    ax.set_xlabel("day of the month (UTC)")
    ax.set_ylabel("temperature in deg C")
    ax.set_ylim(-12, 38)
    ax.set_title(f"{title} 2024, daily maximum", fontsize=9)
ax = fig.add_subplot(grid[1, 0])
ax.plot(series_rows["day"], series_rows["temp"], color="0.2", linewidth=1.1,
        label="the record")
for style, nrlags in zip(("--", ":"), SHOWN_LAGS):
    ax.plot(series_rows["day"], series_rows[f"fit{nrlags}"], style,
            color="0.45", linewidth=1.1, label=f"{nrlags} preceding day(s)")
ax.set_xlabel("day of 2024")
ax.set_ylabel("daily maximum in deg C")
ax.set_title("what a decision tree predicts", fontsize=9)
ax.set_ylim(14, 42)
ax.legend(frameon=False, fontsize=8, ncol=3, loc="upper center",
          columnspacing=0.9, handlelength=1.4)
ax = fig.add_subplot(grid[1, 1])
lags_axis = [c[0] for c in curve]
ax.plot(lags_axis, [c[1] for c in curve], "-o", color="0.2", markersize=3.5,
        label="the record")
ax.axhline(constant_loss, color="0.3", linestyle=":", linewidth=0.9)
ax.set_xlabel("number of preceding days used")
ax.set_ylabel("held-out squared error loss")
ax.set_title("loss against the number of lags", fontsize=9)
ax.legend(frameon=False, fontsize=8)
for column, (tag, title, _, _) in enumerate(PERIODS):
    ax = fig.add_subplot(grid[2, column])
    for (block, span), style in ((verdict[tag][6], "-"),
                                 (verdict[tag][7], "--")):
        values, fraction = empirical_cdf(block)
        ax.step(values, fraction, style, where="post", color="0.3",
                linewidth=1.2, label=span)
    ax.set_xlabel("daily maximum in deg C")
    ax.set_ylabel("fraction at or below")
    ax.set_title(f"{title}: largest gap {verdict[tag][3]:.2f}", fontsize=9)
    ax.legend(frameon=False, fontsize=8)
fig.suptitle("Krems 2024: the two halves of the i.i.d. property, checked by "
             "prediction and by comparing blocks", fontsize=11)
fig.savefig(OUT_DIR / "iidasspt.png", dpi=110, bbox_inches="tight")

passed = sum(ok for _, ok in report)
print(f"\n{passed}/{len(report)} checks pass")
if passed != len(report):
    raise SystemExit(1)
B-plot writes when the script runs