pca.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-11-02
Readiness 100/100
See also feature learning autoencoder dimensionality reduction eigenvalue decomposition eigenvalue empirical risk minimization robust principal component analysis
Principal component analysis (PCA) is the linear case of feature learning: it maps the feature vector of a data point to a vector of fewer entries by a linear map, chosen so that a second linear map rebuilds the original as well as possible. The criterion is the reconstruction error on a dataset whose labels, if it has any, are not used, since what has to be reproduced is the data point itself, which makes PCA an instance of empirical risk minimization (ERM) with the squared error loss. The linear map that minimizes this error is given by the eigenvectors of the sample covariance matrix belonging to its largest eigenvalues, so PCA is computed by an eigenvalue decomposition (EVD). The error left is the sum of the eigenvalues that are dropped, which gives the error of every choice of the number of retained directions in advance. Each eigenvalue is the variance along its eigenvector, so the first direction is the one of largest variance. An autoencoder keeps the same criterion with artificial neural networks (ANNs) in place of the two linear maps.
pca.py, which recomputes what the entry states: the script block by block · open in ColabA weather station at Krems an der Donau records eight numbers for each day of 2024: the lowest, highest and mean air temperature, precipitation, sunshine duration, humidity, air pressure and wind speed. Eight numbers per day are more than a scatterplot can show, and one of them, the mean temperature, is the midpoint of two others to within the precision of the archive. PCA replaces the eight by fewer, chosen so that a second linear map rebuilds the originals from the few with the smallest average squared error.
PCA is the linear case of feature learning, and its criterion is the reconstruction error. The encoder is a linear map \[{\mathbf \Phi}^{({\mathbf W})}: \mathbb{R}^{d} \rightarrow \mathbb{R}^{d'}: {\mathbf x} \mapsto {\mathbf W} {\mathbf x} \text{,}\] given by a matrix ${\mathbf W} \in \mathbb{R}^{d' \times d}$ with $d' < d$, and the decoder is a linear map ${\mathbf R} \in \mathbb{R}^{d \times d'}$ that rebuilds the raw feature vector from the code, the lower-dimensional representation ${\mathbf z} = {\mathbf W} {\mathbf x}$ of the data point. The usefulness of a specific ${\mathbf W}$ is the minimum reconstruction error it leaves on a dataset $\mathcal{D} = \big\{ {\mathbf x}^{(1)}, \ldots, {\mathbf x}^{(m)} \big\}$ of feature vectors ${\mathbf x}^{(r)} \in \mathbb{R}^{d}$ with sample mean zero, the decoder being learned alongside the encoder (Bishop, 2006; Hastie et al., 2009, Sect. 14.5.1; Hotelling, 1933): \begin{equation} \label{eq:pca_reconstruction} \min_{{\mathbf R} \in \mathbb{R}^{d \times d'}} \frac{1}{m} \sum_{r=1}^{m} \left\lVert {\mathbf x}^{(r)} - {\mathbf R} {\mathbf W} {\mathbf x}^{(r)} \right\rVert_{2}^{2} \text{.} \end{equation} Minimizing over ${\mathbf R}$ and ${\mathbf W}$ jointly yields the same pair; the inner minimum is taken first so that the reconstruction error becomes a loss function of ${\mathbf W}$ alone. No labels appear in the reconstruction error \(\eqref{eq:pca_reconstruction}\): the decoder has to reproduce the data point itself. PCA is therefore an instance of empirical risk minimization (ERM) whose loss function is the squared error loss $L\left({\mathbf x},{\mathbf W} \right) = \left\lVert {\mathbf x} - \widehat{{\mathbf R}} {\mathbf W} {\mathbf x} \right\rVert_{2}^{2}$, for the decoder $\widehat{{\mathbf R}}$ that attains the minimum.
B-directionsThe eigenvectors of the sample covariance matrix solve the reconstruction problem \(\eqref{eq:pca_reconstruction}\). The feature vectors are centered, i.e., their sample mean is zero, which is what makes the following matrix the sample covariance matrix: \[\widehat{\mathbf{Q}} = \frac{1}{m} \sum_{r=1}^{m} {\mathbf x}^{(r)} \big( {\mathbf x}^{(r)} \big)^{\top} \text{,}\] and it is positive semi-definite (psd), so its eigenvalue decomposition (EVD) is a spectral decomposition, $\widehat{\mathbf{Q}} = \sum_{j=1}^{d} \lambda_{j} \mathbf{u}^{(j)} \big( \mathbf{u}^{(j)} \big)^{\top}$ with eigenvalues $\lambda_{1} \geq \cdots \geq \lambda_{d} \geq 0$ and eigenvectors $\mathbf{u}^{(1)}, \ldots, \mathbf{u}^{(d)}$ forming an orthonormal basis of $\mathbb{R}^{d}$ (Horn and Johnson, 2013; Meyer, 2000, p. 549).
Restricting the decoder ${\mathbf R}$ to orthonormal columns loses no generality, since the products ${\mathbf R} {\mathbf W}$ range over the matrices of rank at most $d'$ either way. For such an ${\mathbf R}$ the encoder attaining the minimum is the transpose ${\mathbf W} = {\mathbf R}^{\top}$ (Goodfellow et al., 2016, Sect. 2.12, Eq. (2.66); Hastie et al., 2009, Sect. 14.5.1, Eq. (14.52)): the best code holds the inner products ${\mathbf R}^{\top} {\mathbf x}$ of ${\mathbf x}$ with the orthonormal columns of ${\mathbf R}$. The reconstruction ${\mathbf R} {\mathbf R}^{\top} {\mathbf x}$ is therefore the orthogonal projection of ${\mathbf x}$ onto the subspace they span. That projection is orthogonal to the error it leaves, and \[\left\lVert {\mathbf x} - {\mathbf R} {\mathbf R}^{\top} {\mathbf x} \right\rVert_{2}^{2} = \left\lVert {\mathbf x} \right\rVert_{2}^{2} - \left\lVert {\mathbf R}^{\top} {\mathbf x} \right\rVert_{2}^{2} \text{.}\]
B-decoderAveraging over all data points in $\mathcal{D}$ turns the reconstruction error \(\eqref{eq:pca_reconstruction}\) into ${\rm tr} \left(\widehat{\mathbf{Q}}\right) - {\rm tr} \left({\mathbf R}^{\top} \widehat{\mathbf{Q}} {\mathbf R}\right)$. The first trace does not depend on ${\mathbf R}$, so minimizing the error is maximizing the second over matrices with orthonormal columns. That maximum is $\sum_{j=1}^{d'} \lambda_{j}$, attained by the eigenvectors belonging to the $d'$ largest eigenvalues (Goodfellow et al., 2016, Sect. 2.12, Eq. (2.84)). A matrix ${\mathbf W} = \big( \mathbf{u}^{(1)}, \ldots, \mathbf{u}^{(d')} \big)^{\top}$ whose rows are those eigenvectors therefore minimizes the criterion \(\eqref{eq:pca_reconstruction}\), paired with the decoder $\widehat{{\mathbf R}} = {\mathbf W}^{\top}$. The minimum reconstruction error is $\sum_{j=d'+1}^{d} \lambda_{j}$, the eigenvalues left out, so the spectrum of $\widehat{\mathbf{Q}}$ gives the reconstruction error of every code length in advance.
B-traceThe eigenvectors $\mathbf{u}^{(1)}, \ldots, \mathbf{u}^{(d)}$ of $\widehat{\mathbf{Q}}$ are the principal directions of the dataset, ordered by decreasing eigenvalue. Stacking the centered feature vectors row-wise into the feature matrix ${\mathbf X} \in \mathbb{R}^{m \times d}$ writes the sample covariance matrix as $\widehat{\mathbf{Q}} = (1/m) {\mathbf X}^{\top} {\mathbf X}$, so they are equally the eigenvectors of ${\mathbf X}^{\top} {\mathbf X}$. The first $d'$ of them span the subspace that PCA keeps, and each feature vector is replaced by its orthogonal projection onto it. That projection is the approximation whose squared error loss the reconstruction error \(\eqref{eq:pca_reconstruction}\) measures. The inner products of ${\mathbf x}$ with the first $d'$ principal directions are its coordinates in that subspace, and they are the new features PCA delivers.
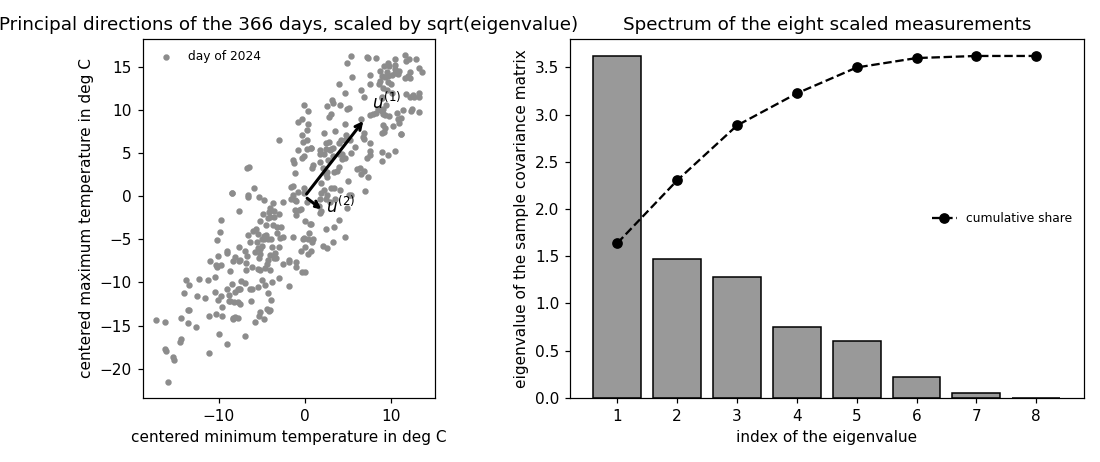
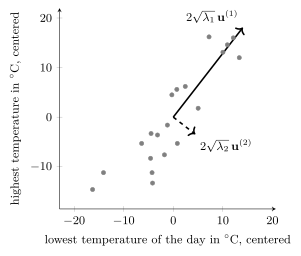
The eigenvalues of $\widehat{\mathbf{Q}}$ are the
variances of the data along its eigenvectors,
so $\mathbf{u}^{(1)}$ is the direction of largest
variance. Fig. 1 shows
the two directions for the days at Krems taken with two
features, the lowest and the highest temperature of the
day (both centered). Their eigenvalues are $130.9$ and $7.9$ squared
degrees, whose square roots are the standard deviations along them.
pythondemos/pca.py
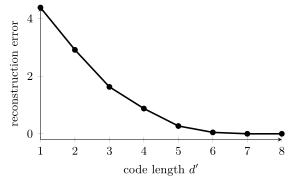
B-redundantThe code length $d'$ is a hyperparameter. Each
number added to the code removes exactly the next eigenvalue
from the error, and the ones removed first are the largest
(see Fig. 2). No choice is optimal on the
criterion itself, which falls to zero at
$d' = d$, where nothing is compressed. What
picks $d'$ is the use the code is put to: a
scatterplot needs two, a later learning task can be
given the validation error of each length to choose from, and a
storage budget fixes it outright.
pythondemos/pca.py
These numbers are averages over the dataset the eigenvectors were computed from. Whether the subspace also rebuilds data points outside it is the question of generalization. The answer depends on how well $\widehat{\mathbf{Q}}$ estimates the covariance matrix of data points outside the dataset.
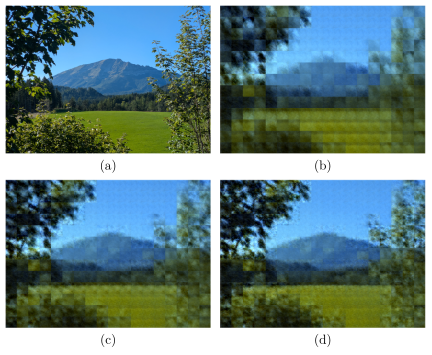
B-compressThe same criterion compresses images. Cutting a photograph into
patches of $64 \times 64$ pixels makes each patch a
data point with $12288$ features, three color values
per pixel, and PCA replaces those by a code of $d'$
numbers (see Fig. 3). At
$d' = 5$ the mountain and the meadow are already in
place while the patch boundaries still show; at $15$ the
reconstruction is close to the original.
pythondemos/pca.py
B-plotSparse principal component analysis (sparse PCA) keeps the criterion but adds a penalty on the entries (loadings) of an eigenvector. Each direction then involves few features and can be interpreted as a named combination of them. On the eight measurements, four loadings, the three temperatures and the sunshine duration, keep $81\%$ of the variance of $\mathbf{u}^{(1)}$ (Zou et al., 2006).
Robust principal component analysis (robust PCA) replaces the squared error loss, which a single grossly corrupted entry can dominate, by a decomposition of the data matrix into a part of low rank plus a part with few nonzero entries. A small number of faulty measurements then falls into the second part instead of tilting the directions (Candès et al., 2011).
An autoencoder keeps the reconstruction error \(\eqref{eq:pca_reconstruction}\) as its criterion and replaces the two linear maps by artificial neural networks (ANNs), which is the nonlinear counterpart of PCA. With a linear decoder and the squared error loss it reconstructs into the same subspace as PCA (Goodfellow et al., 2016, Sect. 14.1).
See also: feature learning, feature transformation, spectrum, encoder, decoder, autoencoder, dimensionality reduction, eigenvalue decomposition, spectral decomposition, sample covariance matrix, eigenvector, eigenvalue, empirical risk minimization, subspace, probabilistic principal component analysis, sparse principal component analysis, robust principal component analysis.
@misc{dictml_pca,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {principal component analysis (PCA)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-03},
  url = {https://dictionaryofml.org/terms/pca.html}
}