autoencoder.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-31
Readiness 100/100
See also feature learning dimensionality reduction principal component analysis empirical risk minimization self-supervised learning transfer learning artificial neural network
An autoencoder is a machine learning (ML) method that learns an encoder and a decoder together. The encoder maps the feature vector of a data point to a new feature vector, referred to as code. The decoder reconstructs the original feature vector from the code. The code delivered by the encoder is typically much shorter than the original feature vector, so the code can retain only part of the information in the feature vector. Different autoencoders use different choices for the hypothesis spaces from which the encoder and the decoder are chosen. Principal component analysis (PCA) is obtained as the special case where both are linear maps, and a deep autoencoder uses a deep net on each side.
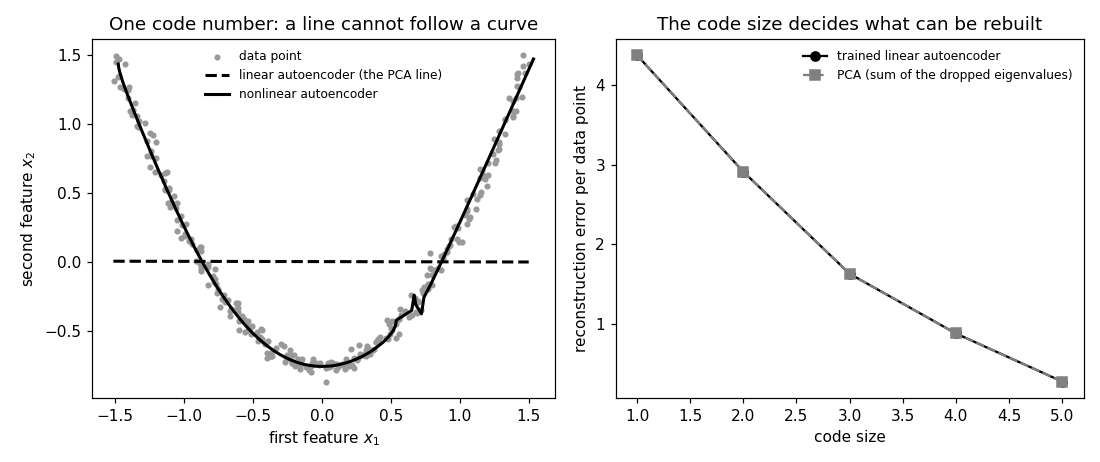
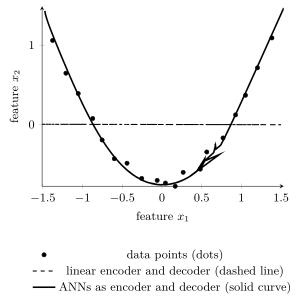
autoencoder.py, which recomputes what the entry states: the script block by block · open in ColabB-linearThree hundred points along a curve
in the plane (Fig. 3) can each be
stored as a single number from which the point is rebuilt almost
exactly, and an image can likewise be stored as a short code from
which a close copy is rebuilt. An autoencoder learns an
encoder $h$ from a hypothesis space $\mathcal{H}$
along with a decoder $h^{*}$ from a second
hypothesis space $\mathcal{H}^{*}$
(Goodfellow et al., 2016, Ch. 14). The encoder maps the
feature vector ${\mathbf x} \in \mathbb{R}^{d}$ of a
data point to a code ${\mathbf z} = h({\mathbf x}) \in
\mathbb{R}^{d'}$. The decoder maps the code back to a
reconstruction $\widehat{{\mathbf x}} = h^{*}({\mathbf z})$ of
the original feature vector (see
Fig. 1). The encoder and the
decoder can be learnt via empirical risk minimization (ERM) with a loss that
measures the reconstruction error ${\mathbf x} -
h^{*}(h({\mathbf x}))$, such as the
squared error loss (Goodfellow et al., 2016, Sect. 14.1),
\begin{equation}
\label{eq:autoencoder_erm}
\min_{h \in \mathcal{H},\; h^{*} \in \mathcal{H}^{*}}
\frac{1}{m} \sum_{r=1}^{m}
L\Big( {\mathbf x}^{(r)},\,
h^{*}\big( h\big( {\mathbf x}^{(r)} \big) \big) \Big)
\text{,}
\end{equation}
The training set needs no labels: what the decoder
has to reproduce is the data point itself, so an autoencoder
is a form of self-supervised learning, as it does not require
manual labeling.
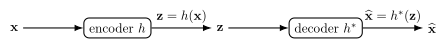
B-nonlinearDifferent autoencoder methods are obtained by different choices
for the hypothesis spaces $\mathcal{H}$, $\mathcal{H}^{*}$ and the
loss function in \(\eqref{eq:autoencoder_erm}\). The special case
of linear maps for the encoder and the decoder,
paired with the squared error loss, coincides with principal component analysis (PCA)
(Goodfellow et al., 2016, Sect. 14.1). For some applications,
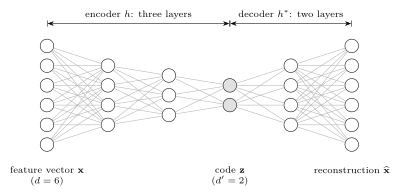
nonlinear encoder and decoder maps represented by
artificial neural networks (ANNs) are more useful, and a deep autoencoder uses a
deep net on each side (Fig. 2).
On the curve of
Fig. 3, a code of one number and one
hidden layer on each side leave an average squared error loss of
$0.003$, against $0.457$ for the best linear map with the same
code. The gain is not the ANNs as such
but the shape of the reconstruction: linear maps with a code
of one number can only place the reconstructions on a straight
line, and these data points do not lie on one.
pythondemos/autoencoder.py
See also: encoder, decoder, feature learning, feature transformation, dimensionality reduction, principal component analysis, empirical risk minimization, squared error loss, self-supervised learning, transfer learning, artificial neural network, deep net.
@misc{dictml_autoencoder,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {autoencoder},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-03},
  url = {https://dictionaryofml.org/terms/autoencoder.html}
}