An artificial neural network (ANN) is a hypothesis space whose
hypothesis maps are all built on one directed graph. Each
hypothesis in this space is a
map from the features of a data point to a
prediction for the label, obtained for a particular choice
of the learnable model parameters carried by the graph's edges (edge weights) and nodes (offset terms). Each node is an artificial neuron
that applies an activation function to the weighted sum of its inputs plus its
offset. The connectivity pattern, the architecture, is an important
design choice: a feedforward network uses a directed acyclic graph (DAG),
whereas a recurrent neural network (RNN) allows a cycle. Depending on the
connectivity, ANNs include deep nets, convolutional neural networks (CNNs),
RNNs, and transformer-based architectures.
B-dagThe face recognition of a
smartphone camera and the speech transcription of a voice assistant are
computed by ANNs whose connection strengths were learned from data
(Goodfellow et al., 2016, Sects. 12.2 and 12.3). An ANN is a
hypothesis space whose hypothesis maps are all built on one
directed graph: the graph fixes which artificial neurons
feed which. A choice of the edge weights and offset terms then selects
one hypothesis map, from the features of a data point at the
input to an output used as the prediction for the label. The
nodes of the graph represent elementary computational units, the
artificial neurons; these are connected via weighted links (or
edges), and the nodes are often assigned offset terms. Together with
the edge weights, these offset terms form the learnable
model parameters $\weights$ of an ANN, and each map in the
space is obtained for a particular choice of $\weights$: the learned
hypothesis $\learnthypothesis = \hypothesis^{(\widehat{\weights})}$
is one such choice.
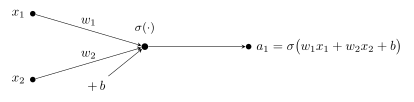
B-layersEach artificial neuron applies an activation function $\actfun(\cdot)$ to
the weighted sum of its inputs plus an offset term
(Fig. 1). The activation function can itself carry
model parameters (parametric activation functions, He et al., 2015),
but it is customarily prescribed in advance, for example the rectified linear unit (ReLU)
(Goodfellow et al., 2016, Sect. 6.3), so that only the node-wise
offset and the edge weights are learned.
Figure 1: A single artificial neuron: it applies an
activation function $\actfun(\cdot)$ to the weighted sum
$w_{1} \feature_1 + w_{2} \feature_2$ of its inputs plus an
offset term $b$, and delivers the output $a_{1}$. The edge weights $w_{1}$, $w_{2}$ and the offset $b$ are learnable
model parameters
The output
of a neuron can be used either as the final output of the
ANN or as an input to other neurons. The directed graph
of the ANN records these uses: its nodes are the
artificial neurons together with the input features,
and each directed edge carries the output of one node to the
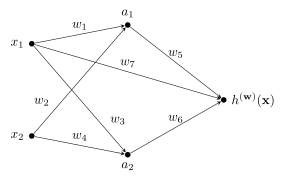
input of another (Fig. 2). Which outputs
are connected to which downstream neuron's inputs, the
connectivity structure (or architecture) of the ANN, is therefore an
important design aspect (Goodfellow et al., 2016). Whether the
graph is acyclic or contains a cycle separates the two broad families
of ANN.
Figure 2: An ANN represented as a weighted, acyclic directed graph
with nodes
corresponding to neurons or features of
a data point. Feature nodes $\feature_1$,
$\feature_2$ have a fixed output given by the
feature value, with no input. Each of the neuron
nodes $a_{1}$, $a_{2}$ applies an activation function to the weighted sum of its inputs (each as in
Fig. 1, whose offset terms are omitted
here). The weighted directed edges, with arrowheads marking the direction of
signal flow, indicate how node outputs are used as inputs
to downstream neurons.
The edge weights are tunable model parameters and are
used to scale the inputs to the neurons. The prediction $\hypothesis^{(\weights)}(\featurevec)$ is the final
output of the ANN, computed from the inputs $\feature_1$, $a_1$,
and $a_2$
The graph of Fig. 2 is acyclic, so this ANN is feedforward (Goodfellow et al., 2016, Ch. 6): the
signal passes from the inputs to the output
without returning to any node.
One widely used type of ANN is deep nets
where neurons form consecutive layers
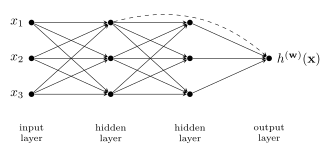
(Fig. 3). In a deep net, the
outputs of neurons in a given layer are typically only connected
to the inputs of the neurons in a consecutive layer. By
contrast, in the general directed acyclic graph (DAG) of Fig. 2
an output may feed any downstream neuron, and there
$\feature_1$ connects straight to the prediction.
B-tuneEach layer $l$ then applies a feature transformation
$\featuretrafovec^{(l)}$ whose components are computed by the
neurons of that layer (each as in
Fig. 1), and the deep net computes
the concatenation of these layer-wise maps. A shortcut or skip connection directly connects the outputs
of neurons in one layer to the inputs of neurons
in a nonconsecutive layer (Goodfellow et al., 2016;
He et al., 2016); Fig. 3 shows one
as a dashed edge. With that edge removed, the network of
Fig. 3 delivers the prediction
\[\hypothesis^{(\weights)}(\featurevec)
= \featuretrafovec^{(3)}\Big(\featuretrafovec^{(2)}
\big(\featuretrafovec^{(1)}(\featurevec)\big)\Big)
\text{.}\]
Here, the input is the feature vector
$\featurevec = (\feature_1, \feature_2, \feature_3)^{\top}$.
The two hidden layers compute
$\featuretrafovec^{(1)}, \featuretrafovec^{(2)}:
\reals^{3} \rightarrow \reals^{3}$, and the output layer
computes $\featuretrafovec^{(3)}: \reals^{3} \rightarrow
\reals$.
Figure 3: A deep net: the neurons form consecutive
layers, and each neuron receives only the
outputs of the preceding layer. Every solid edge carries a learnable edge weight (not drawn). The
dashed edge is a skip connection, directly connecting
two nonconsecutive layers
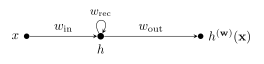
The graphs seen so far are acyclic. A recurrent neural network (RNN) instead
includes a feedback edge (Goodfellow et al., 2016, Ch. 10), so its graph contains a cycle and is not a
DAG (Fig. 4): a self-loop feeds a
neuron's output back to its own input. This feedback
lets the network carry information across the steps of a
sequence; unrolling the recurrence over the sequence,
one copy of each neuron per step, recovers a DAG.
Figure 4: A simple RNN. The self-loop on the hidden
neuron $h$ (edge weight $w_{\mathrm{rec}}$) feeds its
output back to its own input, so the graph contains a cycle
and is not a DAG. The feedback carries information across the
steps of a sequence
The networks of Figs. 2, 3,
and 4 differ only in which nodes their directed
edges join. This connectivity pattern names the common architectures.
Feedforward networks have an acyclic graph, a DAG
(deep nets are the layered case), while convolutional neural networks (CNNs) are also feedforward but share
weights across spatial positions. RNNs add feedback
connections for sequence processing,
and transformer-based architectures, which underlie modern
large language models (LLMs), are likewise feedforward and use attention to connect
every token to every other. Skip connections recur across
these architectures as the residual connections of deep CNNs
(He et al., 2016) and transformers (Vaswani et al., 2017).
The architecture need not be chosen by hand: neural
architecture search learns a useful connectivity automatically
(Elsken et al., 2019). Each architecture fixes a different
hypothesis space, within which empirical risk minimization (ERM) learns a single hypothesis
$\learnthypothesis = \hypothesis^{(\widehat{\weights})}$ by choosing the
model parameters $\widehat{\weights}$ that minimize the average loss
on a training set. The architecture also governs the generalization
of the learned hypothesis to data points outside the
training set, which is what the choice of an architecture is judged by.
See also:label, artificial neuron, activation function,
deep net, layer, convolutional neural network, recurrent neural network,
transformer.
References
Goodfellow et al. (2016). Deep Learning. MIT Press.
He et al. (2015). Delving Deep into Rectifiers: Surpassing Human-Level Performance on ImageNet Classification. 2015 IEEE Int. Conf. Comput. Vis. (ICCV). doi.org/10.1109/ICCV.2015.123
He et al. (2016). Deep Residual Learning for Image Recognition. 2016 IEEE Conf. Comput. Vis. Pattern Recognit.. doi.org/10.1109/CVPR.2016.90