A transformer is an artificial neural network (ANN) built by composing layers,
each of which transforms the features of a data point
made up of smaller units, so-called tokens, such as the
words of a text or the patches of an image. The feature vectors of the tokens are
stacked into a matrix; each layer maps this
matrix to one of the same shape, so that layers can
be composed freely into a deep ANN. The layers
alternate between token mixing, which combines information across
tokens, and a position-wise multilayer perceptron (MLP),
which transforms each token separately.
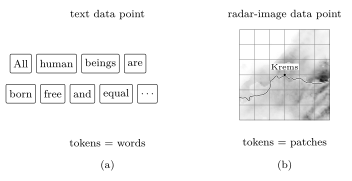
B-riverA text consists of words, and an image consists of
patches of pixels (see Fig. 1): the
data points of many machine learning (ML) applications consist of smaller
units, so-called tokens.
A transformer is an artificial neural network (ANN) that is built by composing
layers, each of which transforms the features of
such a token-based data point
(Vaswani et al., 2017).
Figure 1: Two data points that consist of tokens.
(a) The opening words of the Universal Declaration of
Human Rights (United Nations General Assembly, 1948); each word is one
token. (b) A weather-radar-based image of the
one-hour precipitation around Krems an der Donau, Austria
(August 20, 2026; INCA
(Integrated Nowcasting through Comprehensive Analysis)
analysis, GeoSphere Austria), with $96 \times 96$ pixels of 1 km; darker
pixels indicate more precipitation, and thin gray lines cut
the image into $16 \times 16$-pixel patches, each of which is
one token. The black line, drawn with a white casing so
it stays visible over dark pixels, marks the course of the
Danube, and the dot at the image center the location of Krems
(river course: OpenStreetMap contributors). Data generated by
pythondemos/transformer.py
The feature vectors (or embeddings)
${\mathbf x}^{(1)}, \ldots, {\mathbf x}^{(n)} \in \mathbb{R}^{d}$
of the $n$ tokens are stacked into a matrix
${\mathbf X} = \big({\mathbf x}^{(1)}, \ldots, {\mathbf x}^{(n)}\big)^{\top}
\in \mathbb{R}^{n \times d}$. Each layer of
the original transformer maps such a matrix to a transformed
matrix of the same shape, so that layers can be
composed freely into a deep ANN
(Vaswani et al., 2017, Sect. 3.1). For example, a transformer that
translates a sentence transforms the stacked word embeddings,
layer by layer, into feature vectors from which the
translated words are predicted (Vaswani et al., 2017);
transformers also process images by taking patches as
tokens (Dosovitskiy et al., 2021). Contemporary
large language models (LLMs), such as GPT-3, are transformers trained to predict
the next token of a text (Brown et al., 2020).
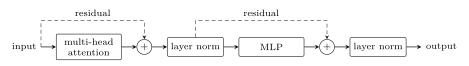
The layers of a transformer alternate between two types of
transformations of ${\mathbf X}$ (see Fig. 2).
A token-mixing layer maps ${\mathbf X}$ to a new matrix
$\widetilde{{\mathbf X}}$, each row of which is a weighted sum of linear
images of the rows of ${\mathbf X}$, with weights that can depend on
${\mathbf X}$ itself; the tokens thereby interact. In the original
transformer, token mixing is implemented by multi-head
attention, whose output for each token is a
weighted sum of the value vectors, the rows of ${\mathbf X}$ multiplied
by a learned matrix
(Vaswani et al., 2017, Sect. 3.2). Attention distinguishes
transformers from recurrent neural networks (RNNs), which process the
tokens of a data point sequentially instead of in
parallel (Vaswani et al., 2017, Sect. 1). A
position-wise multilayer perceptron (MLP) then transforms each row
of $\widetilde{{\mathbf X}}$ separately
(Vaswani et al., 2017, Sect. 3.3). For each of the two
transformations, a residual connection adds the input of the
transformation to its output, and a subsequent
layer normalization standardizes each row of the
resulting matrix (Vaswani et al., 2017, Sect. 3.1).
Figure 2: One transformer block. Each of the two
transformations, multi-head attention for token
mixing and a position-wise MLP,
is bypassed by a residual connection (dashed arrow) whose
output is added back and passed through
layer normalization. The largest Llama 3 LLM
stacks more than 120 of such blocks
(Grattafiori and others, 2024, Sect. 3.2)
The matrices produced by successive layers represent
the tokens at increasingly abstract levels. This
progression is measured by probing: a simple classifier is
trained to predict a chosen property from the output of a single
layer, and the depth at which the property becomes
predictable locates it in the network. In a language transformer,
word-level properties are predictable from the output of
early layers. One example is a part-of-speech tag, which
marks whether a word is a noun, a verb, or an adjective.
Relations between tokens far apart in the text become
predictable only in deeper layers
(Tenney et al., 2019).
Deep convolutional neural networks (CNNs) show the same
progression, from edges and textures in early layers to
object parts in deeper ones (Zeiler and Fergus, 2014). Vision
transformers develop it too: their early layers split
attention between nearby and distant patches, while the
deeper layers attend across the whole image
(Raghu et al., 2021). In language and vision transformers alike, the most informative
representations often arise in the middle layers, whose
outputs can outperform
those of the final layer as features for other tasks
(Skean et al., 2025).
Whatever the layers represent, computing them is dominated
by the token mixing that produces the matrix of each
layer, which is computationally expensive. Attention
compares every pair of tokens, so
its cost grows as $n^{2}$ with the number $n$ of
tokens (Tay et al., 2022, Sect. 2.4). This quadratic growth
motivates alternative techniques for token mixing. Some
transformer variants reduce the number of tokens in deeper
layers (Tay et al., 2022). Any transformation that
combines the rows of ${\mathbf X}$ can replace attention: an
MLP applied across tokens
(Tolstikhin et al., 2021), a fixed Fourier transform
(Lee-Thorp et al., 2022), or a state-space layer
whose cost is linear in $n$ (Gu and Dao, 2024, Sect. 3.3).
See also:attention, artificial neural network, layer, token,
embedding, word embedding, recurrent neural network, natural language processing,
large language model, multilayer perceptron,
residual connection, layer normalization,
convolutional neural network.
Dosovitskiy et al. (2021). An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. Int. Conf. Learn. Represent. (ICLR). openreview.net/forum?id=YicbFdNTTy
Tenney et al. (2019). BERT Rediscovers the Classical NLP Pipeline. Proc. 57th Ann. Meeting Assoc. Comput. Linguistics. doi.org/10.18653/v1/P19-1452
Zeiler and Fergus (2014). Visualizing and Understanding Convolutional Networks. Proc. European Conf. Comput. Vis. (ECCV). doi.org/10.1007/978-3-319-10590-1_53
Skean et al. (2025). Layer by Layer: Uncovering Hidden Representations in Language Models. Proc. 42nd Int. Conf. Mach. Learn. (ICML). openreview.net/forum?id=WGXb7UdvTX
Tay et al. (2022). Efficient Transformers: A Survey. ACM Computing Surveys. doi.org/10.1145/3530811
Lee-Thorp et al. (2022). FNet: Mixing Tokens with Fourier Transforms. Proc. 2022 Conf. North Amer. Chapter Assoc. Comput. Linguistics: Human Lang. Technologies. doi.org/10.18653/v1/2022.naacl-main.319
Gu and Dao (2024). Mamba: Linear-Time Sequence Modeling with Selective State Spaces. Conf. Language Modeling. openreview.net/forum?id=tEYskw1VY2