llm.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-29
Readiness 100/100
See also transformer attention artificial neural network pretraining fine-tuning
A large language model (LLM) is an artificial neural network (ANN), typically with billions of model parameters, that implements a hypothesis map from a prompt to a response. The training of an LLM often proceeds in stages: pretraining uses self-supervised learning, splitting raw text into overlapping fragments that yield data points without manual annotation, and fine-tuning uses a small dataset of manually curated prompt–response pairs. LLM agents extend LLMs beyond text: a program interprets the response, for example as code to run or as a tool to execute, and can append the result to the next prompt, so the LLM chooses actions that the surrounding program carries out.
llm.py, which recomputes what the entry states: the script block by block · open in ColabConsider a chat-based
artificial intelligence (AI) system such as ChatGPT, Claude, Gemini, DeepSeek, or
Mistral: a user types a question, the prompt, and receives
a reply, the response. The system that produces the reply is an
LLM: an artificial neural network (ANN), typically a transformer
(Vaswani et al., 2017) with billions of model parameters
(Brown et al., 2020), trained to produce output text given input text. Each
data point of this learning task is a pair of texts, and
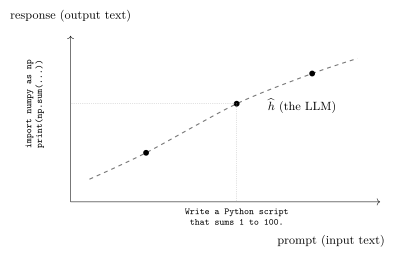
the trained LLM implements a hypothesis map from the prompt
to the response (Fig. 1). A prompt and a response
are sequences of tokens, so the feature space
and the label space of this learning task are sets of
token sequences. In contrast, a text
classifier that maps a document to one of a fixed set of
labels is not an LLM: it returns a label, not
text.
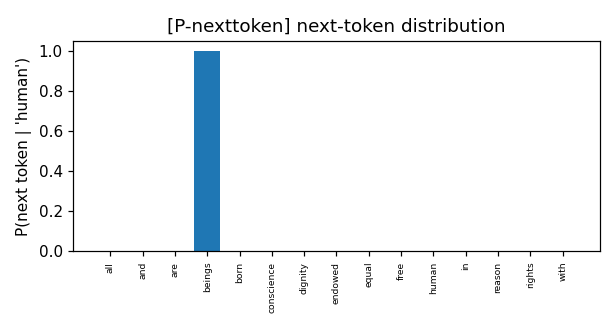
B-trainThe training of an LLM consists of several stages. One stage typically uses self-supervised learning: a given text is split into overlapping fragments, and each fragment amounts to a data point whose label is one of its tokens and whose features are the remaining tokens. Training sets built from text fragments require no manual annotation; a next-token fragment construction is used by Brown et al. (2020) and a masked-token one by Devlin et al. (2019). Pretraining then minimizes the average loss over the fragments, i.e., it is empirical risk minimization (ERM), the aim being a small expected loss on text fragments outside the training set. Another stage is fine-tuning, which uses a small dataset of manually curated prompt–response pairs (Ouyang et al., 2022). The pretrained model parameters are what fine-tuning adapts to each task; an LLM whose model parameters are reused across many learning tasks in this way is a foundation model (Bommasani et al., 2021).
LLM inference, i.e., computing the response for a given prompt, is computationally much cheaper than its training. Still, the inference itself is computationally costly and is often implemented using cloud computing services. An LLM can also run locally: open-weight LLMs, whose model parameters are published (Touvron et al., 2023), can be compressed by quantization (Dettmers et al., 2022). Quantization stores each model parameter in a few bits instead of a $16$-bit floating-point number. An LLM with billions of model parameters then runs on a laptop or phone (see edge computing).
B-agentThe output of an LLM by itself is nothing but a sequence of letters that constitute the response. An LLM (or coding) agent interprets the response of an LLM as instructions for computations to be executed (Yao et al., 2023). For example, the prompt can instruct the LLM to produce a response that is valid source code in a programming language such as Python, as in the spelled-out data point of Fig. 1. The delivered source code can then be executed, and the result can be appended to the next prompt. The response can likewise be read as a call to an external tool, so that the LLM generates the text that specifies the actions the surrounding program carries out.
See also: token, vocabulary, transformer, attention, artificial neural network, word embedding, softmax function, natural language processing, foundation model, pretraining, fine-tuning, agent, cloud computing, edge computing.
@misc{dictml_llm,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {large language model (LLM)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-04},
  url = {https://dictionaryofml.org/terms/llm.html}
}