mlpipeline.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-29
Readiness 93/100
See also feature learning data leakage training set hypothesis space empirical risk minimization
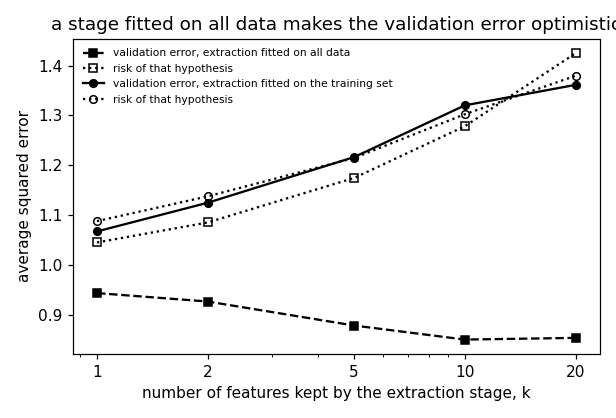
A machine learning pipeline (ML pipeline) is the composition of the functions by which a machine learning system (ML system) turns raw data into predictions. Its stages typically are data preprocessing, feature learning or hand-designed feature extraction, model training, and inference on new data points. Each stage is a function whose output is the input of the next, so the whole pipeline is one map from raw data to predictions and is applied identically during training and in deployment. Fitting stages such as feature scaling inside the pipeline, on the training set only, prevents data leakage from the validation set or test set.
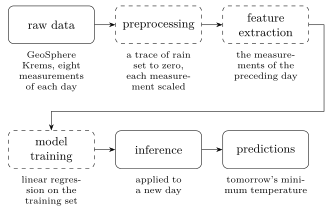
mlpipeline.py, which recomputes what the entry states: the script block by block · open in ColabThe weather station Krems an der Donau reports eight measurements of each day to the GeoSphere Austria data hub. Turning that stream into a forecast of tomorrow's minimum temperature takes four steps: cleaning the records, extracting features, training a model, and computing the prediction. The sequence of such steps is an ML pipeline: a composition (i.e., concatenation) of several functions within a machine learning system (ML system). The individual functions include data preprocessing, feature learning or hand-designed feature extraction, model training, and inference on new data points. By combining them, an ML system turns raw data into predictions (Hapke and Nelson, 2020) (Fig. 1).
Written as math, a pipeline of three stages is the concatenation \begin{equation} \label{equ_mlpipeline_dict} h = h^{(3)} \circ h^{(2)} \circ h^{(1)} \text{,} \end{equation} with $h^{(1)}$ the feature map, $h^{(2)}$ the hypothesis applied to the resulting features, and $h^{(3)}$ the post-processing of its output. Of the four steps above, cleaning and feature extraction form $h^{(1)}$, the trained hypothesis is $h^{(2)}$ (training is how it is chosen, not a factor of $h$), and the post-processing of the prediction is $h^{(3)}$. Each factor is chosen from a hypothesis space of its own, $h^{(j)} \in \mathcal{H}^{(j)}$ for $j = 1, 2, 3$. The concatenations \(\eqref{equ_mlpipeline_dict}\) are themselves a hypothesis space, \[ \mathcal{H} = \bigl\{ h^{(3)} \circ h^{(2)} \circ h^{(1)} \; : \; h^{(j)} \in \mathcal{H}^{(j)}, \; j = 1, 2, 3 \bigr\} \text{,} \] so training the pipeline is empirical risk minimization (ERM) over $\mathcal{H}$ rather than over any one stage.
B-compareEach stage is a function whose output is the input of the next,
so the pipeline is one map from raw data to predictions,
applied identically during training and in deployment. Stages
with their own parameters, such as feature scaling, are
fitted on the training set only. Fitting them on all available
data leaks information from the validation set or the
test set into the learned hypothesis, so that the
validation error or the error on the test set underestimates the risk (see
data leakage). Software libraries therefore bundle the stages
into one object that is trained as a whole on the training set
(Pedregosa et al., 2011). The pipeline is the computational part of
an ML system, which additionally comprises data storage,
deployment, and monitoring.
See also: function, machine learning system, preprocessing, feature learning, inference, data leakage, training set, hypothesis space, empirical risk minimization.
@misc{dictml_mlpipeline,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {machine learning pipeline (ML pipeline)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-03},
  url = {https://dictionaryofml.org/terms/mlpipeline.html}
}