
tabulardata.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-24
Readiness 100/100
See also data data point dataset feature label feature matrix data imputation feature learning
Tabular data consist of data points that share a common, fixed set of attributes. The measured attributes serve as the features or as the label of a data point. The data points constitute the rows, or records, of a table, and the attributes are its columns. Every row has one cell per column, and the cells within one column hold values of the same attribute. The fixed attribute set separates tabular data from other types of data, such as text or graphs, whose data points carry no common set of attributes.
tabulardata.py, which recomputes what the entry states: the script block by block · open in ColabTabular data consist of data points that share a common, fixed set of attributes (Everitt, 2002). As the name suggests, tabular data can be stored as a table: the rows of the table are the data points, and the columns of the table are the attributes.
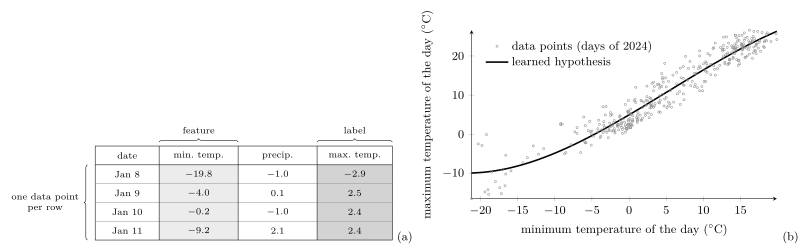
B-fetchThe weather measurements at a Finnish Meteorological Institute (FMI) weather station are
typically represented as a table
(Fig. 1(a)): one row for each day. The
table has four columns, one per attribute of a day: the date, the
morning minimum temperature, the precipitation, and the maximum
daytime temperature (Finnish Meteorological Institute, 2024). The date identifies the
data point, and the three measured attributes are the
candidates for its features and its label.
In Fig. 1(b), the learning task is to
forecast the maximum daytime temperature of a day from its morning
minimum temperature. A machine learning (ML) method reads the minimum-temperature
column as the feature and the maximum-temperature column as
the label, while the precipitation column is left unused. It
learns a hypothesis from the $366$ data points, shown
as a scatterplot with the learned curve.
pythondemos/tabulardata.py
In database theory, the relational model formalizes a table as a relation. A relation is a set of tuples of attribute values. The relational model also provides the operations, such as selecting rows or joining tables, that database systems use to manipulate tabular data (Silberschatz et al., 2019).
The fixed attribute set is what separates tabular data from other data types. For the weather measurements, the station records the same quantities every day, so the attribute set is fixed by the measurement process and shared by every data point. A text, in contrast, is a sequence of tokens whose length varies from data point to data point, and a graph varies in its node and edge sets. Such data points carry no attribute set of their own. One can be imposed, for example the number of occurrences of each word from a fixed word list, but such a set discards the order of the tokens. The table of weather measurements loses nothing in this way, since a day is fully described by its four attributes, while a text with its tokens in another order is a different text. Instead, feature learning methods are developed that map such data points to feature vectors (or embeddings) (Kipf and Welling, 2017; Mikolov et al., 2013).
See also: data, data point, dataset, feature, label, feature matrix, relational model, missing data, data imputation, gradient-boosted decision tree, feature learning.
@misc{dictml_tabulardata,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {tabular data},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/tabulardata.html}
}