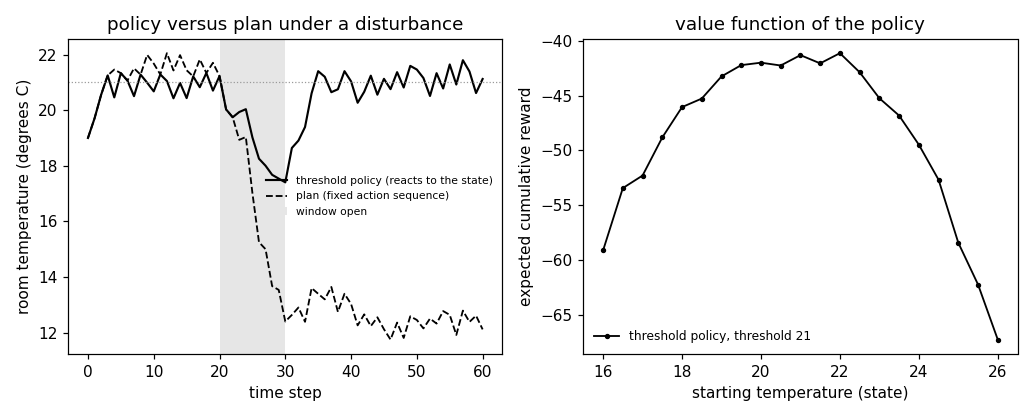
policy.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-28
Readiness 100/100
See also reinforcement learning reward
A policy in reinforcement learning (RL) is a function that maps the current state to an action. Sometimes a policy is stochastic and defined by a conditional probability distribution over the actions given the state. The policy of an RL method can be viewed as the hypothesis of a machine learning (ML) method. It takes the features that characterize the current state of the agent as input and outputs a prediction of the best action to take. Instead of an average loss on a training set, RL methods use the rewards observed after taking actions to guide the learning of a policy.
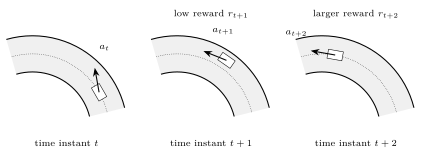
policy.py, which recomputes what the entry states: the script block by block · open in ColabIn reinforcement learning (RL), an agent interacts with an environment. At each time instant $t = 1, 2, \ldots$, the agent observes the state $s_{t}$ of the environment, takes an action $a_{t}$, and receives the next state $s_{t+1}$ together with a reward $r_{t+1}$. This interaction is modeled as a Markov decision process (MDP). Fig. 1 shows three time instants of a self-driving car: the state is the position and heading of the car, the action is the steering direction, and the reward tells how well the car follows the road.
B-stochIn its simplest form, a policy is a function that specifies
which action $a_{t}$ to take in this MDP when
the current state is $s_{t}$
(Sutton and Barto, 2018, Sect. 3.5). A policy differs from a plan, a
fixed sequence of actions: a policy reacts to the
state observed. A policy of this kind is deterministic. It
is a special case of a stochastic policy, which defines a
conditional probability distribution $\mathbb{P}^{(a \mid s)}$ over the
actions given the state, a probability distribution from which
the action is drawn.
B-valueThe return at time instant $t$ is the discounted sum of the rewards received afterwards, \[ G_{t} := \sum_{k=0}^{\infty} \gamma^{k} r_{t+k+1} \text{,} \] with a discount factor $\gamma \in [0,1]$ (Sutton and Barto, 2018, Sect. 3.3). The expected return, as a function of the starting state, is the value function of the policy (Sutton and Barto, 2018, Sect. 3.5). It can be estimated by executing the policy: the agent starts from the state several times, follows the policy for a number of time instants, records the rewards, and averages the observed returns (Sutton and Barto, 2018, Ch. 5).
See also: action, Markov decision process, state, reinforcement learning, reward, value function, return, policy gradient, agent.
@misc{dictml_policy,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {policy (reinforcement learning)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-03},
  url = {https://dictionaryofml.org/terms/policy.html}
}