reward.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 114 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-28
Readiness 100/100
See also loss reinforcement learning label
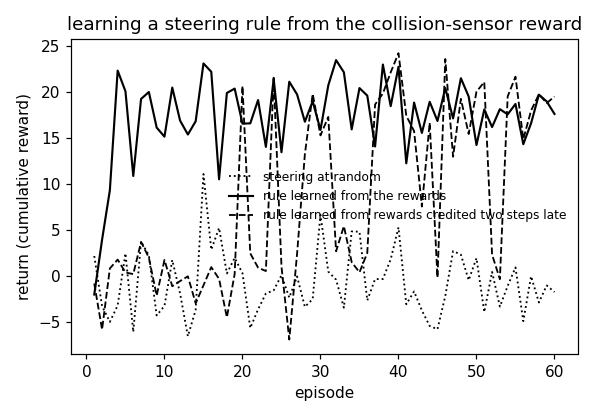
A reward is an observed quantity that allows a machine learning (ML) method to estimate the loss incurred by the prediction of a hypothesis. One example of such a quantity is the label of a data point itself. Many ML applications, however, do not allow the label to be observed, but only a noisy estimate of it; some allow only the prediction error of one specific prediction to be observed. Reinforcement learning (RL) methods learn a sequence of hypothesis maps from the rewards obtained by their predictions. For example, a self-driving vehicle predicts, at each time instant, a steering direction, and observes as a reward whether that direction keeps the vehicle on its lane, with a low reward for a direction that carries it off the road.
reward.py, which recomputes what the entry states: the script block by block · open in ColabB-partialThe ultimate goal of machine learning (ML) is to learn a
hypothesis that predicts the label of a data point
well from its features. Choosing among different
hypothesis maps requires a measure of the prediction
error that a hypothesis incurs. Such a measure is the
loss, which can be defined, for example, by comparing the
prediction $h({\mathbf x})$ with the actual
label value $y$. In some ML applications,
however, the label of a data point cannot be accessed at
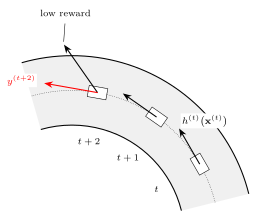
all. Consider a self-driving car, where a data point is the
current time instant and the label is the optimal steering
direction. That optimal direction is never observed; what is
observed is whether the steering direction predicted by the
hypothesis keeps the car on its lane
(Fig. 1).
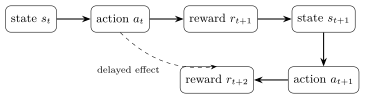
B-learnA reward replaces the label of supervised learning: it does
not reveal the correct prediction, only how good the chosen
prediction, the action, was, and it may arrive delayed, several time steps after
the action that caused it, or corrupted by noise
(Sutton and Barto, 2018, Sect. 1.1). Reinforcement learning (RL) methods
learn a sequence of hypothesis maps from the rewards
obtained by their predictions: the negative reward is the
loss of the action taken, and the actions chosen
are those that maximize the cumulative reward, the return
(Sutton and Barto, 2018, Sect. 3.2). In the self-driving car of
Fig. 1, the state $s_{t}$
is the position and orientation of the car on the road at time
instant $t$, and the action $a_{t}$ is the
steering direction predicted there.
Fig. 2 shows how states,
actions and rewards follow one another over two time steps.
See also: loss, multiarmed bandit, reinforcement learning, return, action, label.
@misc{dictml_reward,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {reward},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-11-03},
  url = {https://dictionaryofml.org/terms/reward.html}
}