fairness.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 109 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-28
Readiness 70/100
See also trustworthy artificial intelligence hypothesis empirical risk minimization explainable artificial intelligence
Fairness (machine learning) is the property of a learned hypothesis, or of the decision rule built on it, to treat data points with different values of a sensitive attribute, such as gender or age, in a comparable way. A counterfactual criterion requires the prediction to be unchanged if the sensitive attribute had taken another value. An individual criterion requires similar predictions for data points that are similar under a task-specific metric. Group criteria equate a measure across the groups: the approval rates (demographic parity), the true-positive and false-positive rates (equalized odds), or the probability of the label given the score (calibration). The criteria are incompatible in general: calibration and equalized odds cannot both hold when the groups differ in their share of positive labels. A chosen criterion is met by a design choice for a component of empirical risk minimization (ERM): excluding the sensitive attribute and the features correlated with it from the model, adding a penalty term or a constraint to the loss function, or resampling the training set.
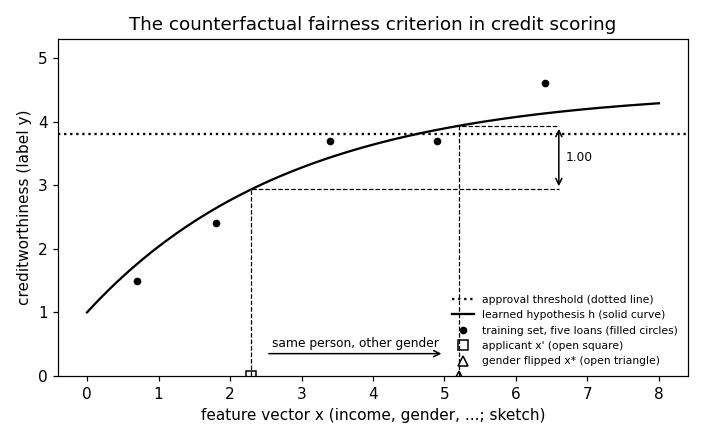
fairness.py, which recomputes what the entry states: the script block by block · open in ColabB-flipConsider a bank that approves a loan when the creditworthiness predicted by a learned hypothesis $\widehat{h}$ exceeds a threshold $\tau$. The feature vector ${\mathbf x}$ of an applicant collects the income, the gender, and further attributes, and $\widehat{h}$ was learned from the training set $\mathcal{D}^{(\rm train)}$ of completed loans. An applicant with feature vector ${\mathbf x}'$ obtains $\widehat{h}({\mathbf x}') = 2.94$, below $\tau = 3.8$, and is rejected. The same applicant with only the gender flipped, ${\mathbf x}^{\star}$, obtains $\widehat{h}({\mathbf x}^{\star}) = 3.93$ and is approved. Whether this system is fair has several precise answers, and they cannot all hold at once. Fairness in machine learning (ML) is the property of a learned hypothesis, or of the decision rule built on it, to treat data points with different values of a sensitive attribute $s$, such as gender, race, or age, in a comparable way, on top of making accurate predictions (Barocas et al., 2023). It is one of the key requirements for trustworthy artificial intelligence (trustworthy AI).
Three families of fairness criteria are distinguished (Barocas et al., 2023). A counterfactual criterion requires that the prediction for a data point would not change if its sensitive attribute had taken another value, under a causal model of how $s$ affects the other features (see causality) (Kusner et al., 2017). An individual criterion requires that data points that are similar under a task-specific metric, such as one that ignores $s$, receive similar predictions (Dwork et al., 2012). A group criterion requires equality of some measure across the groups defined by $s$. Demographic parity equates the approval rates, \begin{equation} \label{eq_fairness_dempar} \mathbb{P}\left(\widehat{h}({\mathbf x}) \geq \tau \mid s = 0\right) = \mathbb{P}\left(\widehat{h}({\mathbf x}) \geq \tau \mid s = 1\right) \text{,} \end{equation} where the data point is modeled as the realization of a random variable (RV). For a binary label $y \in \{0,1\}$, such as whether a loan was repaid, equalized odds equates the true-positive rate and the false-positive rate across the groups (Hardt et al., 2016), and calibration equates $\mathbb{P}\left(y = 1 \mid \widehat{h}({\mathbf x}) = c, s\right)$ across the groups for every score $c$ (Chouldechova, 2017).
B-individualFig. 1 shows the credit-scoring example. The
horizontal axis is a one-dimensional sketch of the
feature vector; the gender flip moves the applicant from
${\mathbf x}'$ (open square) to ${\mathbf x}^{\star}$ (open
triangle). The gap $\widehat{h}({\mathbf x}^{\star}) -
\widehat{h}({\mathbf x}') = 0.99$ (double arrow) is caused
by the gender alone, so $\widehat{h}$ fails the
counterfactual criterion. It fails the individual criterion under
a metric that ignores $s$ as well: ${\mathbf x}'$ and
${\mathbf x}^{\star}$ are then the same data point, yet they
receive predictions on opposite sides of $\tau$. The group
criteria cannot be checked from five loans. They compare the
predictions of $\widehat{h}$ over the population of
applicants, which the probability distribution of the demographic-parity condition \(\eqref{eq_fairness_dempar}\) describes.
B-modelOnce a criterion is chosen, it is met by a design choice for one of the components of empirical risk minimization (ERM) (Pfau and Jung, 2024, Sect. VIII). The model can exclude the sensitive attribute; ${\mathbf x}'$ and ${\mathbf x}^{\star}$ then coincide and the gap in Fig. 1 vanishes. Excluding $s$ alone does not suffice, since features correlated with it, such as the postal code, carry the same information. The loss function can carry a penalty term for the gap, or the gap can be a constraint of the constrained optimization problem that replaces ERM. The training set can be resampled so that the groups are represented equally (see imbalanced data). Each choice lowers the gap of the chosen criterion and raises the average loss on $\mathcal{D}^{(\rm train)}$ or the gap of another criterion (Kleinberg et al., 2017).
See also: sensitive attribute, trustworthy artificial intelligence, hypothesis, decision rule, prediction, calibration, metric, causality, counterfactual, empirical risk minimization, penalty term, constrained optimization problem, data governance, EU AI Act, general data protection regulation, high-risk artificial intelligence system, imbalanced data, explainable artificial intelligence.
@misc{dictml_fairness,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {fairness (machine learning)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-28},
  url = {https://dictionaryofml.org/terms/fairness.html}
}