
em.py, which recomputes what the entry states: the script block by block · open in ColabDictionary of Applied Machine Learning: 107 machine-learning terms, each with a definition, a figure, citations and a Python demo · All terms · Demos · Start here
Updated on 2026-10-22
Readiness 100/100
See also empirical risk minimization Gaussian mixture model $k$-means
The expectation–maximization (EM) algorithm is an iterative optimization method for a particular class of maximum likelihood problems. In particular, EM is useful for probabilistic models that involve observed and unobserved (or latent) attributes of a data point. Each iteration of the EM algorithm alternates an E-step with an M-step. The E-step computes the posterior distribution of the unobserved attributes under the current model parameters. The M-step minimizes the negative log-likelihood of the complete data points averaged under this posterior distribution, which for many probabilistic models has a closed form. Mathematically, the EM algorithm is an instance of a majorize–minimize (MM) method. A canonical soft clustering method uses the EM algorithm to learn the model parameters of a Gaussian mixture model (GMM).
em.py, which recomputes what the entry states: the script block by block · open in ColabB-fetchThe nightly
minimum temperatures recorded over one year at the weather
station of Krems an der Donau (Austria) scatter around two
regimes, cold-season and warm-season nights. A probabilistic model
for such data points has, besides the observed
temperature, an unobserved attribute: the regime a night
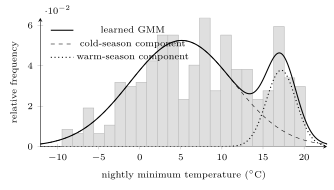
belongs to. Fig. 1 shows the
histogram of the temperatures together with a Gaussian mixture model (GMM)
consisting of a separate normal distribution for each regime. The
EM algorithm (Dempster et al., 1977) is
an iterative optimization method for approximately solving
maximum likelihood optimization problems for probabilistic models
with an unobserved attribute
(Bishop, 2006, Sect. 9.4;
Hastie et al., 2009, Sect. 8.5;
Murphy, 2012, Sect. 11.4.7).
pythondemos/em.py
The EM algorithm solves the maximum likelihood problem
\(\eqref{equ_em_emprisk_dict}\) by alternating two steps. The
E-step computes, for every data point, the
posterior distribution of the unobserved attribute under the
current model parameters $\widehat{\weights}$,
\begin{equation}
\label{equ_em_estep_dict}
\pmf{\truelabel'|\featurevec'}{\truelabel;\widehat{\weights}}
= \frac{\pmf{\featurevec',\truelabel'}{\featurevec^{(\sampleidx)},\truelabel;\widehat{\weights}}}
{\sum_{\truelabel'' \in \labelspace}
\pmf{\featurevec',\truelabel'}{\featurevec^{(\sampleidx)},\truelabel'';\widehat{\weights}}}
\quad \text{for } \truelabel \in \labelspace
\text{ and } \sampleidx = 1, \ldots, \samplesize\text{.}
\end{equation}
The M-step minimizes over $\weights \in \paramspace$ the
empirical risk of the complete data points, averaged under
these posterior distributions,
\begin{equation}
\label{equ_em_mstep_dict}
Q(\weights \mid \widehat{\weights}) \defeq
- \frac{1}{\samplesize} \sum_{\sampleidx=1}^{\samplesize}
\sum_{\truelabel \in \labelspace}
\pmf{\truelabel'|\featurevec'}{\truelabel;\widehat{\weights}}
\ln \frac{\pmf{\featurevec',\truelabel'}{\featurevec^{(\sampleidx)},\truelabel;\weights}}
{\pmf{\truelabel'|\featurevec'}{\truelabel;\widehat{\weights}}}\text{.}
\end{equation}
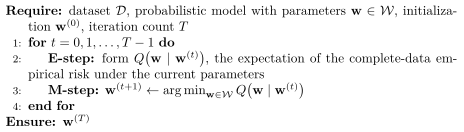
Algorithm 1 states the method in full.
The EM algorithm is a majorize–minimize (MM) method: each iteration minimizes a surrogate $Q(\weights \mid \widehat{\weights})$ of the empirical risk \(\eqref{equ_em_emprisk_dict}\). The surrogate \(\eqref{equ_em_mstep_dict}\) has three properties (Bishop, 2006, Sect. 9.4, whose lower bound on the log-likelihood is this surrogate written for the negative log-likelihood; Hunter and Lange, 2004, Sect. 2). First, it majorizes the empirical risk, $Q(\weights \mid \widehat{\weights}) \geq \emprisk{\weights}{\dataset}$ for all $\weights \in \paramspace$, by Jensen's inequality applied to the concave logarithm. Second, it is tight at the current iterate, $Q(\widehat{\weights} \mid \widehat{\weights}) = \emprisk{\widehat{\weights}}{\dataset}$. Third, it is minimized exactly by the M-step.
Any model parameters $\weights^{(\iteridx+1)}$ that minimize the surrogate built at $\weights^{(\iteridx)}$ therefore satisfy $\emprisk{\weights^{(\iteridx+1)}}{\dataset} \leq Q(\weights^{(\iteridx+1)} \mid \weights^{(\iteridx)}) \leq Q(\weights^{(\iteridx)} \mid \weights^{(\iteridx)}) = \emprisk{\weights^{(\iteridx)}}{\dataset}$: no iteration increases the empirical risk (Dempster et al., 1977, Thm. 1).
The monotone decrease of the empirical risk \(\eqref{equ_em_emprisk_dict}\) along the EM iterates yields a stopping criterion: the iteration stops as soon as the decrease of the empirical risk achieved by the last iteration falls below a given threshold (Bishop, 2006, Sect. 9.2.2). The empirical risk \(\eqref{equ_em_emprisk_dict}\) is in general a non-convex function of the model parameters, and EM might converge to a local minimum (Bishop, 2006, Sect. 9.2.2). It is therefore typically run several times with different initializations, keeping the run with the smallest empirical risk (Murphy, 2012, Sect. 11.3.2).
The EM algorithm is a fixed-point iteration $\widehat{\weights}^{(\iteridx+1)} = \fixedpointop\big(\widehat{\weights}^{(\iteridx)}\big)$. The operator $\fixedpointop$ maps the current model parameters $\widehat{\weights}$ to the result of one E-step followed by one M-step. The E-step \(\eqref{equ_em_estep_dict}\) at $\widehat{\weights}$ builds the surrogate $Q(\cdot \mid \widehat{\weights})$, and the M-step \(\eqref{equ_em_mstep_dict}\) minimizes it, \[\fixedpointop(\widehat{\weights}) \defeq \argmin_{\weights \in \paramspace} Q(\weights \mid \widehat{\weights})\text{.}\] The fixed points of $\fixedpointop$ are model parameters that minimize their own surrogate: there, the surrogate touches the empirical risk from above, so no further descent step is available, and the gradient of the empirical risk vanishes (Wu, 1983).
B-emEM is used to learn the model parameters of a GMM, where the unobserved attribute of a data point is its cluster index $I^{(\sampleidx)} \in \{1, \ldots, \nrcluster\}$ and the model parameters are the cluster probabilities $p_{\clusteridx}$, means $\meanvec{\clusteridx}$, and covariance matrices $\covmtx{\clusteridx}$ (Bishop, 2006, Sect. 9.2.2). The E-step \(\eqref{equ_em_estep_dict}\) becomes the degree of belonging \begin{equation} \label{equ_em_gmm_estep_dict} \dob{\clusteridx}{\sampleidx} \defeq \prob{I^{(\sampleidx)} = \clusteridx \mid \featurevec^{(\sampleidx)}} = \frac{p_{\clusteridx}\, \mvnormal{\meanvec{\clusteridx}}{\covmtx{\clusteridx}}(\featurevec^{(\sampleidx)})} {\sum_{\clusteridx'=1}^{\nrcluster} p_{\clusteridx'}\, \mvnormal{\meanvec{\clusteridx'}}{\covmtx{\clusteridx'}}(\featurevec^{(\sampleidx)})}\text{,} \end{equation} and minimizing the surrogate \(\eqref{equ_em_mstep_dict}\) yields the M-step in closed form. The cluster probability $p_{\clusteridx}$ is the average of $\dob{\clusteridx}{\sampleidx}$ over the data points, while $\meanvec{\clusteridx}$ and $\covmtx{\clusteridx}$ are the mean and covariance matrix of the feature vectors weighted by $\dob{\clusteridx}{\sampleidx}$. The learned degrees of belonging \(\eqref{equ_em_gmm_estep_dict}\) constitute a soft clustering. Fixing every cluster probability at $1/\nrcluster$ and every covariance matrix at $\sigma^{2} \mI$, a multiple of the identity matrix $\mI$ with a common $\sigma^{2}$ that shrinks towards $0$ turns the degrees of belonging into $0$ or $1$, and EM reduces to Lloyd's algorithm for $k$-means (Bishop, 2006, Sect. 9.3.2).
Consider next, as an illustration of the EM algorithm, the GMM of Fig. 1 for the temperature dataset. The feature of a data point is the nightly minimum temperature $\feature \in \reals$, and its unobserved attribute is the regime $\truelabel \in \{\mathrm{cold}, \mathrm{warm}\}$. The model parameters are the probabilities $p_{\mathrm{cold}}$, $p_{\mathrm{warm}} = 1 - p_{\mathrm{cold}}$ of the two regimes, the means $\mu_{\mathrm{cold}}$, $\mu_{\mathrm{warm}}$ and the variances $\sigma^{2}_{\mathrm{cold}}$, $\sigma^{2}_{\mathrm{warm}}$ of the two normal distributions, so $\weights = (p_{\mathrm{cold}}, p_{\mathrm{warm}}, \mu_{\mathrm{cold}}, \mu_{\mathrm{warm}}, \sigma^{2}_{\mathrm{cold}}, \sigma^{2}_{\mathrm{warm}})^{\top} \in \reals^{6}$. The E-step \(\eqref{equ_em_estep_dict}\) computes for every night the probability of the cold regime, and the M-step \(\eqref{equ_em_mstep_dict}\) re-fits $\weights$ as averages weighted by these probabilities. On the $366$ nights of 2024, EM learns $p_{\mathrm{cold}} = 0.83$, $\mu_{\mathrm{cold}} = 5.1$, $\mu_{\mathrm{warm}} = 17.2$, $\sigma^{2}_{\mathrm{cold}} = 39.7$, and $\sigma^{2}_{\mathrm{warm}} = 3.3$.
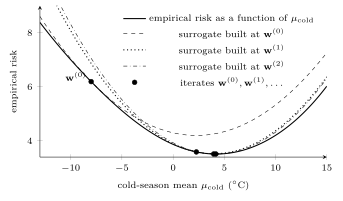
B-majorizeFig. 2 shows the MM view for
this GMM as the cold-season mean $\mu_{\mathrm{cold}}$
varies, while $p_{\mathrm{cold}}$, $\mu_{\mathrm{warm}}$ and
$\sigma^{2}_{\mathrm{warm}}$ are fixed at their learned values
and $\sigma^{2}_{\mathrm{cold}}$ is fixed at $16$. The
empirical risk is then a function of $\mu_{\mathrm{cold}}$
alone, and so is each surrogate. Each surrogate lies above the
empirical risk, touches it at its iterate, and its minimizer is
the next iterate. Fig. 3 shows how the
empirical risk decreases monotonically as the EM
iterations proceed.
pythondemos/em.py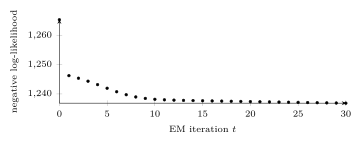
pythondemos/em.py
See also: maximum likelihood, probabilistic model, empirical risk minimization, majorize–minimize, fixed-point iteration, fixed point, posterior distribution, Gaussian mixture model, soft clustering, degree of belonging, $k$-means, Lloyd's algorithm, optimization problem.
@misc{dictml_em,
  author = {Jung, Alexander},
  editor = {Olioumtsevits, Konstantina and Schnoor, Ekkehard},
  title = {expectation–maximization (EM)},
  howpublished = {Dictionary of Applied Machine Learning (course edition)},
  year = {2026},
  doi = {10.5281/zenodo.21569296},
  note = {ISBN 978-952-64-3013-3, CC BY 4.0, retrieved 2026-10-27},
  url = {https://dictionaryofml.org/terms/em.html}
}