Dictionary of Applied Machine Learning · decision boundary
Updated on 2026-11-02
Numerical companion to the entry decision boundary: it recomputes what the entry states and prints one line per check
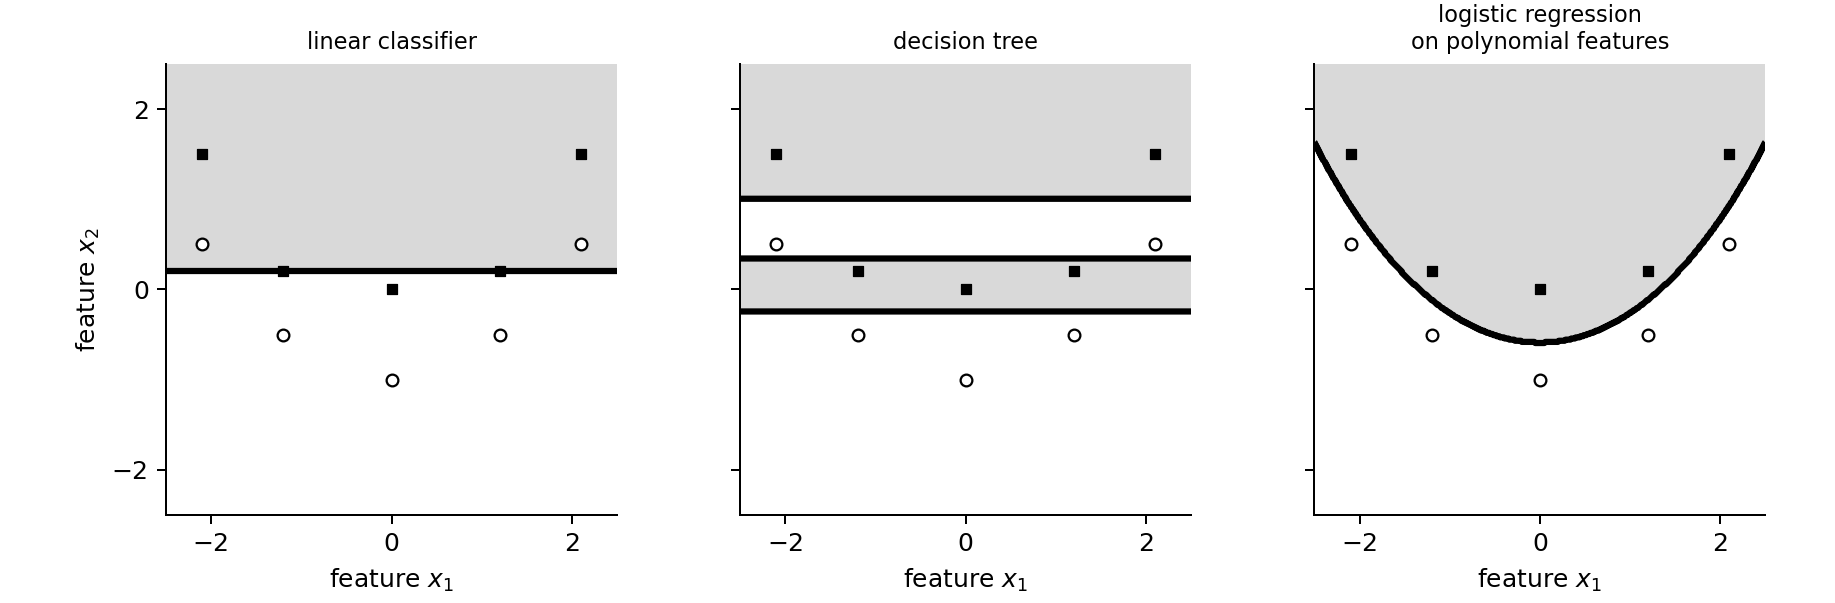
The same two-dimensional training set of ten datapoints is used to learn three classifiers: logistic regression on the original features, a depth-4 decision tree, and logistic regression on polynomial features of degree two. Their learned decision regions and boundaries are shown in decisionboundary.png.
Run it without installing anything:uv run https://dictionaryofml.org/terms/decisionboundary.py
uv downloads this script and the pinned NumPy and Matplotlib it needs, then runs it; the script fetches any input file it uses. To keep the output files, download decisionboundary.py into a folder and run uv run decisionboundary.py there. With NumPy and Matplotlib already installed, python3 decisionboundary.py, from any directory — it writes its output files into the current directory. Fixed seeds, so the printed numbers reproduce exactly. Download decisionboundary.py · Notebook · Open in Colab
"""Numerical companion to the glossary entry 'decision boundary'.

The same two-dimensional training set of ten datapoints is used to learn three classifiers:
logistic regression on the original features, a depth-4 decision tree, and
logistic regression on polynomial features of degree two.  Their learned
decision regions and boundaries are shown in decisionboundary.png.

The implementation uses only NumPy and Matplotlib and a fixed random seed.
"""

from pathlib import Path

import matplotlib
import numpy as np

matplotlib.use("Agg")
import matplotlib.pyplot as plt

OUT_DIR = Path(__file__).parent


def check(name, condition):
    print(f"  [{'ok' if condition else 'FAIL'}] {name}")
    if not condition:
        raise RuntimeError(name)


# Ten training datapoints whose classes are separated by a quadratic curve.
X = np.array([
    [-2.1, 1.5], [-1.2, 0.2], [0.0, 0.0], [1.2, 0.2], [2.1, 1.5],
    [-2.1, 0.5], [-1.2, -0.5], [0.0, -1.0], [1.2, -0.5], [2.1, 0.5],
])
threshold = 0.42 * X[:, 0] ** 2 - 0.65
y = np.where(X[:, 1] > threshold, 1, -1)
check("the training set contains at most ten datapoints", len(X) <= 10)


def feature_map(x, degree):
    """Original features, or all monomials up to degree two."""
    if degree == 1:
        return np.column_stack((np.ones(len(x)), x[:, 0], x[:, 1]))
    return np.column_stack((np.ones(len(x)), x[:, 0], x[:, 1],
                            x[:, 0] ** 2, x[:, 0] * x[:, 1],
                            x[:, 1] ** 2))


def train_logistic(x, labels, degree):
    phi = feature_map(x, degree)
    weights = np.zeros(phi.shape[1])
    binary_labels = (labels + 1) / 2
    for _ in range(5000):
        scores = np.clip(phi @ weights, -30, 30)
        probs = 1 / (1 + np.exp(-scores))
        weights -= 0.3 * phi.T @ (probs - binary_labels) / len(labels)
    return weights


def logistic_predict(x, weights, degree):
    return np.where(feature_map(x, degree) @ weights >= 0, 1, -1)


def grow_tree(x, labels, depth=0, max_depth=4, min_leaf=1):
    """Grow a small CART classification tree using Gini impurity."""
    node = {"prediction": 1 if np.mean(labels == 1) >= 0.5 else -1}
    if depth == max_depth or np.all(labels == labels[0]):
        return node
    best = None
    for feature in range(x.shape[1]):
        values = np.unique(x[:, feature])
        for cut in (values[:-1] + values[1:]) / 2:
            left = x[:, feature] <= cut
            if left.sum() < min_leaf or (~left).sum() < min_leaf:
                continue
            impurity = 0.0
            for part in (left, ~left):
                p = np.mean(labels[part] == 1)
                impurity += part.mean() * 2 * p * (1 - p)
            if best is None or impurity < best[0]:
                best = (impurity, feature, cut, left)
    if best is None:
        return node
    _, feature, cut, left = best
    node.update(feature=feature, cut=cut,
                left=grow_tree(x[left], labels[left], depth + 1,
                               max_depth, min_leaf),
                right=grow_tree(x[~left], labels[~left], depth + 1,
                                max_depth, min_leaf))
    return node


def tree_predict(x, tree):
    predictions = np.empty(len(x), dtype=int)
    for i, row in enumerate(x):
        node = tree
        while "feature" in node:
            node = node["left"] if row[node["feature"]] <= node["cut"] \
                else node["right"]
        predictions[i] = node["prediction"]
    return predictions


w_linear = train_logistic(X, y, degree=1)
w_poly = train_logistic(X, y, degree=2)
tree = grow_tree(X, y)

models = [
    ("linear classifier", lambda z: logistic_predict(z, w_linear, 1)),
    ("decision tree", lambda z: tree_predict(z, tree)),
    ("logistic regression\non polynomial features",
     lambda z: logistic_predict(z, w_poly, 2)),
]

grid_axis = np.linspace(-2.5, 2.5, 401)
g1, g2 = np.meshgrid(grid_axis, grid_axis)
grid = np.column_stack((g1.ravel(), g2.ravel()))

errors = [np.mean(predict(X) != y) for _, predict in models]
check("all three classifiers produce both decision regions",
      all(len(np.unique(predict(grid))) == 2 for _, predict in models))
check("polynomial features capture the quadratic boundary",
      errors[2] < errors[0])

fig, axes = plt.subplots(1, 3, figsize=(10.2, 3.35), sharex=True, sharey=True)
for ax, ((title, predict), error) in zip(axes, zip(models, errors)):
    region = predict(grid).reshape(g1.shape)
    ax.contourf(g1, g2, region, levels=[0, 1.5], colors=["0.85"])
    ax.contour(g1, g2, region, levels=[0], colors="black", linewidths=2.5)
    ax.scatter(X[y == -1, 0], X[y == -1, 1], s=22, marker="o",
               facecolors="white", edgecolors="black", linewidths=0.9)
    ax.scatter(X[y == 1, 0], X[y == 1, 1], s=15, marker="s",
               facecolors="black", edgecolors="black", linewidths=0.5)
    ax.set_title(title, fontsize=9)
    ax.set_xlabel(r"feature $x_1$")
    ax.set_aspect("equal")
    ax.set_xticks([-2, 0, 2])
    ax.set_yticks([-2, 0, 2])
    ax.spines["top"].set_visible(False)
    ax.spines["right"].set_visible(False)
axes[0].set_ylabel(r"feature $x_2$")
fig.tight_layout()
fig.savefig(OUT_DIR / "decisionboundary.png", dpi=180)
print(f"  wrote {OUT_DIR / 'decisionboundary.png'}")