B-sweep writes when the script runsDictionary of Applied Machine Learning · hyperparameter
Updated on 2026-11-03
Numerical companion to the entry hyperparameter: it recomputes what the entry states and prints one line per check
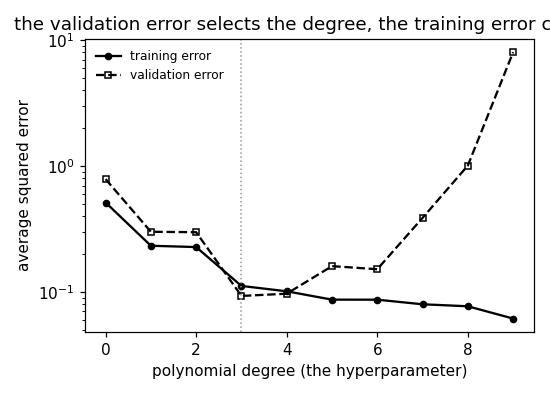
Shows why a hyperparameter is chosen by the validation error and not by the training error: for a polynomial model, the training error falls with every increase of the degree, while the validation error falls and then rises again, so only the validation error selects a degree. Self-contained (numpy/matplotlib only), fixed seed.
Run it without installing anything:uv run https://dictionaryofml.org/terms/hyperparameter.py
uv downloads this script and the pinned NumPy and Matplotlib it needs, then runs it; the script fetches any input file it uses. To keep the output files, download hyperparameter.py into a folder and run uv run hyperparameter.py there. With NumPy and Matplotlib already installed, python3 hyperparameter.py, from any directory — it writes its output files into the current directory. Fixed seeds, so the printed numbers reproduce exactly. Download hyperparameter.py · Notebook · Open in Colab
Before running a downloaded copy, scan it: uvx bandit -q -t B102,B307,B602,B605 hyperparameter.py (B102,B307,B602,B605 are the exec, eval and shell checks of bandit) reports nothing: the script runs no shell command and evaluates no generated code.
One cell per block of the script: the code, and what that code printed when it last ran here
"""
hyperparameter.py — numerical companion to the glossary entry
'hyperparameter'.

Purpose
-------
Shows why a hyperparameter is chosen by the validation error and not by
the training error: for a polynomial model, the training error falls
with every increase of the degree, while the validation error falls and
then rises again, so only the validation error selects a degree.
Self-contained (numpy/matplotlib only), fixed seed.

Setup
-----
Training set: m = 20 data points with feature x drawn uniformly from
[0, 1] and label y = sin(2 pi x) + Gaussian noise scaled by 0.3;
validation set: 100 further points from the same source.  Model: a
polynomial of degree p in x, with the degree as the hyperparameter;
the model parameters are the coefficients, learned by polynomial regression
(ERM with the squared error) on the training set.  Degrees 0 to
9 are compared by their average squared error on the training set
(training error) and on the validation set (validation error).

Blocks
------
[B-krems]  Twelve days of 2020 at Krems an der Donau and three candidate
           straight lines, for the entry's opening picture of a model and
           the loss of one data point.
[B-reach]  On one training set, gradient descent from the zero
           initialization w^(0) = 0, stopped after a FIXED five steps, at
           three learning rates: the reached weight vector moves outward
           with the rate, measured the way the training error's level
           sets measure distance, and the ellipse through the iterate
           farthest out, shaped like those level sets -- the effective
           hypothesis space -- contains every gradient step of that rate
           and of every smaller rate.  A hyperparameter of the optimization
           method therefore indexes a nested family of models, as the
           maximum degree does.
[B-data]   The training set and the validation set.
[B-sweep]  Training and validation error for each degree: the training
           error never increases with the degree, the validation error
           has an interior minimum, and the degree that minimizes it
           (3) is not the degree that minimizes the training error (9).

Outputs
-------
hyperparameter_krems.csv  : tmin, tmax and which point is annotated.
hyperparameter_lines.csv  : the three candidate lines on a grid of tmin.
hyperparameter_lossarrow.csv : the two ends of the loss arrow.
hyperparameter_circles.csv : the nested circles, one per learning rate.
hyperparameter_reach.csv  : learning rate, radius of the reachable set,
                            mean norm, and one problem's endpoint.
hyperparameter_errors.csv : degree, trainerr, valerr.
hyperparameter.png        : matplotlib preview of the entry's figure
                            (checking only).
"""

# /// script
# requires-python = ">=3.10"
# dependencies = ["matplotlib==3.10.7", "numpy==2.3.4"]
# ///

import json
import urllib.request

import numpy as np
import matplotlib

matplotlib.use("Agg")
import matplotlib.pyplot as plt

from pathlib import Path

OUT_DIR = Path(__file__).parent

report = []


def check(name, ok):
    report.append((name, bool(ok)))
    print(f"  [{'ok' if ok else 'FAIL'}] {name}")


rng = np.random.default_rng(1)
Twelve days of 2020 at Krems an der Donau and three candidate straight lines, for the entry's opening picture of a model and the loss of one data point.
# The basic ML picture for the entry's opening figure: a handful of days at
# Krems an der Donau, the minimum temperature of a day as feature and the
# maximum temperature as label, together with three candidate straight lines.
# The three lines are the model -- the set of maps the method may return --
# and one of them is singled out to show the loss of a single data point.
KURL = ("https://dataset.api.hub.geosphere.at/v1/station/historical/"
        "klima-v2-1d?parameters=tlmin,tlmax&station_ids=3805"
        "&start=2020-01-01&end=2020-12-31")
with urllib.request.urlopen(KURL, timeout=120) as resp:
    kpayload = json.load(resp)
kpar = kpayload["features"][0]["properties"]["parameters"]
ktmin = np.array(kpar["tlmin"]["data"], dtype=float)
ktmax = np.array(kpar["tlmax"]["data"], dtype=float)
check("[B-krems]  366 days of 2020 downloaded, none missing",
      len(ktmin) == 366 and not np.isnan(ktmin).any() and not np.isnan(ktmax).any())

krng = np.random.default_rng(4)
kdays = np.sort(krng.choice(366, size=12, replace=False))
kx, ky = ktmin[kdays], ktmax[kdays]
kslope, kintc = np.polyfit(kx, ky, 1)
# three members of the model: the least-squares line and two others
KLINES = [(kslope, kintc), (kslope * 0.55, kintc + 4.0), (kslope * 1.45, kintc - 4.5)]
# the data point whose loss the figure annotates: the largest residual
kresid = ky - (kslope * kx + kintc)
kpick = int(np.argmax(np.abs(kresid)))
check(f"[B-krems]  the annotated data point misses the fitted line by "
      f"{abs(kresid[kpick]):.1f} degrees, the largest of the twelve",
      abs(kresid[kpick]) == np.abs(kresid).max())
print(f"    12 days: feature {kx.min():.1f} to {kx.max():.1f}, "
      f"label {ky.min():.1f} to {ky.max():.1f} deg C; fitted line "
      f"y = {kslope:.2f} x + {kintc:.1f}")
with open(OUT_DIR / "hyperparameter_krems.csv", "w") as fh:
    fh.write("tmin,tmax,annotated\n")
    for i, (a, b) in enumerate(zip(kx, ky)):
        fh.write(f"{a:g},{b:g},{1 if i == kpick else 0}\n")
kg = np.linspace(-9.0, 19.0, 57)
with open(OUT_DIR / "hyperparameter_lines.csv", "w") as fh:
    fh.write("tmin,line1,line2,line3\n")
    for g in kg:
        fh.write(f"{g:g}," + ",".join(f"{sl * g + ic:.3f}" for sl, ic in KLINES) + "\n")
# the loss arrow: from the fitted line down to the annotated data point
with open(OUT_DIR / "hyperparameter_lossarrow.csv", "w") as fh:
    fh.write("tmin,tmax\n")
    fh.write(f"{kx[kpick]:g},{kslope * kx[kpick] + kintc:.3f}\n")
    fh.write(f"{kx[kpick]:g},{ky[kpick]:g}\n")
  [ok] [B-krems]  366 days of 2020 downloaded, none missing
  [ok] [B-krems]  the annotated data point misses the fitted line by 7.4 degrees, the largest of the twelve
    12 days: feature -6.3 to 16.3, label 0.8 to 31.9 deg C; fitted line y = 1.53 x + 5.9
On one training set, gradient descent from the zero initialization w^(0) = 0, stopped after a FIXED five steps, at three learning rates: the reached weight vector moves outward with the rate, measured the way the training error's level sets measure distance, and the ellipse through the iterate farthest out, shaped like those level sets -- the effective hypothesis space -- contains every gradient step of that rate and of every smaller rate. A hyperparameter of the optimization method therefore indexes a nested family of models, as the maximum degree does.
# A hyperparameter of the optimization method does the same job as one that
# chooses a model.  On ONE training set, gradient descent started at the
# zero initialization and stopped after a fixed number of steps reaches a
# weight vector whose distance from the origin, measured the way the
# training error's level sets measure it, grows with the learning rate.  The
# ellipse through the iterate farthest out (the largest rate overshoots, so
# its farthest iterate is the first step), shaped like those level sets, is
# the effective hypothesis space the rate allows: it contains every gradient
# step of that rate.  The ellipses of three rates are nested, and each
# contains every iterate of every smaller rate.
T_STEPS = 5
rrng = np.random.default_rng(7)
Xd = rrng.standard_normal((30, 2))
yd = Xd @ np.array([2.0, -1.0]) + 0.3 * rrng.standard_normal(30)
H = Xd.T @ Xd / len(yd)                      # curvature matrix of the training error
gvec = Xd.T @ yd / len(yd)
L = float(np.linalg.eigvalsh(H).max())        # largest curvature
etas = np.array([0.1, 0.4, 1.4])              # learning rates, as multiples of 1/L


def gd_path(eta_over_L, steps):
    """The iterates of `steps` gradient steps from w^(0) = 0."""
    w = np.zeros(2); path = [w.copy()]
    for _ in range(steps):
        w = w - (eta_over_L / L) * (H @ w - gvec)
        path.append(w.copy())
    return np.array(path)


paths = [gd_path(e, T_STEPS) for e in etas]
ends = np.array([pth[-1] for pth in paths])
path_hnorm2 = [np.array([w @ H @ w for w in pth]) for pth in paths]
hnorm2 = np.array([v.max() for v in path_hnorm2])   # squared H-norm of the farthest iterate
far_step = [int(v.argmax()) for v in path_hnorm2]
check("[B-reach]  from w^(0) = 0 and within 5 fixed steps, the farthest iterate "
      "moves outward with the learning rate: H-norms "
      + ", ".join(f"{np.sqrt(v):.2f} (step {t})" for v, t in zip(hnorm2, far_step)),
      bool(np.all(np.diff(hnorm2) > 0)))
inside = all(path_hnorm2[a].max() <= hnorm2[b] + 1e-12
             for b in range(3) for a in range(b + 1))
check("[B-reach]  each ellipse contains every gradient step of its own learning "
      "rate and of every smaller one, so the three effective hypothesis spaces "
      "are nested", inside)
wls = np.linalg.solve(H, gvec)
print(f"    least-squares solution ({wls[0]:.2f}, {wls[1]:.2f}); endpoints "
      + ", ".join(f"({w[0]:.2f}, {w[1]:.2f})" for w in ends))

# the H-ellipse through each endpoint:  { w : w^T H w = c }
evals, evecs = np.linalg.eigh(H)
ang = np.linspace(0.0, 2.0 * np.pi, 121)
unit = np.stack([np.cos(ang), np.sin(ang)])              # 2 x 121
ellipses = [np.sqrt(c) * (evecs @ (unit / np.sqrt(evals)[:, None])) for c in hnorm2]
with open(OUT_DIR / "hyperparameter_ellipses.csv", "w") as fh:
    fh.write("angle," + ",".join(f"x{k+1},y{k+1}" for k in range(3)) + "\n")
    for t in range(len(ang)):
        fh.write(f"{ang[t]:.4f}," + ",".join(f"{E[0, t]:.4f},{E[1, t]:.4f}" for E in ellipses) + "\n")
with open(OUT_DIR / "hyperparameter_gdpath.csv", "w") as fh:
    fh.write("step," + ",".join(f"w1_{k+1},w2_{k+1}" for k in range(3)) + "\n")
    for t in range(T_STEPS + 1):
        fh.write(f"{t}," + ",".join(f"{pth[t, 0]:.4f},{pth[t, 1]:.4f}" for pth in paths) + "\n")
with open(OUT_DIR / "hyperparameter_reach.csv", "w") as fh:
    fh.write("eta_over_L,hnorm_farthest,farthest_step,w1_end,w2_end\n")
    for e, v, t, w in zip(etas, hnorm2, far_step, ends):
        fh.write(f"{e:g},{np.sqrt(v):.4f},{t},{w[0]:.4f},{w[1]:.4f}\n")
  [ok] [B-reach]  from w^(0) = 0 and within 5 fixed steps, the farthest iterate moves outward with the learning rate: H-norms 0.84 (step 5), 1.93 (step 5), 2.84 (step 1)
  [ok] [B-reach]  each ellipse contains every gradient step of its own learning rate and of every smaller one, so the three effective hypothesis spaces are nested
    least-squares solution (2.04, -1.00); endpoints (0.82, -0.27), (1.87, -0.76), (2.06, -0.99)
The training set and the validation set.
m, m_val, sigma = 20, 100, 0.3
x_tr = np.sort(rng.uniform(0.0, 1.0, m))
y_tr = np.sin(2 * np.pi * x_tr) + sigma * rng.standard_normal(m)
x_va = np.sort(rng.uniform(0.0, 1.0, m_val))
y_va = np.sin(2 * np.pi * x_va) + sigma * rng.standard_normal(m_val)
check(f"[B-data]  training set of {m} and validation set of {m_val} points",
      len(x_tr) == m and len(x_va) == m_val)
  [ok] [B-data]  training set of 20 and validation set of 100 points
  degree -> training error / validation error: 0: 0.513/0.787, 1: 0.233/0.301, 2: 0.227/0.298, 3: 0.112/0.093, 4: 0.101/0.097, 5: 0.087/0.160, 6: 0.087/0.152, 7: 0.080/0.387, 8: 0.077/1.009, 9: 0.061/8.031
Training and validation error for each degree: the training error never increases with the degree, the validation error has an interior minimum, and the degree that minimizes it (3) is not the degree that minimizes the training error (9).
degrees = np.arange(0, 10)
tr_err, va_err = [], []
for p in degrees:
    A = np.vander(x_tr, p + 1)                     # polynomial regression on the trainset
    w = np.linalg.lstsq(A, y_tr, rcond=None)[0]
    tr_err.append(float(np.mean((y_tr - A @ w) ** 2)))
    va_err.append(float(np.mean((y_va - np.vander(x_va, p + 1) @ w) ** 2)))
tr_err, va_err = np.array(tr_err), np.array(va_err)
p_tr, p_va = int(degrees[np.argmin(tr_err)]), int(degrees[np.argmin(va_err)])
print("  degree -> training error / validation error: " +
      ", ".join(f"{p}: {a:.3f}/{b:.3f}" for p, a, b in zip(degrees, tr_err, va_err)))
check("[B-sweep] the training error never increases with the degree",
      np.all(np.diff(tr_err) <= 1e-12))
check(f"[B-sweep] the validation error has an interior minimum at degree "
      f"{p_va}", 0 < p_va < degrees[-1])
check(f"[B-sweep] the training error would pick degree {p_tr}, the "
      f"validation error degree {p_va}", p_tr == 9 and p_va == 3)

# ---------------------------------------------------------------- CSV
with open(OUT_DIR / "hyperparameter_errors.csv", "w") as fh:
    fh.write("degree,trainerr,valerr\n")
    for p, a, b in zip(degrees, tr_err, va_err):
        fh.write(f"{p},{a:.4f},{b:.4f}\n")

# -------------------------------------------------------------- preview
fig, (axk, axr, ax) = plt.subplots(1, 3, figsize=(13.5, 3.8))
for (sl, ic), style, name in zip(KLINES, ["-", "--", ":"],
                                 ["the hypothesis h", "a second member of the model",
                                  "a third member"]):
    axk.plot(kg, sl * kg + ic, style, color="k", lw=1.2, label=name)
axk.plot(kx, ky, "ko", ms=4, label="the twelve days")
axk.annotate("", xy=(kx[kpick], ky[kpick]), xytext=(kx[kpick], kslope * kx[kpick] + kintc),
             arrowprops=dict(arrowstyle="<->", lw=1.4))
axk.text(kx[kpick] + 0.5, 0.5 * (ky[kpick] + kslope * kx[kpick] + kintc), "L((x, y), h)",
         fontsize=8)
axk.set_xlabel("minimum temperature x (deg C)")
axk.set_ylabel("maximum temperature y (deg C)")
axk.set_title("a model (three lines) and one loss")
axk.legend(frameon=False, fontsize=7, loc="upper left")
for k, (e, E, pth) in enumerate(zip(etas, ellipses, paths)):
    sty = ["--", "-.", "-"][k]
    axr.plot(E[0], E[1], sty, color=str(0.6 - 0.25 * k), lw=1.2,
             label=f"H for lrate {k + 1} = {e:g}/L")
    axr.plot(pth[:, 0], pth[:, 1], sty, color=str(0.6 - 0.25 * k), lw=0.8, marker=".", ms=4)
axr.plot(0, 0, "kx", ms=7)
axr.plot(wls[0], wls[1], "k+", ms=8)
axr.set_aspect("equal")
axr.set_xlabel("w1"); axr.set_ylabel("w2")
axr.set_title("GD from w(0) = 0, five steps, three rates")
axr.legend(frameon=False, fontsize=6, loc="upper center", bbox_to_anchor=(0.5, -0.17), ncol=3)
ax.plot(degrees, tr_err, "k-", marker="o", ms=4, label="training error")
ax.plot(degrees, va_err, "k--", marker="s", ms=4, mfc="none",
        label="validation error")
ax.axvline(p_va, color="0.6", ls=":", lw=1)
ax.set_yscale("log")
ax.set_xlabel("polynomial degree (the hyperparameter)")
ax.set_ylabel("average squared error")
ax.set_title("the validation error selects the degree")
ax.legend(frameon=False, fontsize=8)
fig.tight_layout()
fig.savefig(OUT_DIR / "hyperparameter.png", dpi=110)

n_ok = sum(ok for _, ok in report)
print(f"\n{n_ok}/{len(report)} checks pass")
print(f"wrote {OUT_DIR / 'hyperparameter_krems.csv'}, {OUT_DIR / 'hyperparameter_lines.csv'}, "
      f"{OUT_DIR / 'hyperparameter_lossarrow.csv'}, {OUT_DIR / 'hyperparameter_reach.csv'}, "
      f"{OUT_DIR / 'hyperparameter_ellipses.csv'}, {OUT_DIR / 'hyperparameter_gdpath.csv'}, "
      f"{OUT_DIR / 'hyperparameter_errors.csv'}, "
      f"{OUT_DIR / 'hyperparameter.png'}")
if n_ok != len(report):
    raise SystemExit(1)
  [ok] [B-sweep] the training error never increases with the degree
  [ok] [B-sweep] the validation error has an interior minimum at degree 3
  [ok] [B-sweep] the training error would pick degree 9, the validation error degree 3

8/8 checks pass
wrote /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_krems.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_lines.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_lossarrow.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_reach.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_ellipses.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_gdpath.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter_errors.csv, /Users/junga1/dictionaryappliedml/pythondemos/hyperparameter.png
B-sweep writes when the script runs