B-plot writes when the script runsDictionary of Applied Machine Learning · cluster centroid
Updated on 2026-11-19
Numerical companion to the entry cluster centroid: it recomputes what the entry states and prints one line per check
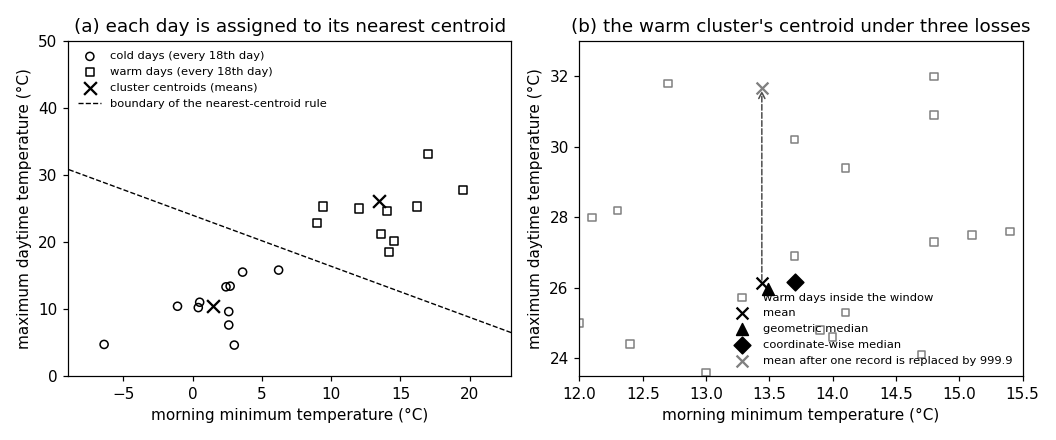
Numerical companion to the glossary entry 'clustercentroid'. The 366 days of 2024 at Krems are data points with the feature vector (morning minimum temperature, maximum daytime temperature). k-means with k = 2 splits them into cold days and warm days, and each cluster is represented by a single vector, its cluster centroid. The demo checks the entry's claims: the centroid is the vector that minimizes the summed loss over the data points of its cluster (the mean under the squared Euclidean distance, the geometric median under the Euclidean distance, the coordinate-wise median under the sum of absolute differences); the nearest-centroid assignment is a linear rule whose boundary is the perpendicular bisector of the two centroids; at the fixed point of Lloyd's algorithm each centroid is the mean of the days nearest to it; one corrupted record moves the mean by its displacement divided by the cluster size and moves either median far less; and the centroid of a soft clustering by a Gaussian mixture model is the mean weighted by the degrees of belonging.
Run it without installing anything:uv run https://dictionaryofml.org/terms/clustercentroid.py
uv downloads this script and the pinned NumPy and Matplotlib it needs, then runs it; the script fetches any input file it uses. To keep the output files, download clustercentroid.py into a folder and run uv run clustercentroid.py there. With NumPy and Matplotlib already installed, python3 clustercentroid.py, from any directory — it writes its output files into the current directory. Fixed seeds, so the printed numbers reproduce exactly. Download clustercentroid.py · Notebook · Open in Colab
Before running a downloaded copy, scan it: uvx bandit -q -t B102,B307,B602,B605 clustercentroid.py (B102,B307,B602,B605 are the exec, eval and shell checks of bandit) reports nothing: the script runs no shell command and evaluates no generated code.
One cell per block of the script: the code, and what that code printed when it last ran here
"""The cluster centroid of the cold and of the warm days at Krems an der
Donau: one vector that stands in for a cluster, under three losses.

Purpose
-------
Numerical companion to the glossary entry 'clustercentroid'.  The 366
days of 2024 at Krems are data points with the feature vector (morning
minimum temperature, maximum daytime temperature).  k-means with k = 2
splits them into cold days and warm days, and each cluster is
represented by a single vector, its cluster centroid.  The demo checks
the entry's claims: the centroid is the vector that minimizes the summed
loss over the data points of its cluster (the mean under the squared
Euclidean distance, the geometric median under the Euclidean distance,
the coordinate-wise median under the sum of absolute differences); the
nearest-centroid assignment is a linear rule whose boundary is the
perpendicular bisector of the two centroids; at the fixed point of
Lloyd's algorithm each centroid is the mean of the days nearest to it;
one corrupted record moves the mean by its displacement divided by the
cluster size and moves either median far less; and the centroid of a
soft clustering by a Gaussian mixture model is the mean weighted by the
degrees of belonging.

Deterministic: Lloyd's algorithm starts from the means of the colder
and of the warmer half of the days, Weiszfeld's iteration from the
mean, and EM from the k-means centroids.  Self-contained: numpy +
matplotlib only; the GeoSphere download falls back to the committed CSV.

Blocks
------
[B-data]      Download the daily minimum and maximum temperature of 2024
              at Krems (GeoSphere station 3805) or read the committed
              copy; 366 days, no missing value.
[B-lloyd]     Lloyd's algorithm with k = 2 from the colder and the
              warmer half of the days: cold days and warm days; at the
              fixed point each centroid is the mean of the days nearest
              to it, and the mean is the minimizer of the summed squared
              Euclidean distance over its cluster.
[B-assign]    The nearest-centroid assignment equals the sign of a
              linear function of the feature vector; the boundary is
              the perpendicular bisector of the two centroids, and a
              new day is assigned by the same rule.
[B-losses]    The warm cluster under three losses: mean, geometric
              median (Weiszfeld's fixed-point iteration), coordinate-
              wise median; each minimizes its own summed loss, and the
              geometric median satisfies the zero-sum condition on the
              unit vectors.
[B-outlier]   One warm day's maximum replaced by the sentinel 999.9:
              the mean moves by the displacement over the cluster size,
              the two medians far less.
[B-gmm]       EM for a Gaussian mixture model with k = 2 from the
              k-means centroids: at the fixed point each mean is the
              degree-of-belonging-weighted mean of all days; with
              degrees of belonging in {0, 1} the weighted mean is the
              plain mean.
[B-plot]      Every 18th day for panel (a), the warm days inside the
              window of panel (b), the centroids, the boundary line,
              and the preview figure.

Outputs
-------
clustercentroid_weather.csv       : date, tmin, tmax (committed copy).
clustercentroid_points_plot.csv   : the 21 drawn days with their cluster.
clustercentroid_kmeans.csv        : the two k-means centroids.
clustercentroid_boundary.csv      : two points of the boundary line.
clustercentroid_warm_plot.csv     : the warm days inside the window
                                    of panel (b).
clustercentroid_centroids.csv     : the warm cluster's centroid under
                                    each loss, before and after the
                                    corrupted record (kind, corrupted).
clustercentroid_shift.csv         : the mean and its displacement by the
                                    corrupted record (one arrow).
clustercentroid.png               : matplotlib preview (checking only).
"""

# /// script
# requires-python = ">=3.10"
# dependencies = ["matplotlib==3.10.7", "numpy==2.3.4"]
# ///

import json
import urllib.request
from pathlib import Path

import numpy as np
import matplotlib

matplotlib.use("Agg")
import matplotlib.pyplot as plt

OUT_DIR = Path(__file__).parent

report = []


def check(name, ok):
    report.append((name, bool(ok)))
    print(f"  [{'ok' if ok else 'FAIL'}] {name}")
Download the daily minimum and maximum temperature of 2024 at Krems (GeoSphere station 3805) or read the committed copy; 366 days, no missing value.
print("[B-data] daily minimum and maximum temperature at Krems, 2024")
URL = ("https://dataset.api.hub.geosphere.at/v1/station/historical/"
       "klima-v2-1d?parameters=tlmin,tlmax&station_ids=3805"
       "&start=2024-01-01&end=2024-12-31")
CSV = OUT_DIR / "clustercentroid_weather.csv"
try:
    with urllib.request.urlopen(URL, timeout=120) as resp:
        payload = json.load(resp)
    params = payload["features"][0]["properties"]["parameters"]
    records = [(stamp[:10], lo, hi)
               for stamp, lo, hi in zip(payload["timestamps"],
                                        params["tlmin"]["data"],
                                        params["tlmax"]["data"])]
    with open(CSV, "w") as fh:
        fh.write("date,tmin,tmax\n")
        for day, lo, hi in records:
            fh.write(f"{day},{lo},{hi}\n")
    print(f"    downloaded {len(records)} days")
except OSError as err:
    print(f"    download failed ({err}); reading the committed CSV")
    rows = CSV.read_text().strip().splitlines()[1:]
    records = [(d, float(a), float(b))
               for d, a, b in (r.split(",") for r in rows)]

check("[B-data] 366 days for 2024", len(records) == 366)
check("[B-data] no day is missing a temperature",
      all(lo is not None and hi is not None for _, lo, hi in records))
X = np.array([[lo, hi] for _, lo, hi in records], dtype=float)
m = len(X)


# ---- the three losses: how poorly a vector w stands in for a day x
def sq_euclid(x, w):
    return np.sum((x - w) ** 2, axis=-1)


def euclid(x, w):
    return np.sqrt(np.sum((x - w) ** 2, axis=-1))


def manhattan(x, w):
    return np.sum(np.abs(x - w), axis=-1)


def weiszfeld(pts, iters=1000, tol=1e-12):
    """Weiszfeld's fixed-point iteration for the geometric median,
    started from the mean; returns the point and the iteration count."""
    w = pts.mean(axis=0)
    for t in range(1, iters + 1):
        d = np.sqrt(np.sum((pts - w) ** 2, axis=1))
        if np.any(d < 1e-12):
            return pts[np.argmin(d)], t
        wts = 1.0 / d
        w_new = (wts[:, None] * pts).sum(axis=0) / wts.sum()
        if np.max(np.abs(w_new - w)) < tol:
            return w_new, t
        w = w_new
    return w, iters


def nearest(X, W, dist=euclid):
    """Index of the nearest centroid for every data point."""
    return np.argmin(np.stack([dist(X, w) for w in W], axis=1), axis=1)


def lloyd(X, W0, max_iter=500):
    """Lloyd's algorithm from the centroids W0; returns the centroids,
    the assignment, and the number of iterations until it stops."""
    W = np.array(W0, dtype=float)
    c = nearest(X, W)
    for t in range(1, max_iter + 1):
        W = np.array([X[c == j].mean(axis=0) for j in range(len(W))])
        c_new = nearest(X, W)
        if np.array_equal(c_new, c):
            return W, c, t
        c = c_new
    return W, c, max_iter
[B-data] daily minimum and maximum temperature at Krems, 2024
    downloaded 366 days
  [ok] [B-data] 366 days for 2024
  [ok] [B-data] no day is missing a temperature
Lloyd's algorithm with k = 2 from the colder and the warmer half of the days: cold days and warm days; at the fixed point each centroid is the mean of the days nearest to it, and the mean is the minimizer of the summed squared Euclidean distance over its cluster.
print("[B-lloyd] Lloyd's algorithm with k = 2: cold days and warm days")
order = np.argsort(X[:, 0])
W0 = np.array([X[order[: m // 2]].mean(axis=0),
               X[order[m // 2:]].mean(axis=0)])
W, c, n_iter = lloyd(X, W0)
cold, warm = sorted(range(2), key=lambda j: W[j, 1])
n_cold, n_warm = int(np.sum(c == cold)), int(np.sum(c == warm))
check(f"[B-lloyd] stops after {n_iter} iterations; cold days: centroid "
      f"({W[cold, 0]:.1f}, {W[cold, 1]:.1f}) for {n_cold} days; warm days: "
      f"centroid ({W[warm, 0]:.1f}, {W[warm, 1]:.1f}) for {n_warm} days",
      n_cold + n_warm == m and W[cold, 1] < W[warm, 1])
check("[B-lloyd] at the fixed point each centroid is the mean of the days "
      "nearest to it",
      all(np.allclose(W[j], X[c == j].mean(axis=0)) for j in range(2))
      and np.array_equal(nearest(X, W), c))
rng = np.random.default_rng(3805)
warm_days = X[c == warm]
cands = W[warm] + rng.normal(size=(2000, 2))
own = sq_euclid(warm_days, W[warm]).sum()
check("[B-lloyd] the mean has the smallest summed squared Euclidean "
      "distance over the warm days among 2000 nearby candidates",
      all(sq_euclid(warm_days, v).sum() > own for v in cands))
check("[B-lloyd] the deviations of the warm days from their mean sum to "
      "zero (the gradient of the summed squared distance vanishes)",
      np.allclose((warm_days - W[warm]).sum(axis=0), 0.0))
[B-lloyd] Lloyd's algorithm with k = 2: cold days and warm days
  [ok] [B-lloyd] stops after 2 iterations; cold days: centroid (1.5, 10.5) for 192 days; warm days: centroid (13.4, 26.1) for 174 days
  [ok] [B-lloyd] at the fixed point each centroid is the mean of the days nearest to it
  [ok] [B-lloyd] the mean has the smallest summed squared Euclidean distance over the warm days among 2000 nearby candidates
  [ok] [B-lloyd] the deviations of the warm days from their mean sum to zero (the gradient of the summed squared distance vanishes)
The nearest-centroid assignment equals the sign of a linear function of the feature vector; the boundary is the perpendicular bisector of the two centroids, and a new day is assigned by the same rule.
print("[B-assign] the nearest-centroid rule and its boundary")
w1, w2 = W[cold], W[warm]
a = w2 - w1
b = 0.5 * (np.sum(w2 ** 2) - np.sum(w1 ** 2))
linear = (X @ a <= b)                    # True: nearer to the cold centroid
check("[B-assign] a day is nearer to the cold centroid exactly when a "
      "linear function of its feature vector is at most a threshold",
      np.array_equal(linear, c == cold))
mid = 0.5 * (w1 + w2)
check(f"[B-assign] the boundary passes through the midpoint ({mid[0]:.1f}, "
      f"{mid[1]:.1f}) of the centroids and is perpendicular to their "
      f"difference", abs(mid @ a - b) < 1e-9)
# two points of the boundary line inside the plotting window
direction = np.array([-a[1], a[0]]) / np.linalg.norm(a)
ts = np.linspace(-60, 60, 12001)
line = mid + ts[:, None] * direction
inside = (line[:, 0] >= -9) & (line[:, 0] <= 23) & (line[:, 1] >= 0) \
    & (line[:, 1] <= 50)
seg = line[inside][[0, -1]]
new_day = np.array([5.0, 18.0])
new_c = int(nearest(new_day[None, :], W)[0])
check(f"[B-assign] a new day with features ({new_day[0]:.0f}, "
      f"{new_day[1]:.0f}) is assigned to the "
      f"{'warm' if new_c == warm else 'cold'} days; its distances to the "
      f"two centroids are {euclid(new_day, W[cold]):.1f} and "
      f"{euclid(new_day, W[warm]):.1f}",
      (new_day @ a <= b) == (new_c == cold))
[B-assign] the nearest-centroid rule and its boundary
  [ok] [B-assign] a day is nearer to the cold centroid exactly when a linear function of its feature vector is at most a threshold
  [ok] [B-assign] the boundary passes through the midpoint (7.5, 18.3) of the centroids and is perpendicular to their difference
  [ok] [B-assign] a new day with features (5, 18) is assigned to the cold days; its distances to the two centroids are 8.3 and 11.7
The warm cluster under three losses: mean, geometric median (Weiszfeld's fixed-point iteration), coordinate- wise median; each minimizes its own summed loss, and the geometric median satisfies the zero-sum condition on the unit vectors.
print("[B-losses] the centroid of the warm days under three losses")
mean_w = warm_days.mean(axis=0)
gm_w, n_weisz = weiszfeld(warm_days)
cwm_w = np.median(warm_days, axis=0)
centroids = {"mean": (mean_w, sq_euclid), "geometric median": (gm_w, euclid),
             "coordinate-wise median": (cwm_w, manhattan)}
for kind, (w, dist) in centroids.items():
    others = [v for k2, (v, _) in centroids.items() if k2 != kind]
    check(f"[B-losses] {kind} ({w[0]:.1f}, {w[1]:.1f}): smallest summed "
          f"loss over the warm days among the three centroids",
          all(dist(warm_days, w).sum() <= dist(warm_days, v).sum() + 1e-9
              for v in others))
unit = (warm_days - gm_w) / euclid(warm_days, gm_w)[:, None]
check(f"[B-losses] Weiszfeld's iteration stops after {n_weisz} iterations "
      f"at a point where the unit vectors to the warm days sum to zero "
      f"(norm of the sum {np.linalg.norm(unit.sum(axis=0)):.1e})",
      np.linalg.norm(unit.sum(axis=0)) < 1e-6)
check("[B-losses] the coordinate-wise median minimizes the summed absolute "
      "difference in each feature separately",
      all(np.abs(warm_days[:, j] - cwm_w[j]).sum()
          <= np.abs(warm_days[:, j] - v).sum() + 1e-9
          for j in range(2) for v in np.linspace(0, 40, 401)))
check(f"[B-losses] the three centroids of the warm days lie within "
      f"{max(euclid(mean_w, gm_w), euclid(mean_w, cwm_w)):.1f} degrees of "
      f"each other", max(euclid(mean_w, gm_w), euclid(mean_w, cwm_w)) < 2)
[B-losses] the centroid of the warm days under three losses
  [ok] [B-losses] mean (13.4, 26.1): smallest summed loss over the warm days among the three centroids
  [ok] [B-losses] geometric median (13.5, 26.0): smallest summed loss over the warm days among the three centroids
  [ok] [B-losses] coordinate-wise median (13.7, 26.1): smallest summed loss over the warm days among the three centroids
  [ok] [B-losses] Weiszfeld's iteration stops after 60 iterations at a point where the unit vectors to the warm days sum to zero (norm of the sum 2.6e-11)
  [ok] [B-losses] the coordinate-wise median minimizes the summed absolute difference in each feature separately
  [ok] [B-losses] the three centroids of the warm days lie within 0.3 degrees of each other
One warm day's maximum replaced by the sentinel 999.9: the mean moves by the displacement over the cluster size, the two medians far less.
print("[B-outlier] one warm day's maximum replaced by the sentinel 999.9")
SENTINEL = 999.9
i_bad = int(np.argmax(warm_days[:, 1]))        # the hottest warm day
bad = warm_days.copy()
shift_record = SENTINEL - bad[i_bad, 1]
bad[i_bad, 1] = SENTINEL
mean_b = bad.mean(axis=0)
gm_b, _ = weiszfeld(bad)
cwm_b = np.median(bad, axis=0)
moves = {"mean": euclid(mean_b, mean_w),
         "geometric median": euclid(gm_b, gm_w),
         "coordinate-wise median": euclid(cwm_b, cwm_w)}
check(f"[B-outlier] the mean moves by {moves['mean']:.1f} degrees, which "
      f"is the displacement {shift_record:.1f} of the record divided by "
      f"the cluster size {n_warm}",
      abs(moves["mean"] - shift_record / n_warm) < 1e-9)
check(f"[B-outlier] the geometric median moves by "
      f"{moves['geometric median']:.2f} degrees and the coordinate-wise "
      f"median by {moves['coordinate-wise median']:.2f} degrees, each "
      f"less than a tenth of the move of the mean",
      max(moves["geometric median"], moves["coordinate-wise median"])
      < 0.1 * moves["mean"])
[B-outlier] one warm day's maximum replaced by the sentinel 999.9
  [ok] [B-outlier] the mean moves by 5.5 degrees, which is the displacement 965.6 of the record divided by the cluster size 174
  [ok] [B-outlier] the geometric median moves by 0.03 degrees and the coordinate-wise median by 0.00 degrees, each less than a tenth of the move of the mean
EM for a Gaussian mixture model with k = 2 from the k-means centroids: at the fixed point each mean is the degree-of-belonging-weighted mean of all days; with degrees of belonging in {0, 1} the weighted mean is the plain mean.
def normal_pdf(A, mu, sig):
    d = A.shape[1]
    diff = A - mu
    inv = np.linalg.inv(sig)
    expo = -0.5 * np.einsum("ij,jk,ik->i", diff, inv, diff)
    return np.exp(expo) / np.sqrt((2 * np.pi) ** d * np.linalg.det(sig))


def em_gmm(A, mu, iters=5000, tol=1e-9):
    """EM for a GMM started from the means mu, equal probabilities and
    the covariance of the k-means clusters; returns the parameters, the
    degrees of belonging, and the iteration count."""
    k = len(mu)
    lab = nearest(A, mu)
    sig = np.stack([np.cov(A[lab == j].T) for j in range(k)])
    pk = np.full(k, 1.0 / k)
    for t in range(1, iters + 1):
        joint = np.stack([pk[j] * normal_pdf(A, mu[j], sig[j])
                          for j in range(k)])
        dob = joint / joint.sum(axis=0)
        wgt = dob.sum(axis=1)
        mu_new = (dob @ A) / wgt[:, None]
        sig = np.stack([(dob[j][:, None] * (A - mu_new[j])).T
                        @ (A - mu_new[j]) / wgt[j] for j in range(k)])
        pk = wgt / len(A)
        done = np.max(np.abs(mu_new - mu)) < tol
        mu = mu_new
        if done:
            break
    joint = np.stack([pk[j] * normal_pdf(A, mu[j], sig[j]) for j in range(k)])
    dob = joint / joint.sum(axis=0)
    return mu, sig, pk, dob, t


print("[B-gmm] EM for a Gaussian mixture model with k = 2")
mu, sig, pk, dob, n_em = em_gmm(X, W.copy())
check("[B-gmm] the degrees of belonging of each day sum to one",
      np.allclose(dob.sum(axis=0), 1.0))
weighted = (dob @ X) / dob.sum(axis=1)[:, None]
check(f"[B-gmm] after {n_em} iterations each mean is the degree-of-"
      f"belonging-weighted mean of all {m} days",
      np.allclose(mu, weighted, atol=1e-6))
d_cold = euclid(mu[cold], W[cold])
d_warm = euclid(mu[warm], W[warm])
check(f"[B-gmm] GMM means ({mu[cold, 0]:.1f}, {mu[cold, 1]:.1f}) and "
      f"({mu[warm, 0]:.1f}, {mu[warm, 1]:.1f}), {d_cold:.1f} and "
      f"{d_warm:.1f} degrees from the k-means centroids",
      max(d_cold, d_warm) < 5)
n_unsure = int(np.sum((dob.max(axis=0) < 0.8)))
check(f"[B-gmm] {n_unsure} of the {m} days have no degree of belonging "
      f"above 0.8", 0 < n_unsure < m // 2)
hard = np.stack([(c == j).astype(float) for j in range(2)])
check("[B-gmm] with degrees of belonging in {0, 1} the weighted mean is "
      "the k-means centroid",
      np.allclose((hard @ X) / hard.sum(axis=1)[:, None], W))
[B-gmm] EM for a Gaussian mixture model with k = 2
  [ok] [B-gmm] the degrees of belonging of each day sum to one
  [ok] [B-gmm] after 495 iterations each mean is the degree-of-belonging-weighted mean of all 366 days
  [ok] [B-gmm] GMM means (3.1, 12.4) and (14.2, 27.5), 2.5 and 1.5 degrees from the k-means centroids
  [ok] [B-gmm] 58 of the 366 days have no degree of belonging above 0.8
  [ok] [B-gmm] with degrees of belonging in {0, 1} the weighted mean is the k-means centroid
Every 18th day for panel (a), the warm days inside the window of panel (b), the centroids, the boundary line, and the preview figure.
print("[B-plot] thinned days, centroids, boundary")
idx = np.arange(0, m, 18)
with open(OUT_DIR / "clustercentroid_points_plot.csv", "w") as fh:
    fh.write("tmin,tmax,cluster\n")
    for i in idx:
        fh.write(f"{X[i, 0]:.1f},{X[i, 1]:.1f},{int(c[i] == warm)}\n")
check(f"[B-plot] every 18th day: {len(idx)} of the {m} days are drawn in "
      f"panel (a)", len(idx) == 21)
with open(OUT_DIR / "clustercentroid_boundary.csv", "w") as fh:
    fh.write("tmin,tmax\n")
    for p in seg:
        fh.write(f"{p[0]:.4f},{p[1]:.4f}\n")
with open(OUT_DIR / "clustercentroid_kmeans.csv", "w") as fh:
    fh.write("cluster,tmin,tmax\n")
    for j in (cold, warm):
        fh.write(f"{int(j == warm)},{W[j, 0]:.4f},{W[j, 1]:.4f}\n")
WIN = ((12.0, 15.5), (23.5, 33.0))        # the window of panel (b)
in_win = ((warm_days[:, 0] >= WIN[0][0]) & (warm_days[:, 0] <= WIN[0][1])
          & (warm_days[:, 1] >= WIN[1][0]) & (warm_days[:, 1] <= WIN[1][1]))
widx = np.flatnonzero(in_win)
with open(OUT_DIR / "clustercentroid_warm_plot.csv", "w") as fh:
    fh.write("tmin,tmax\n")
    for i in widx:
        fh.write(f"{warm_days[i, 0]:.1f},{warm_days[i, 1]:.1f}\n")
check(f"[B-plot] {len(widx)} of the {n_warm} warm days fall inside the "
      f"window of panel (b), {WIN[0][0]} to {WIN[0][1]} degrees by "
      f"{WIN[1][0]} to {WIN[1][1]} degrees; the window contains the "
      f"centroids and the moved mean",
      len(widx) <= 25 and all(WIN[0][0] <= w[0] <= WIN[0][1]
                              and WIN[1][0] <= w[1] <= WIN[1][1]
                              for w in (mean_w, gm_w, cwm_w, mean_b)))
rows = [("mean", 0, mean_w), ("geometric median", 0, gm_w),
        ("coordinate-wise median", 0, cwm_w), ("mean", 1, mean_b),
        ("geometric median", 1, gm_b), ("coordinate-wise median", 1, cwm_b)]
with open(OUT_DIR / "clustercentroid_centroids.csv", "w") as fh:
    fh.write("kindid,kind,corrupted,tmin,tmax\n")
    for kid, (kind, corr, w) in enumerate(rows):
        fh.write(f"{kid % 3},{kind},{corr},{w[0]:.4f},{w[1]:.4f}\n")
with open(OUT_DIR / "clustercentroid_shift.csv", "w") as fh:
    fh.write("tmin,tmax,dtmin,dtmax\n")
    fh.write(f"{mean_w[0]:.4f},{mean_w[1]:.4f},{mean_b[0] - mean_w[0]:.4f},"
             f"{mean_b[1] - mean_w[1]:.4f}\n")

fig, (ax1, ax2) = plt.subplots(1, 2, figsize=(9.6, 4.0))
for j, mk, lab in ((cold, "o", "cold days"), (warm, "s", "warm days")):
    sel = idx[c[idx] == j]
    ax1.scatter(X[sel, 0], X[sel, 1], marker=mk, facecolors="none",
                edgecolors="black", s=28, label=f"{lab} (every 18th day)")
ax1.scatter(W[:, 0], W[:, 1], marker="x", color="black", s=70,
            label="cluster centroids (means)")
ax1.plot(seg[:, 0], seg[:, 1], "k--", lw=0.9,
         label="boundary of the nearest-centroid rule")
ax1.set_xlim(-9, 23)
ax1.set_ylim(0, 50)
ax1.set_xlabel("morning minimum temperature (°C)")
ax1.set_ylabel("maximum daytime temperature (°C)")
ax1.set_title("(a) each day is assigned to its nearest centroid")
ax1.legend(frameon=False, fontsize=7.5, loc="upper left")
ax2.scatter(warm_days[widx, 0], warm_days[widx, 1], marker="s",
            facecolors="none", edgecolors="0.5", s=24,
            label="warm days inside the window")
for (kind, _, w), mk in zip(rows[:3], ("x", "^", "D")):
    ax2.scatter(w[0], w[1], marker=mk, color="black", s=60, label=kind)
ax2.annotate("", xy=mean_b, xytext=mean_w,
             arrowprops=dict(arrowstyle="->", ls="--", color="0.3"))
ax2.scatter(mean_b[0], mean_b[1], marker="x", color="0.5", s=60,
            label="mean after one record is replaced by 999.9")
ax2.set_xlim(*WIN[0])
ax2.set_ylim(*WIN[1])
ax2.set_xlabel("morning minimum temperature (°C)")
ax2.set_ylabel("maximum daytime temperature (°C)")
ax2.set_title("(b) the warm cluster's centroid under three losses")
ax2.legend(frameon=False, fontsize=7.5, loc="lower right")
fig.tight_layout()
fig.savefig(OUT_DIR / "clustercentroid.png", dpi=110)

n_ok = sum(ok for _, ok in report)
print(f"\n{n_ok}/{len(report)} checks pass")
if n_ok != len(report):
    raise SystemExit(1)
[B-plot] thinned days, centroids, boundary
  [ok] [B-plot] every 18th day: 21 of the 366 days are drawn in panel (a)
  [ok] [B-plot] 18 of the 174 warm days fall inside the window of panel (b), 12.0 to 15.5 degrees by 23.5 to 33.0 degrees; the window contains the centroids and the moved mean

24/24 checks pass
B-plot writes when the script runs